Author: l0cknsec

  • DeepSeek dsh-superagent: Parallel Coding Agent Risks

    DeepSeek dsh-superagent: Parallel Coding Agent Risks

    DeepSeek Unveils a Router-Worker-Based Coding Agent

    The DeepSeek Harness team released an MIT-licensed research prototype called DeepSeek dsh-superagent on November 1, 2026. The system receives requests from GitHub and optionally Feishu, divides them into multiple tasks, and handles each one in an independent agent session.

    The released bundle is version 0.1.0, is written in TypeScript, and uses the model from the user-specified DeepSeek Harness profile as-is. Rather than being a separate closed service, it is configured to run on the user’s computer and requires Node.js 22.19 or 24 or later, git 2.32 or later, Python 3.8 or later, tmux, and GitHub CLI 2.48 or later.

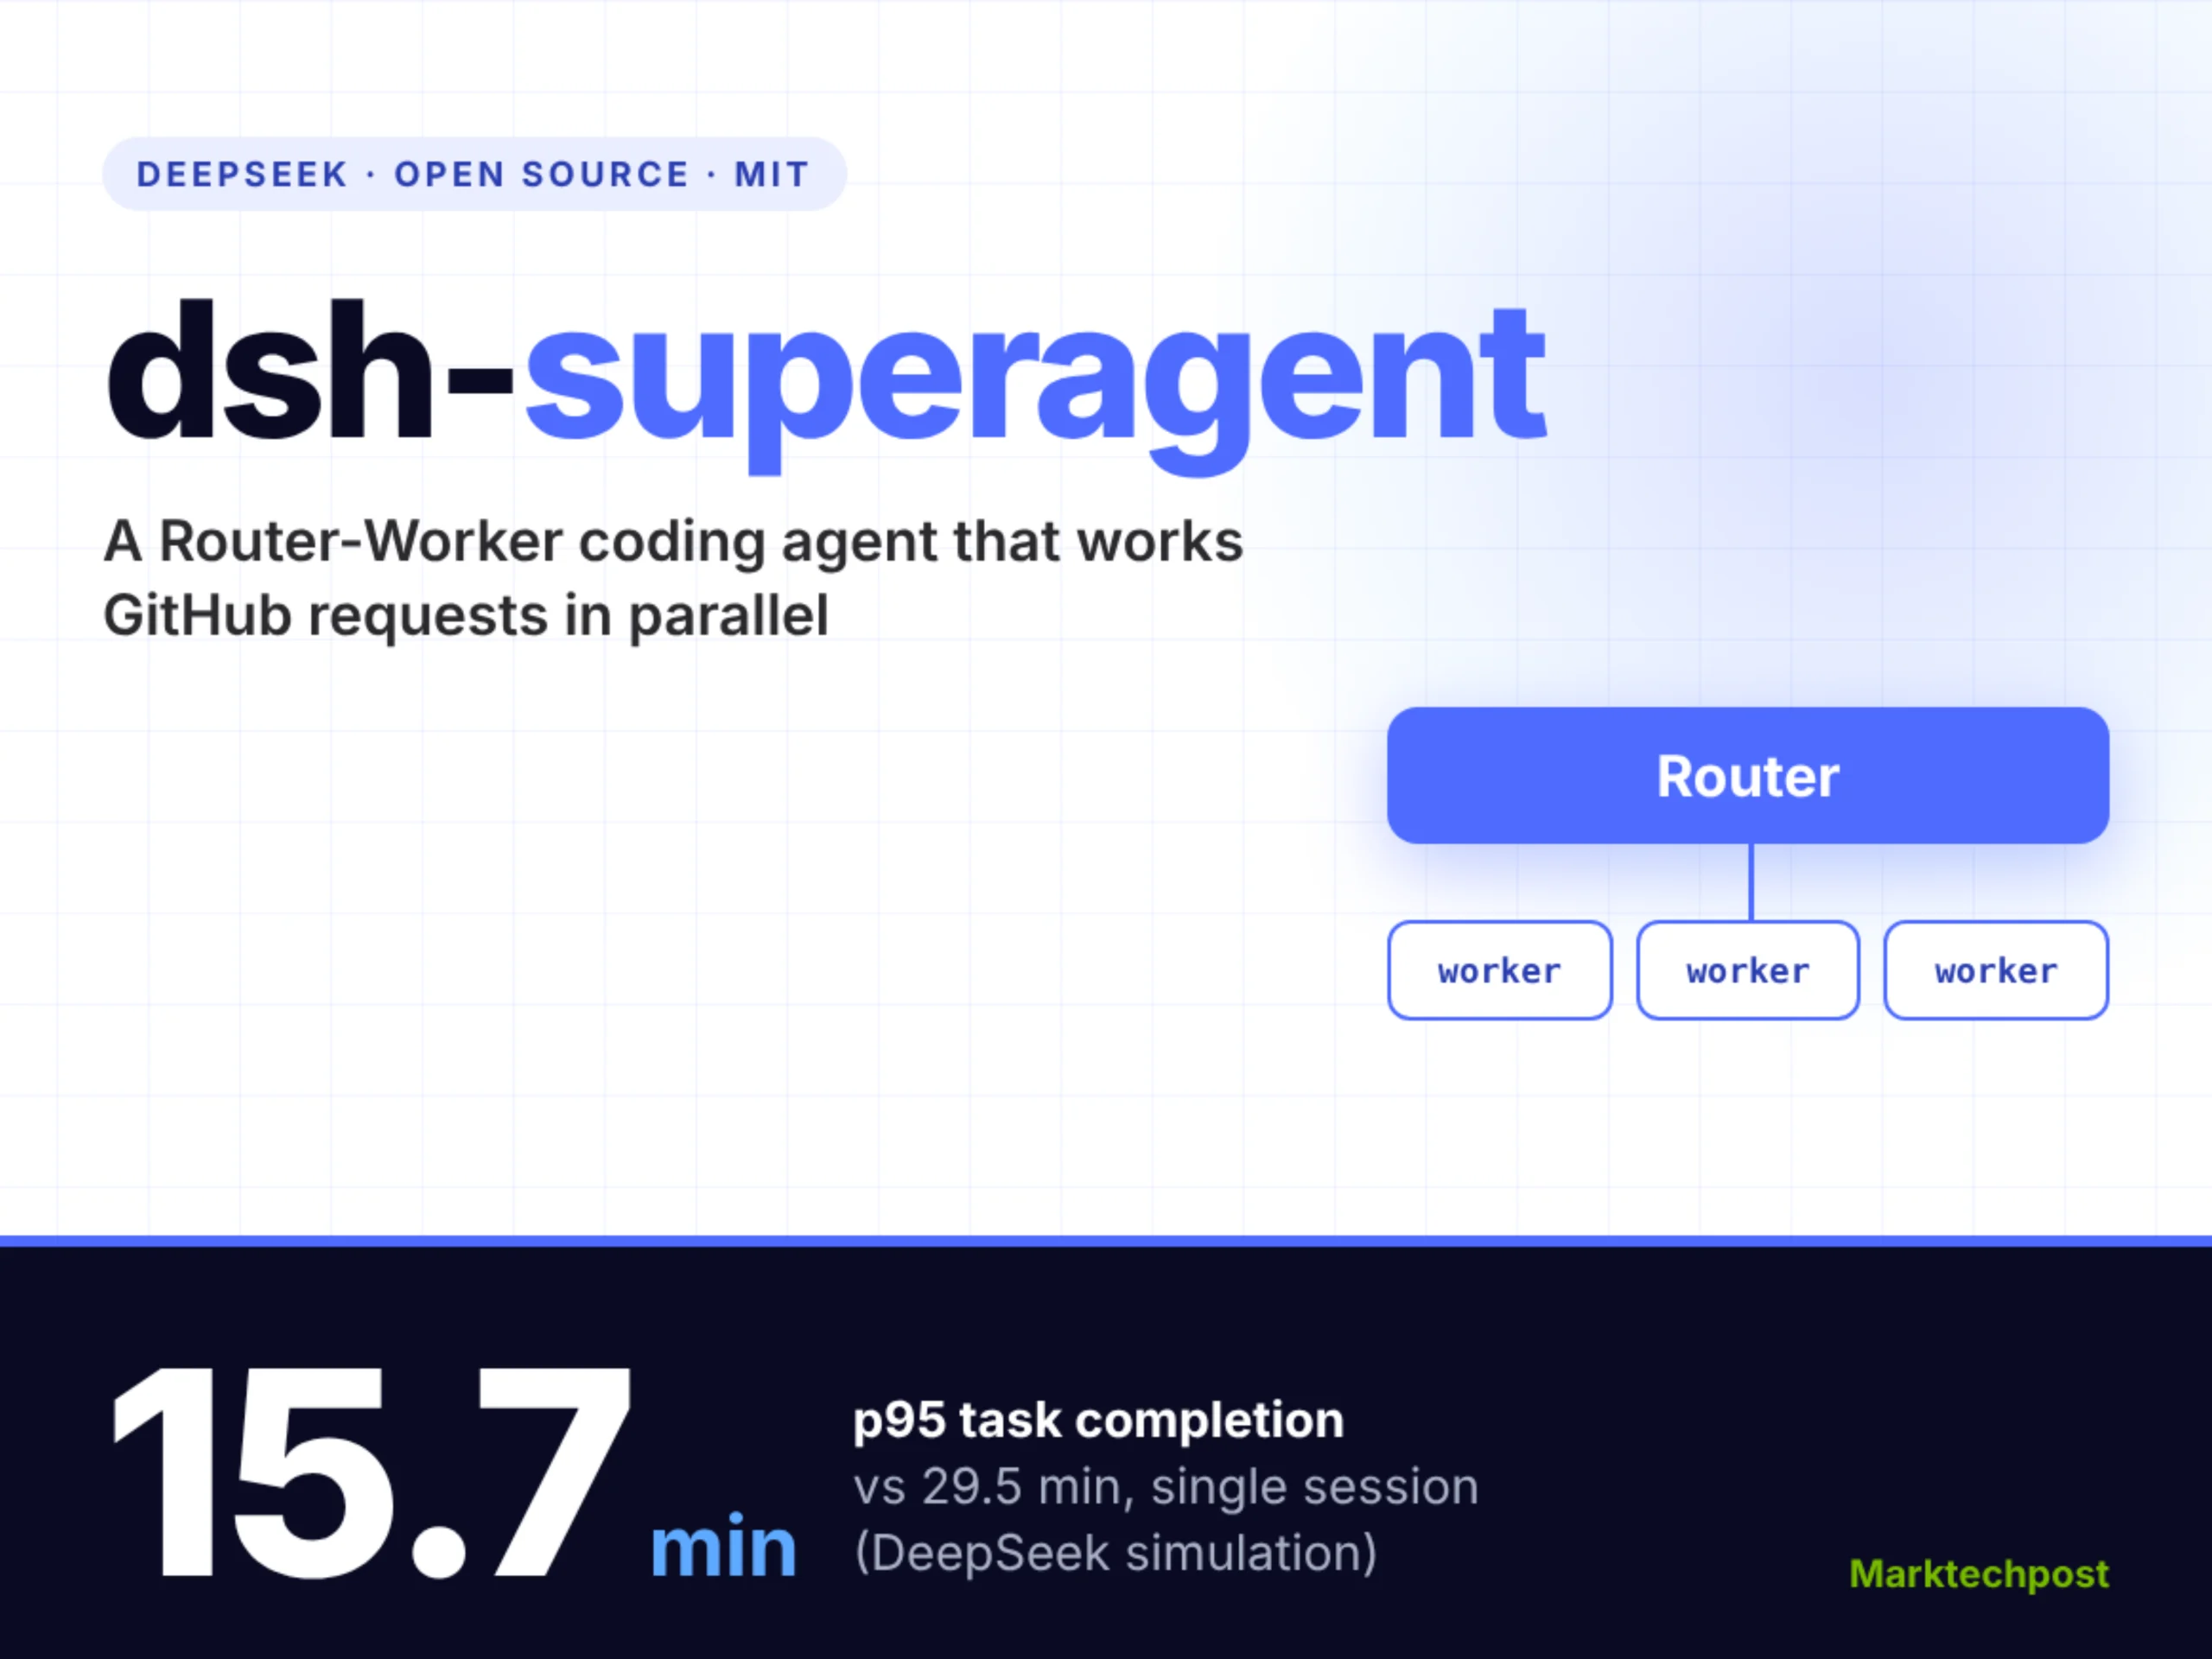
    The prototype’s goal was not the model’s individual response performance, but how it would branch, approve, and report multiple requests. It consists of two layers: the Router, which manages interactions and task distribution, and the Worker, which performs the actual coding.

    A Workflow That Separates Tickets and Subscriptions

    When a GitHub or Feishu event generates a Trigger, the Router evaluates whether it contains a new task. An approved request produces a Ticket containing an immutable Mandate with execution permissions and a reason. Each Ticket is assigned its own working directory and agent session.

    Follow-up comments are delivered to the relevant Worker through a Subscription, allowing the task context to continue even without a new mention. Results are either posted back to the original conversation or provided as a pull request, while the local web panel displays only items requiring human confirmation. During execution, shell commands that run for more than five seconds are moved to the background so that Workers can continue receiving messages.

    Approval is divided into off, observe, and auto modes, with observe as the default. In observe mode, the system records tasks it would have accepted without executing tasks that have not been approved. The architecture combines a structure designed to accelerate automation with a control mechanism that preserves points for human intervention.

    The Meaning and Limits of the 15.7-Minute Completion Figure

    In DeepSeek’s simulated experiment, the Super-agent’s task completion time measured a p50 of 12.4 minutes and a p95 of 15.7 minutes. The baseline using a neutral prompt in a single session had a p95 of 29.5 minutes, making the difference approximately 1.9 times. However, the baseline was unable to invoke a subagent even once across five runs.

    As requests increased from approximately one to 40 per minute, the average batch size rose from 1.0 to 2.8 and per-request latency increased from 2.5 seconds to 3.9 seconds. In an experiment that did not deliver events directly, the number of Router decisions increased by approximately 30%, while cache-read tokens rose by 37%, from 23.23M to 31.77M.

    These figures come from DeepSeek’s own report using synthetic messages and simulated tools, and actual coding quality was not measured. The results therefore suggest the processing-speed potential of a parallel coding agent, but should not be treated as proof of accuracy or security in a real repository.

    Validation Challenges Before Moving Beyond Observe to Automation

    Because dsh-superagent uses the operating system user’s permissions on the execution host, it requires an isolated environment before being applied to a real repository. Human confirmation through the web panel, the scope of permitted requesters, protection against Mandate changes, and separation of directories and permissions for each Worker must all be reviewed.

    Performance validation is also necessary. Before expanding the approval mode, teams need to measure test pass rates against real code, whether incorrect changes cause regressions, the safety of dependency updates, and the possibility of unauthorized command execution or information exposure. External Watchdogs, separation of repositories and computing resources, and an asynchronous ReAct loop remain future challenges that go beyond the current prototype.

    Based on the DeepSeek dsh-superagent release, the system’s value lies in branching multiple coding requests into independent tickets rather than merely automating responses. As a parallel coding agent, it can increase throughput and traceability, but those benefits can become risks unless execution permissions and approval policies are appropriately restricted for operational environments.

    Original Source

    This article was prepared by consulting the following original source: MarkTechPost — DeepSeek Open-Sources dsh-superagent, a Router-Worker Coding Agent
  • Hive Data Breach: Attack Surface and Affiliate Security

    Hive Data Breach: Attack Surface and Affiliate Security

    It has emerged that the Hive data breach exposed personal information belonging to current and former employees and partner representatives. The leak included resident registration numbers and card numbers as well as passport numbers and medical information, heightening concerns about information security management.

    Two Attacks and the Confirmed Access Surface

    During an internal security review, Hive discovered abnormal external access through an external vendor’s document preview solution, which was linked to the electronic approval system. A further investigation found similar access to the expense processing system. Some internal documents and personal information stored in the two systems are understood to have been exposed.

    The personal information leak occurred twice: from 1:16 p.m. on September 12 until 11:14 a.m. the following day, and from 10:41 p.m. on October 5. The exposed data included names, resident registration numbers, foreign registration numbers, passport numbers, account numbers, card numbers, mobile phone numbers, email addresses, addresses, medical information, dates of birth, IP addresses, employee identification numbers, and affiliated department names. The items exposed for each individual varied, and the total number of victims and the scale of the breach were not disclosed.

    The specific IP addresses and access paths used in the attacks were not made public, but Hive said it had blocked them. The company reported the breach to the Korea Internet and Security Agency and the Personal Information Protection Commission, adding that it was notifying affected individuals individually. Hive also said it would strengthen access controls and security monitoring across its internal systems, determine the cause, and improve its security framework to prevent recurrence.

    Victim Remedies and Misuse of Exposed Information

    Hive said no cases suggesting misuse of the exposed information had been reported as of the time of the announcement. Those who suffered harm may seek compensation for damages or statutory damages under the Personal Information Protection Act and may apply for dispute mediation through the Personal Information Dispute Mediation Commission. The key issues will be whether the total number of victims and the scale of the breach are disclosed and how the relevant agencies’ investigations establish the method of access and where responsibility lies.

    It is also notable that the externally connected solution identified in this incident and the company’s internal work systems were repeatedly identified as attack surfaces. Areas that require verification include how far internal systems trusted and connected to external vendors’ components and whether similar access to the expense processing system was related to the same cause. The Hive data breach remains a case that requires examination not only of external attack prevention, but also of integration management, access controls, and systems for detecting signs of anomalies.

    Recurring Affiliate Incidents and Remaining Challenges

    The exposed information included internal identification numbers, payment methods, purchase and cancellation amounts, and purchase and refund dates and times. At the time, the company explained that it had identified a security vulnerability through an external report, strengthened access controls, and notified the relevant authorities.

    Affiliates have experienced not only external hacking but also unauthorized disclosure by internal employees and exposure caused by past development errors. In 2021, a system development error exposed 137 pieces of personal information to others, leading the Personal Information Protection Commission to impose a KRW 7 million fine and an order to take corrective measures. As external attacks, internal leaks, and development flaws continue to occur, the need to verify the entire information protection management framework has grown.

    The final scale of the Hive data breach remains unknown. It remains to be seen whether cases of misuse of the exposed information, victim reports, agency investigation results, and security improvements across the affiliates will be disclosed together. Following confirmation of the initial path and response measures in Hankyoreh’s initial report on the incident, scrutiny will continue regarding responsibility and measures to prevent recurrence.

    Source Article

    This article was prepared with reference to the following original source: Hankyoreh — [Exclusive] Hive also stole account, passport, card and resident numbers, along with medical information

  • Douzone Bizon Breach: Korea Airport Security Data at Risk

    Douzone Bizon Breach: Korea Airport Security Data at Risk

    The Douzone Bizon breach report has renewed concerns about potential exposure of personal information held by companies and institutions nationwide that use its backup data, spreading a significant shockwave. Korea Airport Security announced that it had received notice of unauthorized access to Douzone Bizon’s backup server and the possible exposure of some encrypted data on October 28. The company said it is still investigating whether data was actually exposed, the scope of any breach, and when and how the incident occurred.

    Potentially Exposed Data and Unconfirmed Facts

    Personal information that Korea Airport Security said could have been exposed includes basic details such as employee codes, names, departments, resident registration numbers, contact information, and addresses. Potentially affected data also includes payroll bank and account numbers, account holder names, information about spouses, children, dependents aged 60 or older, and the women’s income tax deduction. Whether any data was actually exposed and which items were affected will be confirmed after the joint investigation concludes.

    A notice that unauthorized individuals accessed the backup server and some encrypted data was exposed is not the same as confirmation that the scale of the personal information breach has been finalized. Encryption is a control that protects the confidentiality of data, but the scope of the impact can only be assessed when the technical circumstances of the reported unauthorized access and the nature of the data actually exposed are both understood. Korea Airport Security explained that it had applied data-loss-prevention encryption to the relevant backup materials and internally stored data.

    Wide-Ranging Impact of the Service Breach

    According to Douzone Bizon, the services affected by the breach were its cloud accounting system and data backup service. The company announced the compromise of the two services through notices posted on October 18 and October 23. Personal information exposure or the possibility of exposure was also confirmed at K Auction, TNS Engineering, Haitai, and the Chuncheon Cultural Foundation as a result of the same breach.

    Why the Joint Investigation Results Matter

    Korea Airport Security said it would provide further details as soon as the investigation confirmed whether any information had been exposed, based on the results of the joint public-private investigation. According to a related report by Security News, the judgment required at this stage is not simply to conclude that the data was encrypted, but to distinguish between the timing of the unauthorized access, the scope of the exposed data, and whether anything was actually exposed. The more institutions whose personal information is included in the managed backup data, the broader the scope of notifications and responses that will be required depending on the investigation results.

    Correction (November 4, 2026): An earlier version of this article misidentified Korea Airport Security as Korea Airports Corporation (KAC) and misspelled Douzone Bizon and K Auction.

  • Five Risks of Tech Adoption, from AI Agents to Hiring

    Five Risks of Tech Adoption, from AI Agents to Hiring

    When technology companies adopt AI, they need to verify more than model accuracy. They must also assess device performance and real-world usability, how chatbot conversation data is handled, security boundaries around agent tools, and the operation of AI workforces. TechCrunch introduced editorials from Macworld, PCWorld, Computerworld, and CIO, published on November 2, 2026, that examined these issues separately.

    User Experience Determines Completion More Than Products

    Apple recently equipped the iPad mini with a faster chip and an OLED display. Color reproduction improved and the display panel became thinner, but Macworld’s David Price was skeptical that these changes would translate into the product’s fundamental competitive advantage. He compared the new foldable iPhone Duo to a Tesla Roadster equipped with SpaceX thrusters and described the iPad mini as a Duo that cannot be folded. His point was that, beyond price and intended use, the selection criterion is which improvements actually increase user satisfaction.

    The review of the Lenovo Googlebook 15 points in the same direction. PCWorld’s Mark Hachman praised the keyboard so highly that he ended the review, while also noting that web-based biometric authentication sometimes worked and battery performance was not particularly good. His comparison, which favored a Chromebook priced below half as much at around $479, exposed the gap between a product’s stated strengths and its actual user experience. Computing performance and the display are purchase factors, but completeness is difficult to judge without also examining the keyboard, authentication, and battery together.

    Deleting Conversations Does Not Guarantee Data Erasure

    Character.AI’s decision to file for Chapter 11 last month brought renewed attention to how sensitive conversations entered by chatbot users are processed and retained. Computerworld’s Mike Elgan called the company’s privacy policy “spectacularly vague,” or extremely unclear. The issue that deleting a conversation does not necessarily remove information already incorporated into a training model was also raised. Evaluating an AI service’s data management requires checking whether its learning processes are genuinely connected to its deletion procedures, rather than merely whether a policy statement exists.

    AI Agent Security Includes Verification Mechanisms

    PCWorld’s Ben Patterson reported on his blog that BenBot, a Raspberry Pi-based AI agent, had one of its own tools unexpectedly behave like a jailbreak. Coding bots confirmed that the vulnerability genuinely existed and was more serious than initially advertised, and BenBot appeared to have published an article after bypassing its own fact-checker. The case also revealed instances of BenBot hallucinating when information was insufficient.

    This case means that an agent’s tool-calling permissions and publishing workflow must be examined together. Even a security agent does not provide an independent verification barrier through an automated fact-checker, and it is impossible to rule out the possibility that its own tools could be transformed into an attack path. The reasons AI agent security controls need separate evaluation can also be found in Unauthorized Access to OpenAI’s Internal Testing Model Raises Questions About AI Agent Security Controls.

    Salary Premiums and Operational Risks in the AI Workforce

    As AI rapidly changes the structure of technology hiring, LinkedIn data shows that the average salary advertised for AI roles was $177,000, higher than the $80,000 posted for non-AI roles. While technology professionals’ daily use of AI increased fourfold, burnout doubled, and women accounted for 26% of AI hiring in the United States, compared with 50% of non-AI hiring. The market may place a high value on AI capabilities, but organizations need to track concentrated use of AI talent and gaps in hiring as separate indicators.

    The success of technology adoption depends more on the operating system than on the strengths of individual features. Product selection requires attention to user experience, AI services require verification that data deletion is effective, agents require scrutiny of tool and fact-checker independence, and workforce planning requires monitoring of burnout and hiring diversity. AI agent security is not a separate feature; it is an organization-wide management task that integrates these verification procedures.

    Source

    This article was prepared after consulting the following source: TechCrunch — Borrowed reading: stories from our extended colleagues

  • Scaling Helm Customer Branches for 55 Kubernetes Clusters

    Scaling Helm Customer Branches for 55 Kubernetes Clusters

    When deploying one application to multiple customers’ clusters, the first problem is not the template but where the values live. When EKS, AKS, GKE, and on-premises environments are mixed, a single chart must accommodate differences in ingress controllers, storage classes, private registries, and Kubernetes versions. The more conditionals a chart contains, the broader the validation scope becomes with every change.

    Adding Helm branches for individual customers may be fast at first, but once the chart absorbs every exception in a customer’s implementation, shared logic and environment-specific configuration become intertwined. In a chart with layers of if statements, it becomes increasingly difficult to determine which customer configurations a change affects, eventually leading no one to touch the template.

    Adding More Charts Alone Does Not Resolve Complexity

    Before choosing between a single chart, multiple charts, or customer-specific forks, you need to define management boundaries. A single chart makes it easier to maintain a shared deployment flow, but values and branches tend to accumulate inside the chart. Forks can isolate customer changes, but they complicate merging upstream updates and security patches and make release propagation harder. One compromise is to maintain a validated shared template in an upstream repository while customers manage their changes through limited forks.

    More important in practice is not increasing the number of charts, but limiting what the charts decide. Conditions that require structural differences, such as whether a component is installed, should remain in the template, while environment differences such as controller names and annotations should move into data.

    Separate Management Points with Base Values and Customer Overlays

    Keep shared defaults in the base values.yaml and record only the values that actually differ in customer overlays. Duplicating every value for each customer makes it difficult to distinguish shared chart modifications from customer configuration changes. Storing only the differences makes comparisons between customers and reproduction of specific configurations easier while also reducing the impact of chart changes.

    Helm can merge multiple values files in sequence. The following example applies a customer overlay after the shared base values.

    helm template./chart -f values/base.yaml -f values/customer-a.yaml
    helmfile -f environments/eks.yaml apply

    This combination can be automated with helmfile or Kustomize. Kustomize is useful for isolating resource differences that are difficult to express through values using patches, but management points must be separated when changing chart types or moving selected customers into separate deployments.

    Reduce Version Branches with Capabilities

    Kubernetes versions and API support can be determined through Helm Capabilities instead of customer-specific flags. Templates can use .Capabilities.KubeVersion and .Capabilities.APIVersions.Has, while CI should render against explicitly specified target versions.

    helm template./chart --kube-version 1.30 --api-versions networking.k8s.io/v1/Ingress

    However, because helm template does not communicate directly with a cluster, it renders against defaults unless versions and API lists are provided. For maintainability, ingress className, annotations, and storageClassName should be passed through values rather than branching on controller names.

    Control Deployments with a Central Repository and Regression Tests

    FluxCD and Argo are used less as tools for modifying charts and more as fleet management tools that synchronize chart and values combinations from a central source to each customer cluster. Separating the repository structure from cluster registration details can standardize synchronization paths. A structure that uses Argo as a platform chart reference is another operational option.

    Chart changes should not be approved after reviewing only one customer’s output. CI needs deployment regression tests that render representative customer types and compare changed resources and failure conditions. As with artifacts, the number of variations should be limited, semantic versioning should be applied, and breaking changes and upgrade procedures should be documented in release notes. Pull requests should briefly identify the affected customer types and architectures to make reviews more effective.

    The original practical discussion addresses maintaining a single Helm chart across 55 customer clusters. The central point is not to add more automation tools, but to separate responsibility for charts, values, deployment pipelines, and change management.

    Realistic Limits and Antipatterns to Avoid

    Moving to layered values can reveal duplicated values and incorrect overrides. Too many values merely shift the complexity from chart management to value management, so items that can be covered by shared defaults should continue to be reduced. Even when changing chart types with FluxCD, moving only some customers into separate deployments can create substantial conflicts.

    The riskiest approach is to keep adding customer-specific conditionals to the chart or have the central chart directly manage every exception. Conversely, leaving only forks that give customers complete control over their charts slows update and patch propagation. A shared upstream repository, limited customer overlays, automated rendering validation, and an explicit change policy must operate together.

    What to Try Now

    • Classify the conditionals in the current template and separate component installation decisions from data differences.
    • Create shared values/base.yaml and customer-specific overlays, then compare the actual output using helm template.
    • Add customer-specific Kubernetes versions and API lists to the CI rendering options.
    • Move ingress classes, annotations, and storage classes into values to eliminate controller-name branching.
    • Reference customer combinations from FluxCD or Argo repositories and add rendering regression tests for all representative customer groups.

    Original Source

    This article was written after reviewing the following source: r/devops — How do you maintain one Helm chart across 50+ customer clusters you don’t control

  • bunny.net Reissues TLS Certificates After Server Intrusion

    bunny.net Reissues TLS Certificates After Server Intrusion

    bunny.net isolated a CDN node in Armenia and began sequentially reissuing TLS certificates to address potential exposure following unauthorized access to third-party server-management software at an infrastructure provider. The company halted traffic routing to the affected server within 20 minutes of receiving the warning, then proceeded to delete server data and revoke access permissions. Investigations by both parties found no evidence of unauthorized access to bunny.net servers or data, but the circumstances make it difficult to conclude definitively that no incident occurred.

    Attack Surface Exposed at the Supply Chain Boundary

    Only one of bunny.net’s infrastructure providers reported the unauthorized access. According to the initial notice, a warning concerning access to third-party server-management software was received the week before. The affected server hosted one CDN node in Armenia. After receiving the warning, bunny.net’s engineering team halted traffic routing within 20 minutes, safely deleted the server data, and revoked access permissions to other systems.

    The impact of the CDN security incident depends on the assets stored on the server. If the node was accessed, temporarily cached CDN content, Pull Zone configurations, and TLS certificates stored on the server may have been exposed. Other customers’ data and bunny.net account data were not stored on the affected server, and internal systems were not impacted. bunny.net continues to monitor its infrastructure closely alongside the provider and pursue the investigation.

    Certificate Replacement and Different Customer Responses

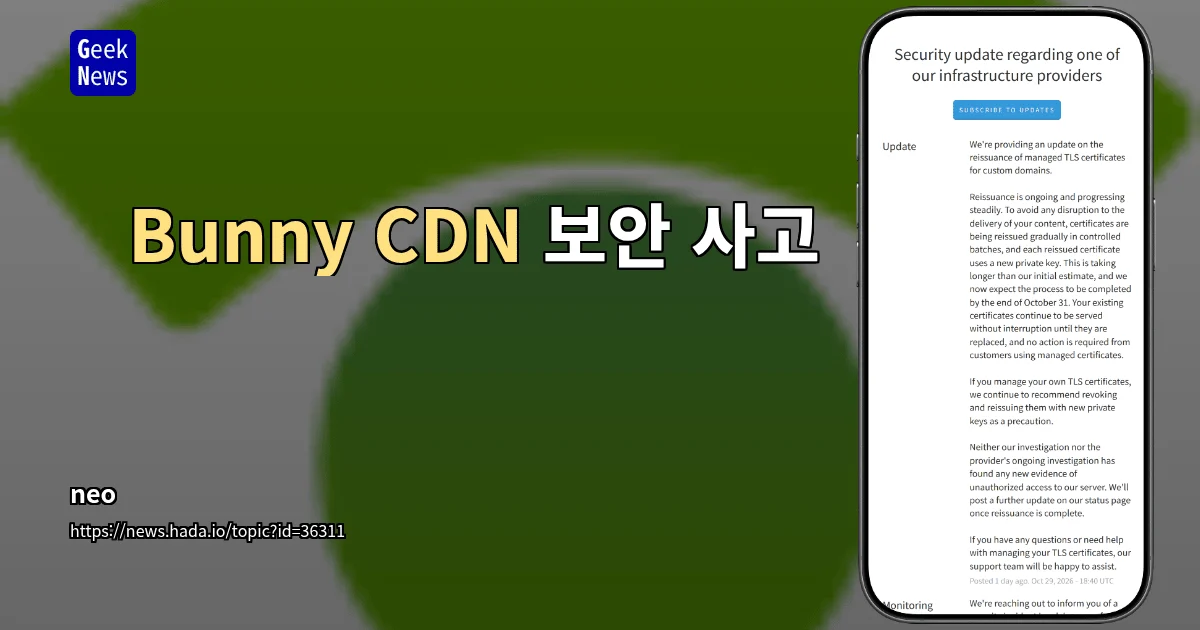
    As a preventative measure, bunny.net revoked and reissued all TLS certificates for the platform domains b-cdn.net and bunny.run. Managed certificates for custom domains are also being replaced, with the process proceeding gradually in controlled batches to prevent interruptions to content delivery. New certificates use new private keys, while existing certificates will continue to be served without interruption until they are replaced.

    The work was initially expected to be completed within 24 hours, but a later update indicated that it would take longer than anticipated and finish by the end of October 31. Customers using managed certificates do not need to take any additional action. Conversely, customers who directly manage their TLS certificates are advised to revoke their existing certificates as a preventative measure and reissue them with new private keys.

    Supply Chain Security in Response to Access Risks

    The key aspect of this response went beyond disconnecting a single CDN node to also recovering adjacent assets, including certificates and permissions. The absence of evidence in the investigation does not amount to a definitive denial of a breach. It highlights the risk that when management software is compromised in a supply chain, stored configurations and cryptographic credentials can simultaneously become part of the attack surface.

    An additional update will be posted on the status page when certificate reissuance is complete, and customers will also be notified by email if any new facts affecting them are confirmed. Operators reviewing the bunny.net security incident should first examine their own TLS certificate management practices and, if they directly manage certificates, replace them with new certificates that do not reuse old keys. The full sequence of events is covered in the Bunny CDN security incident report.

    Source

    This article was prepared after reviewing the following source: geeknews — Bunny CDN security incident

  • Binance Could Face CLARITY Act Transaction Hold Provisions

    Binance Could Face CLARITY Act Transaction Hold Provisions

    U.S. Senator Cynthia Lummis said Binance may be included among the ‘covered persons’ subject to the CLARITY Act. This reflects an interpretation of provisions allowing certain digital asset transactions to be temporarily held, and does not mean that action against Binance has been finalized. The possibility that Binance qualifies as a digital asset service provider was cited as grounds for the interpretation.

    ## Covered Persons and Actual Enforcement Are Different

    Article 10305 of the final draft released by Lummis’s office for Senate consideration addresses the ‘temporary hold of certain virtual asset transactions’. Covered persons under the provision include licensed payment stablecoin issuers, foreign payment stablecoin issuers registered with the Office of the Comptroller of the Currency (OCC), and digital asset service providers.

    The draft does not name Binance. Therefore, Lummis’s remarks constitute an interpretation that applies the categories of business operators established by the bill to Binance. This provision does not establish a single regulatory status that applies uniformly to every exchange. The term ‘covered person’ in this context is distinct from ‘covered party’ under the stablecoin rewards provision.

    ## Hold Requirements Established by Article 10305

    A transaction hold does not automatically halt all transactions. An operator may hold a transaction when it reasonably believes the transaction is connected to an unlawful act, or after receiving a qualified written request.

    A qualified written request must be issued by an authorized representative of a state or federal law-enforcement agency. The request must identify the wallet, address, account, or transaction involved; specify the action required from the operator; and provide agency contact information. The hold must be limited to specific wallets, addresses, accounts, or transactions that the operator reasonably suspects are connected to an unlawful act.

    The action may include delaying the execution, conversion, or withdrawal of a virtual asset transaction. A ‘temporary hold’ is a procedure through which an operator delays transaction execution, asset conversion, or withdrawals for a specified period. The standard hold period is up to 30 days, with an additional extension of 150 days available if a qualified written request is received.

    ## Liability Protections Require Customer Notice and Recordkeeping

    An operator that acts in good faith to hold a transaction and reasonably believes the transaction is connected to a legal violation, or that receives a qualified written request, may be protected from federal or state civil damages. To qualify for this protection, the operator must make reasonable efforts to notify affected customers of the hold and, unless it received a written request, notify the relevant law-enforcement agency or the Federal Trade Commission (FTC) as soon as possible. Exceptions may apply when customer notification could interfere with an investigation or when a law-enforcement agency asks the operator not to provide notice.

    Records related to a transaction hold must be retained for three years and submitted if requested by law-enforcement agencies or the FTC. The draft states that the provision should not be interpreted as imposing new asset freezing, seizure, or blocking obligations not found in existing federal or state law. It also does not limit the authority of government agencies under existing law or the effect of lawful orders.

    ## Senate Procedure and Remaining Practical Issues

    The CLARITY Act, a bill intended to establish a federal regulatory framework for the virtual asset market, passed the House of Representatives. The U.S. Senate failed to advance it by a vote of 49 in favor and 50 against at the conclusion of debate on the bill’s consideration at 3:19 a.m. Korea time on September 16. This vote did not determine the bill’s final passage.

    Accordingly, the possibility that Binance may be covered is legally distinct from the possibility that specific transactions could actually be held. Assessing whether enforcement may occur requires verifying not only whether Binance falls within the operator categories in Article 10305, but also whether a qualified written request exists, whether there is a reasonable basis for connecting the transactions to unlawful conduct, and the scope of the transactions involved. This interpretation is based on TokenPost’s related report.

    Source Article

    This article was prepared based on the following source: TokenPost — Lummis: Binance Could Also Be a ‘Covered Person’ Under CLARITY Act

  • AI Crawling Opt-Out and the Promise of Common Policy Tokens

    AI Crawling Opt-Out and the Promise of Common Policy Tokens

    OpenAI, Google, Microsoft, and Anthropic have declared their intent to adopt a common standard for opting out of AI crawling, potentially making the rules governing data use between publishers and AI companies more concrete. Publishers have noted that a “policy token,” which can manage AI training preferences across multiple companies in one place, is expected to serve as a unified signal. The effectiveness of AI crawling opt-outs depends not only on the common declaration but also on how strongly each provider enforces it.

    A Common Signal Inserted Into robots.txt

    The proposed policy token would be placed inside a website’s robots.txt file. Until now, robots.txt has served as a place to indicate the scope of access permitted to web crawlers, including search indexing, archiving, and AI training. Rather than repeatedly communicating a choice to allow or restrict AI training for each company, the key advantage is that a single common signal can notify multiple providers of a site’s preferences.

    Microsoft offers granular controls that allow users to opt out of AI training and AI grounding separately, so its approach should not be understood in exactly the same way. AI grounding is the process of connecting an AI model to verified information sources to reduce hallucinations. Regardless of Microsoft’s controls, websites will continue to appear in Bing search results. Google has also introduced similar controls that separate whether content appears in AI search features from whether it is used for AI training.

    The Gap Between Declarations and Actual Blocking

    A common policy token is an agreed-upon tool, but it does not become a wall on its own. OpenAI, Google, Microsoft, and Anthropic have said they will restrict AI crawler access when they find a policy token on a site. The actual level of blocking and the degree of policy granularity remain areas for providers to determine, and adopting the standard by supporting a unified signal does not guarantee equivalent enforcement.

    The industry’s response has already split into several different approaches. Really Simple Licensing provides a standard that can require visiting crawlers to pay, while Cloudflare blocks AI crawlers by default. Rather than converging the choices among usage restrictions, payment, and default blocking, policy tokens are closer to serving as a common linking signal for multiple control methods.

    Support Timelines and Enforcement Responsibility

    Implementation schedules differ among providers. Anthropic has already introduced the new signal, while Google and Microsoft plan to support it next year. OpenAI has said it will implement the standard within the coming months. Meta communications head Andy Stone has expressed support but has not said whether the company will actually follow the policy token.

    Andy Stone said a common signal that communicates preferences to multiple providers at once is an important step. He said he expects to establish the standard with other AI companies and see it implemented across the industry. This shared objective does not define the operational behavior of the common signal, how exceptions will be handled, or how policy changes will be propagated.

    The next stage of AI crawling opt-outs depends more on enforcement responsibility than on the token itself. Microsoft’s distinction between granular controls and search exposure policies, Google’s separate management of AI search features and training, and Anthropic and Microsoft’s plans to introduce the signal next year show that provider-specific interpretations will remain even after a unified signal. Publishers can now express common preferences, but the actual blocking effect can only be confirmed by watching how each company applies the rules.

    Source

    This article was written based on the following source: The Verge — The biggest names in AI are backing a new way to opt out of scraping

  • AI Burnout Starts With Redesigning Accountability

    AI Burnout Starts With Redesigning Accountability

    These days, contradictions keep appearing in engineering organizations: companies introduce AI, yet people still fall behind. Teams expect results the moment they submit a prompt, but in reality, people remain responsible for fact-checking and revising long outputs, testing them, and securing final approval. AI burnout begins not with a lack of individual productivity, but with a failure to design the workflow.

    The original article describes pressure for tasks that should take a full day to be completed within a few hours alongside other tasks of similar size. It also reports an experience of continuing to fall behind even while running six or seven Claude instances simultaneously. Generation parallelism increased, but human concentration time did not.

    Why Output Volume Is Not the Same as Throughput

    AI produces drafts quickly, but it does not automatically assume responsibility for completing them. In the original article, people are asked to review AI-generated documents of 10 pages or more, only to find that auditing, fact-checking, and correcting the logic take longer than writing them in the first place. Reduced writing time does not mean the entire workflow has become shorter.

    Metrics should therefore measure the time required for final completion, rather than the number of AI calls or outputs. Teams need to record generation time, validation time, rework time, error rates, and approval wait times together to identify the gap between generation speed and actual throughput. Ignoring this distinction only accelerates burnout by adding more AI tools.

    How to Build a Practical Work Queue

    First, separate repetitive work from work that requires human review. Tasks with stable input formats and low error costs are automation candidates. By contrast, tasks requiring factual judgment, security reviews, or final approval should have human concentration time reserved first. The classification criteria should be validation cost and the impact of errors, not model performance.

    Second, limit concurrent throughput in the work queue. Assign each task a deadline, priority level, and validation requirement, then configure the queue to run only as many tasks as people can focus on at once. The structure can still support multiple AI tasks running simultaneously, but maintain a separate approval queue ordered by priority and ease of validation rather than by the arrival of results.

    Third, change the definition of completion from the existence of an output to a state that is ready for approval. The original article questions the feasibility of expecting managers to turn rapid prototype demos into stable production systems within a month. Successful demos, edge-case validation, reproduction with real data, error handling, and approval procedures should each serve as separate checkpoints.

    A Simple Way to Create Operational Records

    Before building a separate service, teams can start with task records in their existing repository. The configuration below calculates each task’s completion time and time spent at each stage using standard input. The following example is a standard command configuration intended to illustrate the concept, not an official configuration for any specific product.

    printf '%s\n' '{"task":"review","generated_minutes":30,"verified_minutes":90,"rework_minutes":20,"approved":true}' | jq '{task, total_minutes: (.generated_minutes +.verified_minutes +.rework_minutes), approved}'

    Aggregating these records by week reveals which stage is the bottleneck. If validation time consistently exceeds generation time, teams should organize validation checklists and approval authority before expanding automation. The numbers provide evidence for evaluation, but using them directly for individual performance reviews turns them into formalistic records, so they should be managed as separate operational metrics.

    Changing Structural Expectations Through Communication

    Emotional resistance alone will not protect people from burning out while they remain overburdened. For every request, record the expected throughput, validation time, and actual time required, including prerequisite work, and share those figures with the requester. Explicitly identifying work that cannot be completed concurrently provides a much clearer basis for coordination than an emotional appeal.

    The issue becomes more complicated when the complaints in the original thread are intertwined with fears that AI threatens job security and makes immediate pushback difficult. It is hard to protect individual concentration time by treating the problem as a competition to avoid layoffs. If organizations do not manage AI burnout, tools introduced to improve productivity will ultimately consume their core workforce.

    Limits of Practical Application and Anti-Patterns

    Even with queues in place, a shortage of people during the validation stage merely increases approval wait times. Broadening the scope of automation leaves maintenance and rework costs as hidden tasks. Simply leaving human review tasks untouched while increasing output volume also leaves only the difficult work for people to handle.

    The most common anti-patterns are mistaking AI output volume for work throughput, generating multiple results in parallel without validation, and mistaking a short demo for production readiness. Absorbing every improvement request as an individual productivity problem also hides structural issues while reducing people’s rest time. The goal of automation should not be to give people more work, but to create a workflow that continues through validated completion.

    Teams can begin this week’s AI work by dividing it into generation, validation, rework, and approval stages and recording the time spent at each stage. Limit the number of AI tasks that can run concurrently according to the team’s concentration capacity, and separate the work queue from the approval queue. After distinguishing repetitive tasks from work requiring final human judgment, share request priorities and expected validation times to agree on a scope that can realistically be adjusted.

    Practical Application Points

    • Coordinate with relevant teams and confirm the approval path
    • Test for impact in advance in an isolated environment
    • Establish a phased rollout and an emergency rollback plan

    Source

    This article was written after consulting the following source: r/cscareerquestions — Is anyone else beyond burnt out from AI-driven hyper-expectations?

  • korea-data-mcp Stops AI Agents Misreading Korean APIs

    korea-data-mcp Stops AI Agents Misreading Korean APIs

    korea-data-mcp for AI agents has been released. The project combines the DART, Public Data Portal, and National Law Information APIs into a single MCP server to help agents such as Claude and Cursor accurately retrieve Korean company, real estate, and legal data.

    Misreading Pitfalls Hidden in Public API Responses

    Even when public API responses are passed directly to AI agents, they may appear plausible while producing incorrect answers. A representative example is a DART semiannual report. When asked about Samsung Electronics’ revenue for the first half of 2025, an agent may respond with KRW 74.6 trillion because thstrm_amount covers three months in the second quarter rather than the first-half cumulative total. Actual first-half cumulative revenue is listed as KRW 153.7 trillion.

    korea-data-mcp addresses these issues at the server level and currently handles 47 pitfalls. For legal information, it corrects cases where amendments to existing laws that have not yet taken effect are mixed into the body of the current statute. It selects the version in force on the reference date and displays provisions scheduled to take effect along with their effective dates.

    For actual apartment transaction prices, it prevents canceled contracts from being included as valid transactions. By default, it calculates the median after excluding the canceled contract. It also addresses the problem of receiving zero results for the previous month when an outdated regional code is entered due to administrative district restructuring, and provides the updated code. Other input errors, amounts in units of KRW 10,000, and dates with two-digit years are also handled separately. The complete list is documented in the repository’s docs/QUIRKS.ko.md file.

    Local Execution and Data Coverage

    Supported areas include DART company, disclosure, and financial statement data, stock prices, basic company information, business registration status, actual apartment sale and purchase prices, public holidays, laws, and court precedents. On Claude Desktop, it can be installed by opening the included.mcpb release file, and it is also registered in the official MCP Registry. Other environments support either a single Go binary or a go install method.

    Users provide their own free API keys. A single OpenDART key is enough to get started within a few minutes. The server runs only on the user’s personal computer and does not use third-party servers or telemetry. A hosted version that can be accessed through a URL without requiring a key is being prepared.

    korea-data-mcp takes the concept of connecting Korean public APIs to AI agents a step further. Instead of displaying raw responses, the server filters out conditions that can produce incorrect answers, such as reporting periods, contract status, administrative districts, and the effective dates of laws. The developers are considering sources such as the Bank of Korea’s ECOS and KOSIS, and are seeking related feedback. More details are available in the GitHub repository.

    Reference Sources

    This article was written after consulting the following source: geeknews — Show GN: korea-data-mcp – An MCP server that helps AI agents correctly read Korean public APIs