Author: l0cknsec

  • Tencent’s WeVisOne-VL Unifies Detection Through Matting

    Tencent’s WeVisOne-VL Unifies Detection Through Matting

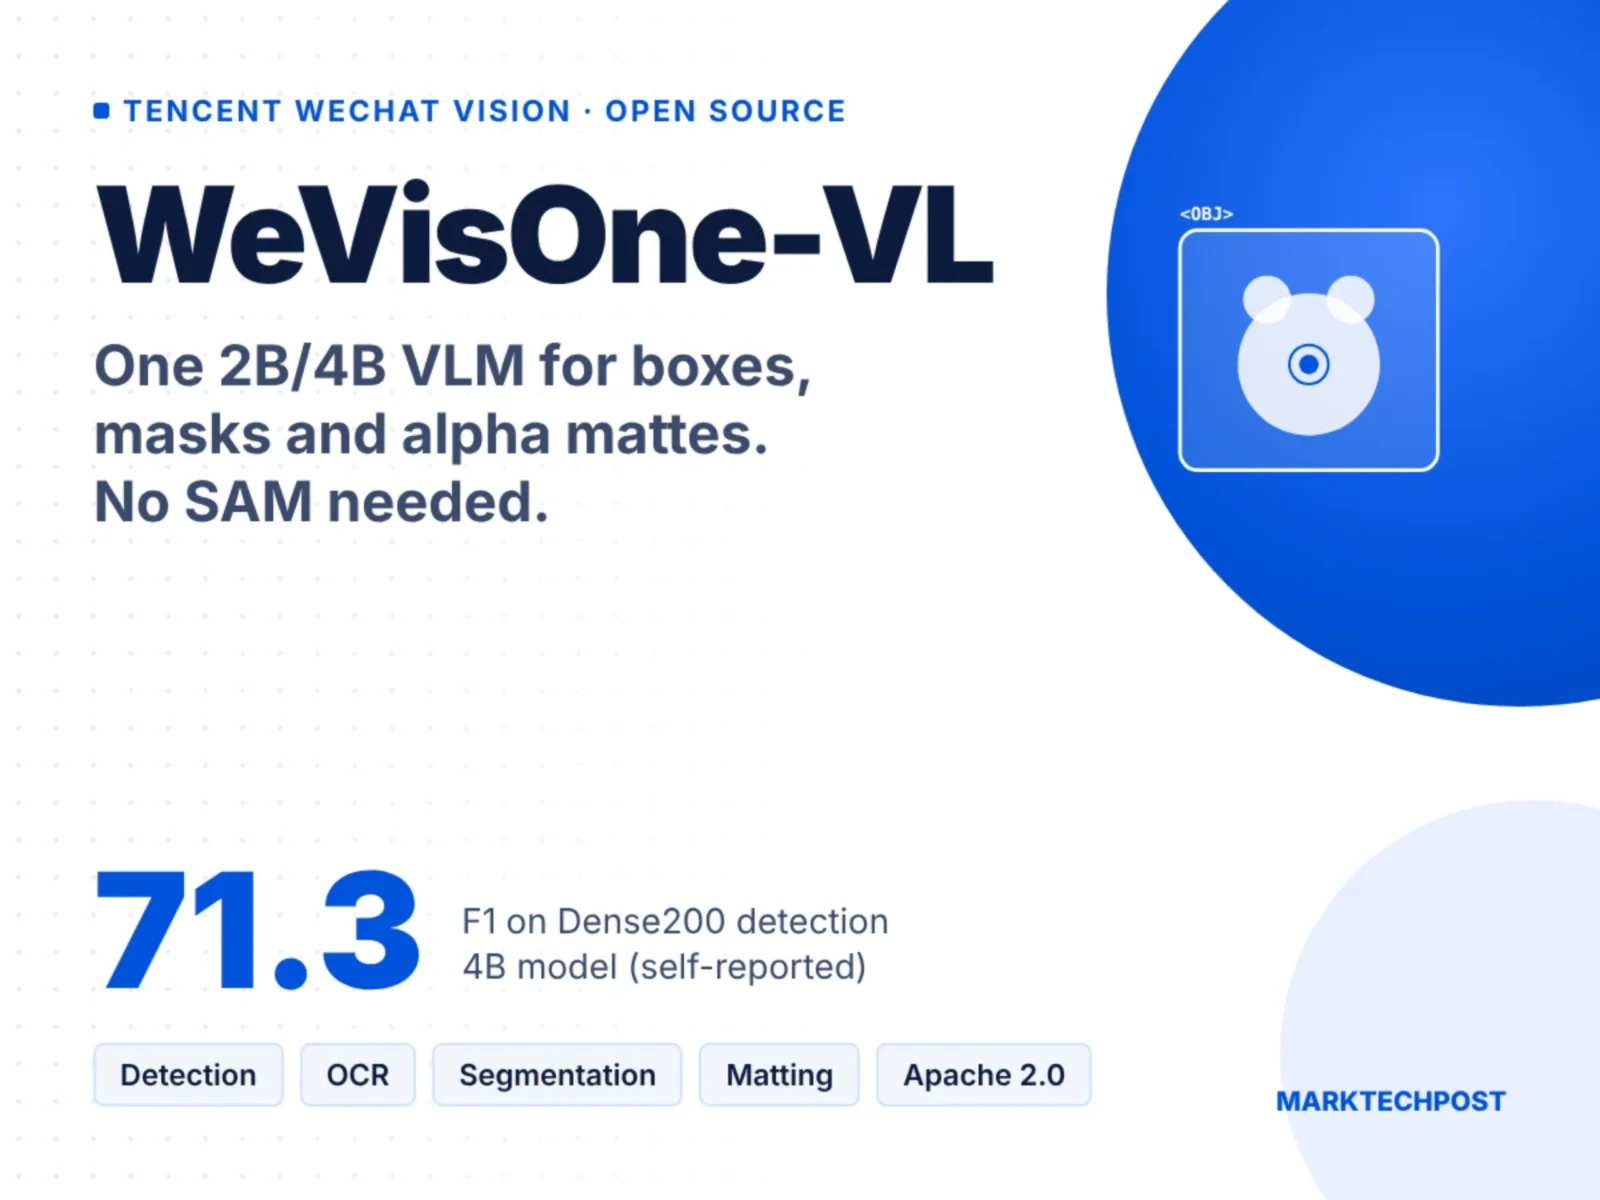
    Tencent’s WeChat Vision team has released WeVisOne-VL, a unified vision model that handles object detection and OCR, as well as image segmentation and alpha matting, in a single model. Rather than connecting separate detectors, OCR engines, or segmenters, WeVisOne-VL focuses on performing various perception tasks through one inference path. According to MarkTechPost’s original report, the model is available on Hugging Face in 2B and 4B sizes under the Apache 2.0 license.

    One Model From Detection to Pixel-Level Output

    WeVisOne-VL supports seven tasks: detection, referring, counting, pointing, OCR, segmentation, and alpha matting. Output formats can be selected according to the required level of precision, including points and boxes, binary masks, and continuous alpha mattes. The model’s goal is closer to fine-grained localization than open-ended conversation. When the requested target does not exist, it outputs “None” instead of a speculative box.

    The masks and alpha mattes are generated by a 9.6-million-parameter pixel decoder. This configuration enables pixel-level results without running SAM separately, and it further concentrates responsibility for detection and mask generation in a single model, distinguishing it from conventional perception pipelines.

    Architecture Combining Coordinate Tokens and Box-Based Queries

    All WeVisOne-VL tasks are processed through structured next-token prediction. Boxes and points use normalized coordinate tokens ranging from 0 to 1,000, while pixel-level tasks emit an <OBJ> token after the predicted box. The hidden state of this token is used as a query for the pixel decoder.

    The pixel decoder consists of three stages. The Visual Feature Adapter reuses multi-level ViT features from Qwen3-VL without adding a second image encoder. The Box-Guided Query Decoder uses six deformable cross-attention blocks and processes queries initialized with the <OBJ> state and boxes. The Dense Prediction Head refines results at S/4, S/2, and S/1 resolutions to produce full-resolution masks or mattes.

    Large-Scale Annotation and Three-Stage SFT

    The training data was constructed by a knowledge-graph-driven data engine that generated approximately 3.6 billion boxes across more than 100 million images. SAM3, Rex-Omni, and Tencent’s own detector proposed regions, which were then verified by Qwen3-VL.

    SFT proceeded in three stages. The first stage aligned the output format using 90 million examples. The second expanded the input to 1,960 visual tokens and the output to as many as 500 boxes per response. In the third stage, the model trained the pixel decoder before undertaking matting-focused training with 130 million samples. At the final stage, GRPO was applied to 178,000 examples filtered by an uncertainty criterion.

    Benchmark Results Reveal a Trade-Off Through Rejection Rates

    Tencent said WeVisOne-VL generally outperformed same-sized VLM baselines across more than 30 benchmarks. The 4B model recorded 55.3 F1 on LVIS detection, 71.3 F1 on Dense200, 81.8 F1 on the RefCOCOg test set, and 89.6% exact-match on the PixMo-Count test set. For OCR, it achieved 52.0 F1 on TotalText, while segmentation reached 71.2 gIoU on the ReasonSeg validation set. These figures are Tencent’s own claims and require independent verification.

    Task Evaluation Set WeVisOne-VL 4B Comparison Model
    Dense detection Dense200 71.3 F1 LocateAnything-3B: 58.7 F1
    OCR TotalText 52.0 F1 PP-OCRv5: 25.7 F1
    Segmentation ReasonSeg val 71.2 gIoU LISA-13B: 65.0 gIoU
    Matting P3M-500-NP box prompts 7.3 MAD SAM2-Matting(SAM3): 15.4 MAD

    Its rejection performance on queries involving nonexistent objects was satisfactory. Across 2,880 WeRef-Bench queries, the rejection rate reached 96.4%, higher than the 73.0% of the comparison target. By contrast, PR-Bench recorded a rejection rate of 52.6%, revealing an issue in which the model still output some boxes when asked for nonexistent targets. These results show that the practical safety performance of a unified vision model needs to be evaluated from multiple angles rather than through a simple score comparison.

    Apache 2.0 Release and Remaining Deployment Constraints

    The 2B and 4B weights are available on Hugging Face, and the wevisone_vl package provides Transformers and vLLM backends. It can run on a single GPU in BF16, while the package also lists NPU and CPU as supported targets. Actual VRAM requirements and the context length for deployment have not been disclosed, although training used up to 8,192 tokens. One reported use of a community GGUF build ran object-level tasks on a 6 GB RTX 2060.

    The weights are released under Apache 2.0, but the fine-tuning code remains a TODO. The GGUF build cannot generate masks because it cannot use the pixel decoder, which requires native visual features. Tencent also released Mask2Alpha, which it used in the data engine, alongside the matting annotations.

    WeVisOne-VL’s core value lies in bringing multiple perception models together under a single structured output framework. However, its PR-Bench rejection rate, unfinished fine-tuning tools, and GGUF mask limitations are factors that must be considered when applying the unified vision model to real-world product pipelines.

    Source

    This article was prepared with reference to the following original source: MarkTechPost — Tencent WeVisOne-VL Unifies Detection, OCR, Segmentation and Matting
  • Google Extends School AI Blocks to Search, Sparking Debate

    Google Extends School AI Blocks to Search, Sparking Debate

    Google’s school AI policy is designed to give administrators control over the use of generative artificial intelligence in American elementary, middle, and high schools. However, at schools that do not permit generative AI, ordinary Google Search may also be disabled for student accounts, bringing both institutional choice and dependence on search services into focus.

    School Choice Expanded, but Search Was Blocked Too

    Is Google relevant to education across the United States?

    On the 3rd local time, Google announced on its official blog that it would disable Gemini, Gemini Notebook, Gemini in Google Classroom, and Google Search by default for K-12 student accounts spanning kindergarten through high school until school administrators explicitly permit their use. Gemini is Google’s AI model, Gemini Notebook is a tool for analyzing educational materials, and Google Classroom is a platform through which teachers manage student assignments and other tasks online.

    Google justified the measure by arguing that schools must be given control so they can manage AI in the classroom and oversee how students access it. The measure followed an earlier decision to enable Gemini chatbot features by default in Google Classroom at schools that allow generative AI, which prompted objections from schools and parents.

    This approach aligns with the argument that schools should decide when and how students may use AI. New York City limited generative AI use among elementary and middle school students for one year to protect their capabilities, while the Los Angeles Unified School District also prohibited generative AI use on school-provided devices for one year. The decision was reportedly made after Google consulted schools, teachers, and policy advocates.

    Why an AI Ban Leads to a Search Block

    The central technical issue behind school AI restrictions is that generative AI features are deeply integrated into Google Search. Google Search currently includes AI Overviews, which summarizes search results, and AI Mode, which allows users to find information through conversations with AI. Using search now requires accepting these AI features.

    Chris Phillips, Google’s vice president of education, explained that “search and AI are deeply integrated.” He said that if a school prohibits AI, students lose access to the search service. In other words, a school’s decision to block Gemini alone may also restrict students’ ordinary web browsing.

    Google said it plans to improve its services by offering educational features that guide students toward solving problems step by step rather than simply presenting them with answers through AI Overviews and AI Mode. However, it maintained that the AI features built into Google Search cannot be removed separately.

    The Clash Between Market Power and Educational Control

    This policy sits between the argument that it expands schools’ autonomy and criticism that it effectively coerces the adoption of AI.

    Josh Golin, executive director of the children’s rights organization Fairplay, also said Google’s effort to push its own AI products on schools is highly likely to backfire. The argument that Google is bundling search and AI while also narrowing the range of choices available to schools is drawing attention from an antitrust perspective.

    As the controversy grew, Google clarified through X that the decision expands schools’ autonomy. There is clear tension between handing control to school administrators and tying access to search services to the same choice. Hankyoreh’s related report also provides insight into the scope of the debate this decision has generated within education.

    When Schools Need to Establish New Adoption Standards

    When redesigning school AI policies, schools need to assess generative AI use separately from the use of search services. Unless they define the range of tools permitted during learning, assignments requiring teacher review, and activities designed to develop independent thinking, policies may become blurred into formal administrator approval or prohibition.

    Schools also need to distinguish between school-provided and personal devices, classroom instruction and assignment submission, and levels of risk based on students’ ages and cognitive abilities. The one-year restrictions adopted by the New York City and Los Angeles education authorities are useful examples of setting a temporary adoption principle, but schools need standards that include a process for reassessing the rules when the period ends.

    Pressure is also likely to grow on service providers not to treat AI features and conventional search as a completely inseparable package. Even while Google develops search features suited to learning, schools must also consider conventional search alternatives that they can disable; otherwise, restrictions on AI may undermine access to learning resources themselves.

    School AI restrictions must address both the need to protect students’ independent thinking and access to information required for learning. Giving administrators explicit control is significant, but a structure that simultaneously limits choice at two levels—whether AI may be used and whether search may be used—requires additional explanation in both education policy and antitrust enforcement.

    Source

    This article was written based on the following source: Hankyoreh — Google Blocks Search for Schools That Reject AI, Sparking ‘AI Upselling’ Controversy in the US

    Cross-checked sources:

  • Niko PC Launcher Attack Raises Credential Theft Fears

    Niko PC Launcher Attack Raises Credential Theft Fears

    A software supply chain attack has been identified in which a game launcher legitimately downloaded from the official website could become infected with an external remote-control backdoor. The PC launcher distribution infrastructure for the game “Goddess of Victory: NIKKE” was found to have been compromised, exposing users to credential theft and remote-control risks. Shift Up and Level Infinite confirmed the possibility of third-party file tampering and urgently distributed a corrective patch.

    The attack began by compromising the official update channel

    According to the technical analysis, the point of intrusion was not a security flaw in the game client itself but the official content delivery network (CDN) server operated by Level Infinite. After stealing write access to the official distribution network based on Tencent Cloud Object Storage (COS) on September 27, the attacker inserted malicious loader code into four JavaScript files that called the notice screen and graphics.

    The altered scripts connect to the attacker domain insightjs.com in the launcher’s browser background and retrieve additional payloads. They then abuse the launcher’s download function to obtain LuaJIT-based malware disguised with a plain-text log file extension and execute it in memory. Identified as a remote access trojan (RAT) that maintained encrypted communications with an external control server, the malware could execute remote shell commands, browse and exfiltrate files, and capture the entire monitor screen on infected devices.

    Browser accounts and development infrastructure were targeted together

    The malware targeted account passwords and session cookies stored in Google Chrome, Microsoft Edge, and Firefox. The search also focused on data from 28 cryptocurrency wallets, including MetaMask and Phantom. It scanned development credentials across 264 paths, including AWS, Microsoft Azure, and Google Cloud keys, GitHub tokens, Docker and Kubernetes configuration files, and SSH keys.

    To maintain persistence even after the game and launcher were closed, the malware registered a fake module in the Windows registry and concealed itself so the backdoor would automatically launch whenever Chrome was executed. By taking browser accounts as well as keys from cloud services, code repositories, and container environments, it increased the risk of a second-stage supply chain attack that could connect game users with development infrastructure privileges.

    Concerns about corporate network intrusion through developer endpoints

    Similar credential theft could be interpreted as an attack that uses individual developer devices as an intermediary to enter the internal development networks of game studios and IT companies. Nexon issued an urgent directive to immediately remove the NIKKE PC launcher from employee devices and report them to security teams. Krafton and Netmarble also strengthened monitoring of access to internal devices and business networks.

    The damage may not be confined to a single NIKKE title. Level Infinite operates global services including “PUBG Mobile,” “King of Glory,” and “Arena Breakout: Infinite”. Concern has grown that other games sharing distribution networks and CDN infrastructure may also have been exposed to similar compromises.

    Rapid endpoint response and redesign of distribution integrity

    Employee devices and personal computers should be subjected to launcher removal, corrective patch deployment, and referral to security teams. If an infection is confirmed, browser-stored passwords and session cookies should be discarded, while cryptocurrency wallet data, cloud keys, GitHub tokens, Docker and Kubernetes configuration files, and SSH keys should be securely revoked and reissued. The fake module in the Windows registry and browser autorun entries should also be inspected.

    Within corporate networks, organizations need to review authentication logs from devices that ran the launcher and access histories to development repositories and cloud services to track signs of lateral movement. Moon Kwang-seok, head of the Future Convergence Technology Institute at the Korea Information Society, said that as supply chain attacks rapidly increase, integrity verification and hash-control systems must be redesigned from the outset across the entire software lifecycle, from source-code builds to CDN deployment. Further details about the attack can be found in Boannews’ report on the supply chain attack.

  • EloElo Raises $80M as India’s Microdrama Market Surges

    EloElo Raises $80M as India’s Microdrama Market Surges

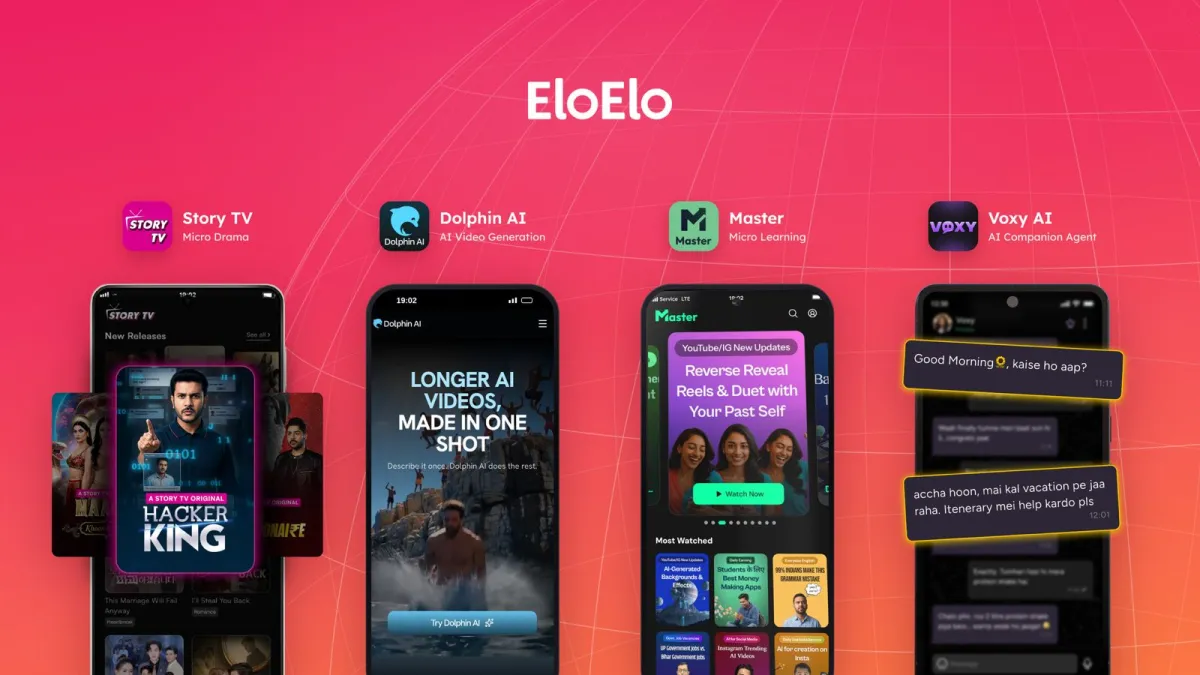
    More than 118 million people in India watch microdramas every month, with vertical video and serialized narratives becoming key elements of mobile consumption. EloElo, which operates the microdrama app Story TV, recently raised an $80 million Series C with participation from NBCUniversal and Hornbill Capital. The company’s cumulative funding stands at $130 million, while its valuation is reported at $500 million.

    A User and Content Foundation for the Market

    Story TV has more than 33 million active users, according to analysts. Founded in 2020 by former Flipkart executive Saurabh Pandey, the service offers content in six languages and has more than 5,000 titles. A survey found that users open the app several times a day and watch for an average of 95 minutes per session, with short-form content and repeat visits emerging as the primary usage patterns.

    India’s vast internet population and demand for entertainment content are creating substantial market opportunities that remain largely untapped. Dedicated apps such as Story TV, Kuku TV, and Quick TV ranked among the most-downloaded video streaming apps last year. Microdramas are also increasingly being viewed as a common gateway for mobile streaming users, extending beyond a niche genre.

    The Challenge of Moving from Free Viewing to Subscription Revenue

    Story TV offers monthly, quarterly, and annual subscriptions alongside ad-supported free content, but converting free users into paying subscribers remains a major challenge. According to Redseer’s analysis, more than 40 million people have paid for microdramas at least once, but only 15 million to 17 million pay on a monthly basis. An Ormax Media survey found that 72% of microdrama consumers have never paid for the content.

    This structure may allow the platform to survive in a market where competitors emphasize free content, but it also highlights the difficulty of converting visit frequency and title depth into revenue. Pandey said high-quality content can draw users to Story TV and persuade them to choose the free platform. EloElo is strengthening its production capabilities through collaborations with companies such as Balaji Telefilms, with part of the new funding directed toward original productions.

    Dolphin AI Combines Production Speed with Human Judgment

    Story TV plans to make its internally developed Dolphin AI tool widely available to improve video production efficiency. The tool provides a template-based editor and image, audio, and video generation models. EloElo plans to expand its capabilities so they can also be used in future marketing campaigns and advertising. While providing AI tools to creators, as Google-backed Kuku does, can shorten the content pipeline, critics say alternatives such as CapCut and Instagram Edits still offer insufficient support for Indian creators.

    Pandey argued that human involvement remains essential for telling compelling stories and that AI should complement the capabilities of creative directors and showrunners. He also said AI can help write stories, but the works he enjoyed required a high degree of integration between humans and AI. EloElo currently has a workforce of 240 people and plans to expand its AI and machine learning research teams.

    The Competitive Edge Investors See

    NBCUniversal participated in the latest funding round, alongside MIT Investment Co. and existing investors Play Ventures, Kalaari Capital, Waterbridge Ventures, and Griffin Gaming Partners. In addition to Story TV, EloElo operates the learning app Master and the AI companion app Voxy AI, with the company reporting more than 40 million monthly users across all of its apps. According to the company, most users are on Story TV, but it does not disclose app-specific user numbers.

    Annual revenue in India’s microdrama industry is projected to exceed $3 billion to $4 billion by 2030. The cases of Story TV and Dolphin AI demonstrate how securing a massive audience and maintaining a stable content supply can attract investment. The next challenge will be how precisely the company can balance free users’ willingness to pay against AI-accelerated production systems. More details are available in TechCrunch’s report on EloElo’s investment.

    Source

    This article was prepared with reference to the following source: TechCrunch — India’s EloElo nabs $80M from NBCUniversal to bet on the country’s rising microdrama market

  • A Practical Framework for Documenting IT Work

    A Practical Framework for Documenting IT Work

    The most exhausting situation in IT is not when a technical problem is complex, but when decisions are made without any record of what needs to be handled or when. If requests arriving by phone and messenger all seem urgent and deadlines are vague, IT ends up assigning work to the loudest person and the nearest available owner. When complaints about prioritization are added to the mix, IT is not merely defending its judgment; it is also taking on responsibility for the organization as a whole.

    The original article repeatedly describes a pattern in which every request is urgent, nothing is documented, and IT is still identified as the final accountable party. An approved project is suddenly halted, but neither the reason for the halt nor the approval process is shared. The core problem is not a lack of IT capability. It is that the boundaries of responsibility for requests, approvals, and execution are not fixed through documentation.

    Why problems persist even when tickets exist

    A ticket is only a mechanism for collecting requests; it does not by itself establish a decision-making sequence. If messages and verbal instructions remain the actual path to execution, tickets serve only as retrospective records. The starting point for IT work documentation should therefore not be replacing tools, but establishing operating rules that route every request through intake, evaluation, approval, execution, and confirmation.

    This process can be organized into six stages: request intake, requester verification, technical impact and risk assessment, approval by an authorized manager, agreement on schedule and priority, and change execution and completion confirmation. IT should focus on explaining technical feasibility and risk and recording approval outcomes. Final authority over business priorities and resource allocation should remain with the authorized manager.

    Turning verbal instructions into actionable records

    Even when a request arrives through a messenger, do not immediately turn it into a work item. First confirm the requester, purpose, desired outcome, and preferred timing with the requester, then have IT assess the scope of impact and the possibility of recovery. The approver then makes the decision, and the change begins only when the approval outcome and change target are registered together.

    In a real environment, teams can use a request template from an issue-tracking tool. Create a change request template file in the repository and define fields for the requester, change purpose, affected systems, risks, executor, approver, rollback method, and completion confirmation. Linking the ticket number to the change branch and deployment pipeline makes it possible to trace which approval corresponds to which change.

    title: "IT Change Request"
    labels:
     - "it-change"
    description: |
     ## Request Information
     - Requester:
     - Change Purpose:
     - Preferred Timing:
    
     ## IT Assessment
     - Affected Systems:
     - Risks and Recovery Method:
    
     ## Approval and Execution
     - Approver:
     - Approval Time:
     - Executor:
     - Completion Result:
    

    ※ The following configuration and code are conceptual illustrative examples to aid understanding, not an official specification for any specific product.

    Separate urgency from the processing procedure

    If the word “urgent” alone is enough to move an item to the front of the queue, every request becomes urgent. Urgency should be assessed against business impact, recoverability, safety and legal risks, alternative approaches, and the required approval process. Items that can be executed immediately must be distinguished from those whose approval procedures cannot be skipped.

    It is risky for IT to carry out verbal instructions first and demand documentation afterward. Retroactive approval of a change that has already been made becomes distorted, and it remains unclear what the approver actually approved. If there is a technical exception that requires an immediate response, record that fact separately, including who made the judgment, why the response could not be delayed, and what scope was isolated. The principle should be that a risky change without an official approval record must not be executed.

    Minimum standards for approval and change records

    The completeness of a record should be judged not by its length, but by whether the situation can be reconstructed. Even if the same question arises later, it should be possible to determine who requested what, why a priority was assigned, who granted approval, and what was completed and when. If an approved project is halted or requirements change, the previous state and the changed state should be retained together so that IT does not arbitrarily reverse past decisions.

    The issue can be reviewed in the following original discussion: Everything is urgent, nothing goes in writing, and somehow it’s always IT’s fault.

    Considerations when introducing the process

    The most common anti-pattern is adding more forms without introducing a coherent system. Long templates that neither requesters nor approvers use are simply abandoned. IT work documentation should retain only the minimum fields necessary for approval, while recurring questions should be incorporated into the template.

    Operational costs must also be considered. If the approval system is excessive, emergency responses become slower; if approval authority is dispersed, teams end up searching again for “who made the decision.” Designate approvers according to the organization’s size and risk level, but preserve the principle that an authorized manager finalizes priorities and resource allocation. Do not attempt to migrate records scattered across existing emails and messages from the outset. It is more practical to transfer currently active requests into the template first.

    What to try now

    • Start with active requests that were decided verbally and organize the requester, purpose, impact, and approver.
    • Add a change request template to the issue-tracking project and register one test request using the minimum required fields.
    • Separate approval from execution by establishing a rule that unapproved risky changes remain only in the work queue.
    • Reclassify urgent requests based on business impact, recoverability, safety risks, alternative approaches, and whether approval is required.
    • After recording a request from intake through completion confirmation, review the fields completed by the approver and executor separately.

    Original source

    This article was written after reviewing the following original source: r/sysadmin — Everything is urgent, nothing goes in writing, and somehow it’s always IT’s fault

  • Hydrogen-1.0: An Open Scientific Model for Discovery

    Hydrogen-1.0: An Open Scientific Model for Discovery

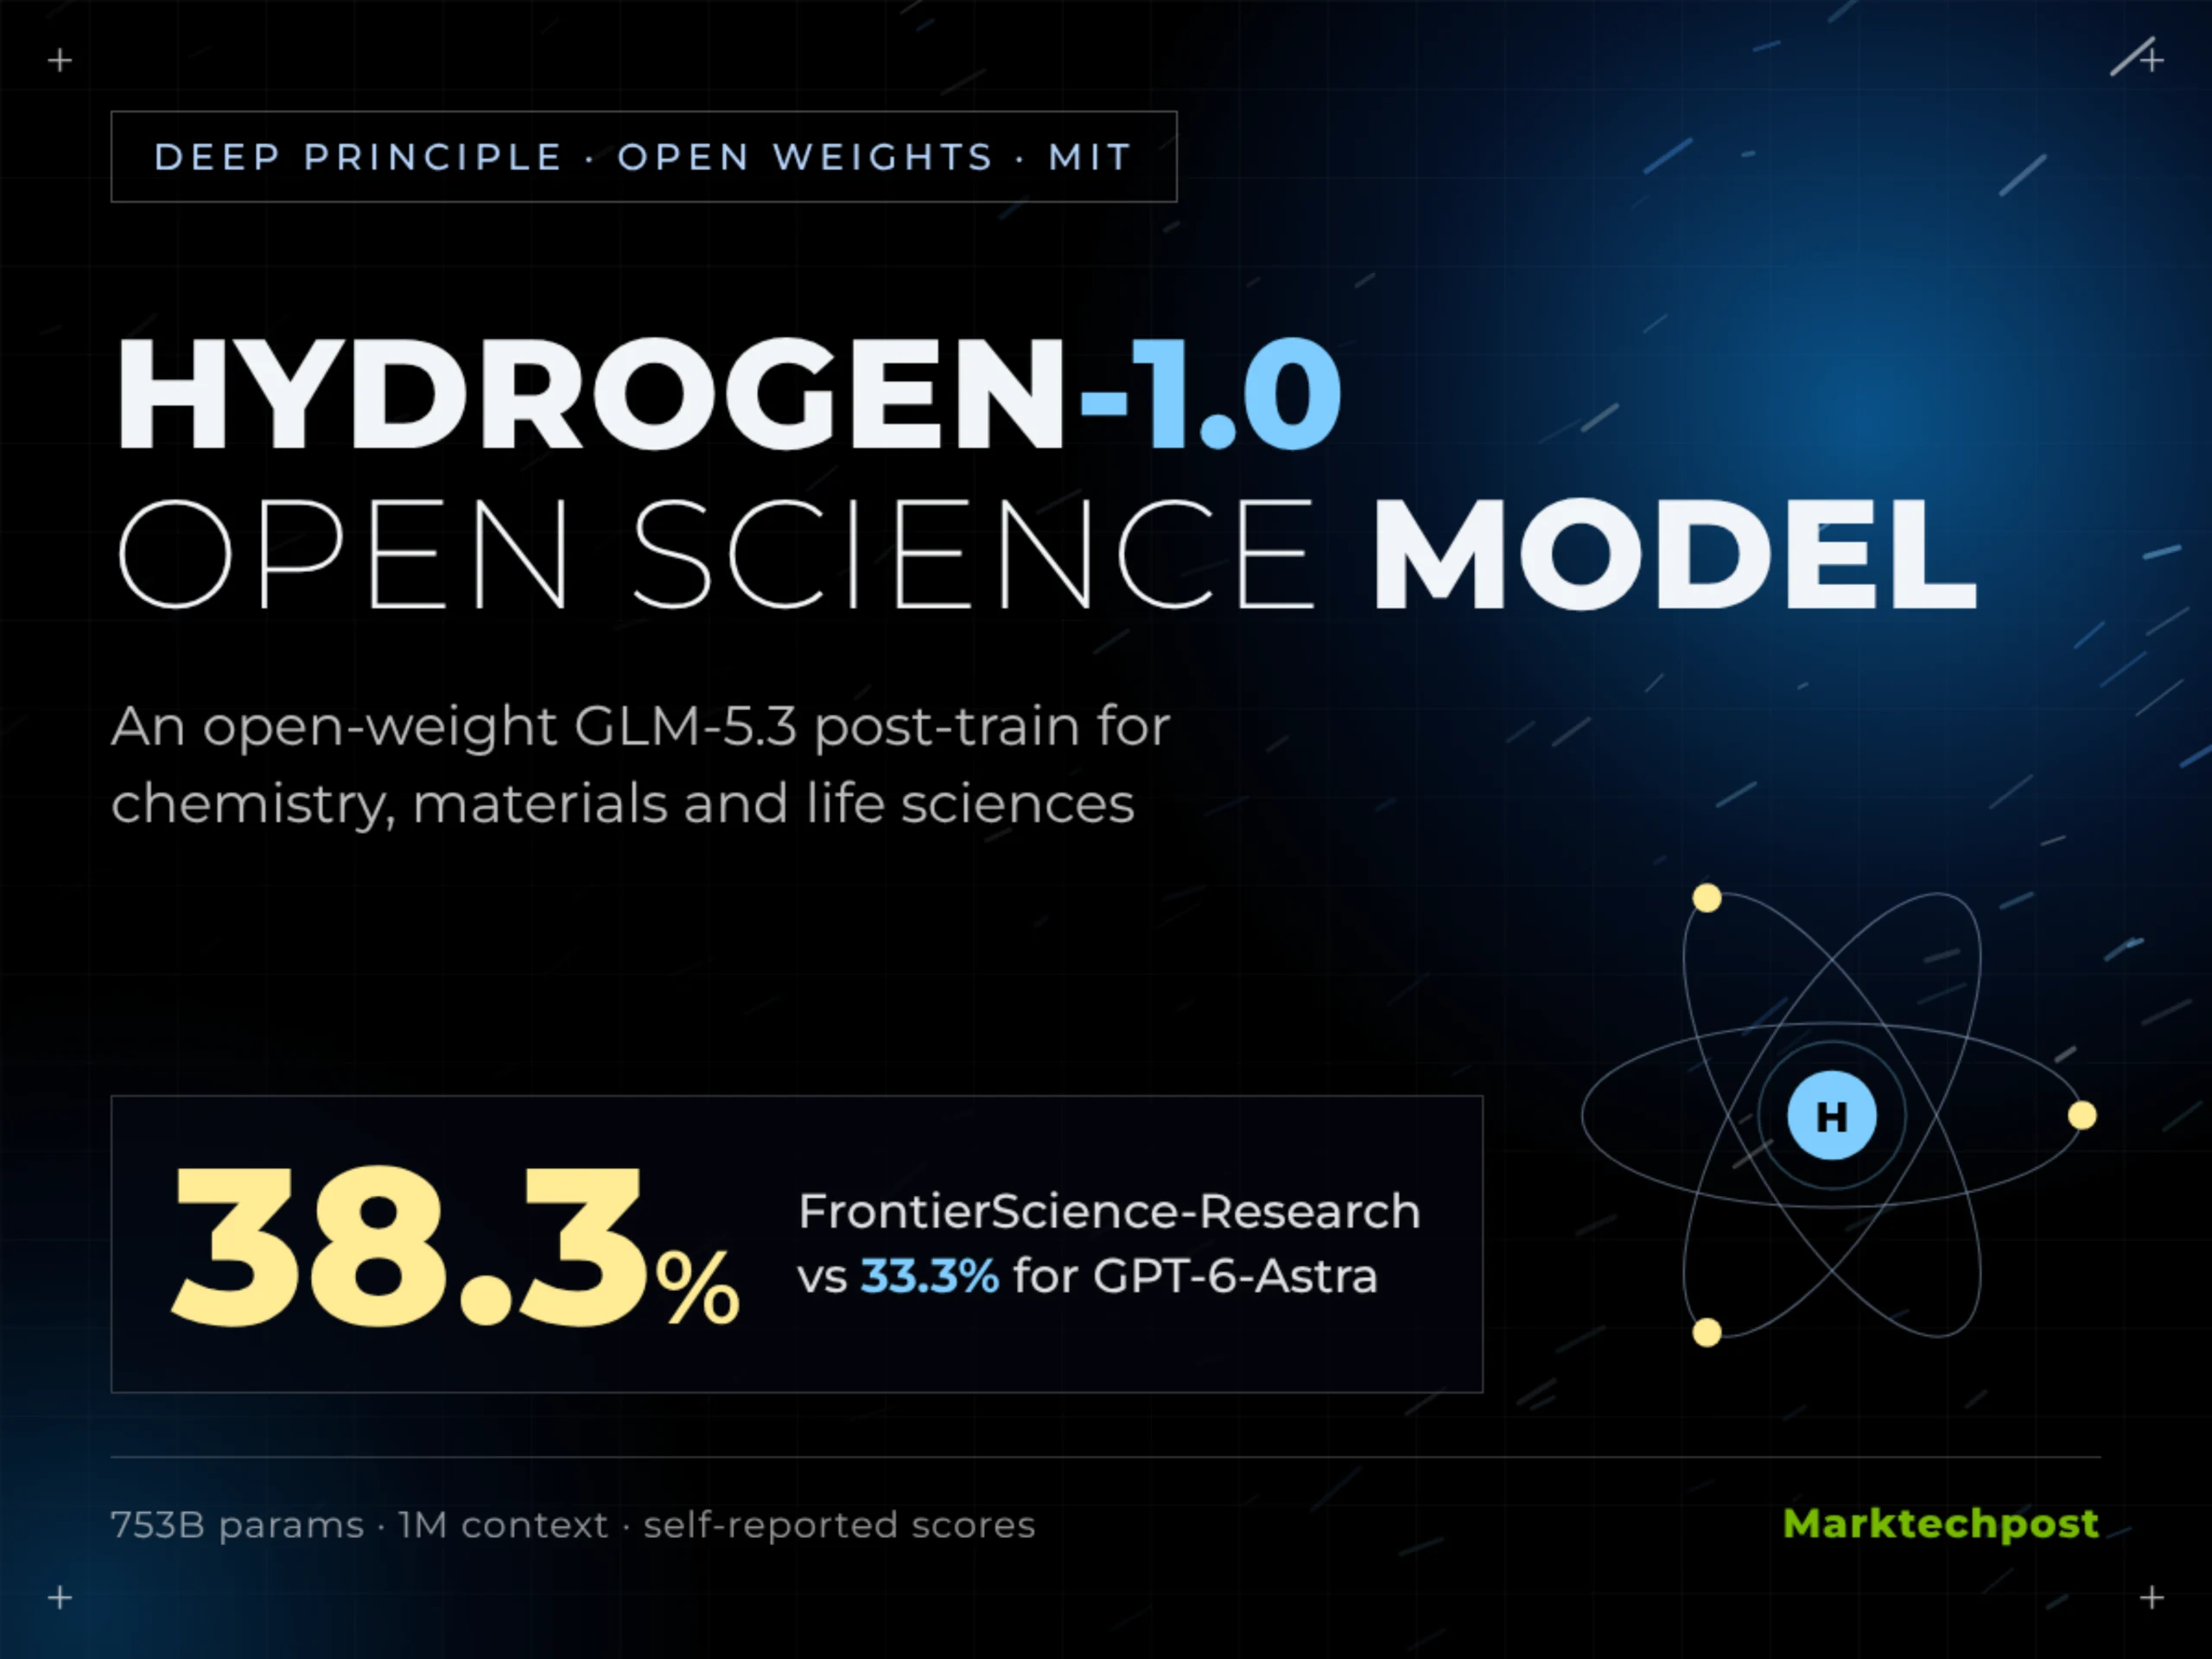
    Deep Principle released Hydrogen-1.0, a scientific open model for chemistry, materials science, and life sciences. Built on GLM-5.3, it targets not only general paper queries but also experiment design and result analysis, with its weights distributed under the MIT License. Deep Principle reported that its internal evaluations produced a higher FrontierScience-Research score than GPT-6-Astra, but the full dataset and training recipe have not been released, so the reported figures cannot yet be independently reproduced.

    A Scientific Exploration Model Beyond Paper Question Answering

    Hydrogen-1.0 is a 753B-parameter MoE model post-trained from Z.ai’s GLM-5.3, with approximately 40B active parameters. Its context window was introduced as 1M tokens, with maximum output of 128K tokens. Its intended uses include question setting, experiment planning, result analysis, and open-ended exploration.

    The model used scientist task feedback, electronic experiment notes collected through Mira, and discovery trajectories containing both successes and failures as training data. Training combined supervised fine-tuning with reinforcement learning, and the distributed environment is based on Megatron and SGLang with support for NVIDIA CUDA and AMD ROCm. Muon optimizer state can move between CPU, GPU, and disk depending on the backend, while RL rollouts were designed to be resumable. The layout adapter converts training checkpoints into BF16 inference weights and 128×128 blockwise FP8 inference weights.

    Self-Evaluated Results and Task-by-Task Gaps

    In an internal research-task evaluation released by Deep Principle, Hydrogen-1.0 outperformed GPT-6-Astra by 5.13 percentage points in scientific computation and by 4.76 percentage points in retrosynthetic prediction. By contrast, GPT-6-Astra scored 3.33 percentage points higher in NMR structure elucidation. In other words, the results should be examined separately by task rather than interpreted as evidence that the performance advantage extends to every area of science.

    Evaluation task Hydrogen-1.0 Comparison
    FrontierScience-Research 38.3% Higher than GPT-6-Astra’s 33.3%
    GPQA-Diamond 93.0% Generally comparable to Kimi-K3
    Scientific computation Difference benchmark 5.13 percentage points higher than GPT-6-Astra
    Retrosynthetic prediction Difference benchmark 4.76 percentage points higher than GPT-6-Astra
    NMR structure elucidation Difference benchmark 3.33 percentage points lower than GPT-6-Astra

    In transition-metal complex design, the models tracked larger HOMO-LUMO gaps over five rounds. At round five, Hydrogen-1.0’s average optimal gap was 4.318 eV, compared with 3.689 eV for GPT-6-Astra and 3.353 eV for Kimi-K3. On 117 experiment-planning questions, Hydrogen-1.0 scored higher than Kimi-K3, but GPT-6-Astra and Opus-5.5 refused more than half of the requests and were excluded from the comparison. Because these results were self-reported by Deep Principle, independent validation under the same conditions is also needed.

    Lab Automation Demos Reveal Both Possibilities and Risks

    The released technical materials show how the model can be integrated into actual research workflows. Hydrogen-1.0 used Python code and GROMACS to assemble a polyethylene melt, identified and corrected topology errors, and analyzed a corrected 40 ns trajectory. For an Ireland-Claisen reaction, it generated a reaction network of 27 structures from 30 reaction candidates, and for the 1H NMR trace of 2-bromonaphthalene, it ranked seven candidates for single formylation products. For a Suzuki coupling study, it wrote a JSON protocol covering 12 vials, with the virtual-laboratory validation stage detecting a case in which a fresh tip was missing during an aspirate operation before execution.

    These demos show that the strength of an open scientific model lies not only in answer accuracy but also in executable workflows and intermediate validation. However, protocol generation, reagent safety, and the physical validity of analytical results are separate verification problems. The fact that a model has generated a procedure does not guarantee the reliability of real experiments. Its use of exploration records that include failed attempts should also be evaluated separately from approaches that train only on successful cases and may therefore introduce bias.

    The Validation Gap Between Open Release and Real-World Adoption

    The weights were released on Hugging Face and ModelScope, and Deep Principle tested BF16 serving with eight GPUs and tensor parallelism of 8 in SGLang. NVFP4 configurations were proposed for NVIDIA B200 and B300 systems, while MXFP4 configurations were proposed for AMD Instinct MI350X and MI355X systems. The server provides an OpenAI-compatible API and exposes a reasoning_effort setting. Reference API pricing for NeuroSpark has not been published. The public scope and release terms can be confirmed through Deep Principle’s Hydrogen-1.0 release materials.

    Before practical adoption, organizations must separately verify whether the self-reported evaluations can be reproduced, the model’s accuracy on their actual research data, code-execution and synthesis or analysis error rates, and the stability of long-running exploration processes. The 753B MoE architecture and eight-GPU serving configuration may also place demands on operational resources, while cost information such as NeuroSpark pricing remains a gap in deployment planning. Open weights and the MIT License provide a foundation for directly reviewing the model’s internal behavior and weights, but they do not close the validation gap created by undisclosed training data.

    Source

    This article was prepared by consulting the following original source: MarkTechPost — Deep Principle Releases Hydrogen-1.0: A 753B Open-Weight Model for Scientific Discovery

  • Cyberattack Targets European Supermarket Freezers

    Cyberattack Targets European Supermarket Freezers

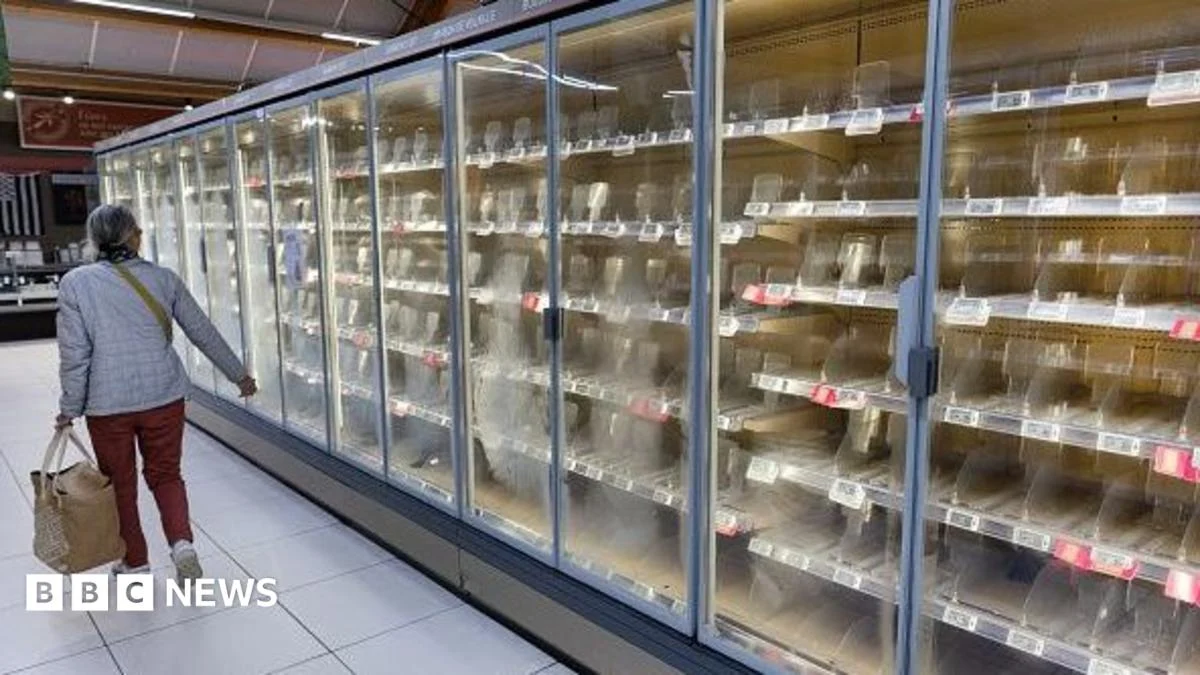
    As suspicious cyberattacks targeting refrigerators and freezers have affected several European supermarkets, the security vulnerabilities of internet-connected appliances and industrial equipment have become central to a major debate. Following this incident, discussions have called for a thorough qualitative safety review to determine whether everyday devices such as humidifiers, heaters, and washing machines share the same risks as vehicles and energy infrastructure. However, a device does not become immediately hackable simply because it is connected to the internet, and major manufacturers have also invested significant resources in security.

    Connected-Device Attack Surface Revealed by Freezer Attack

    Smart devices connected to the internet offer convenience and operational efficiency through remote control, but they can also become targets for abuse by malicious actors. Security researchers demonstrated in 2015 that vulnerabilities in a Samsung smart refrigerator could be exploited to intercept internet traffic, illustrating that real-world exploitation may also be possible with consumer appliances. However, there is still no confirmed evidence that the appliances themselves were targeted in the November attack against European supermarkets.

    The UK’s National Cyber Security Centre (NCSC) is working with international partners and industry collaborators to understand the incident in advance, but it has not identified any impact in the United Kingdom. Researchers found that more than 800 refrigeration and building-control interfaces connected to UK retailers were accessible over the public internet. While public accessibility does not necessarily mean the systems can be hacked, the warning is that weak passwords or software vulnerabilities could leave them exposed as an attack surface if exploited.

    Boundaries of Equipment Ownership and Repair Responsibility

    The central issue is where responsibility for equipment security should lie. SentinelOne researcher Tom Hegel said retailers need to clarify who owns the security of the relevant equipment, rather than merely identifying the organization responsible for repairs. As connectivity provides convenience, security must keep pace, and a warning cautioned that if attackers seize legitimate control functions, even ordinary functions such as defrosting could be turned into a tool for disruption. Assessments also concluded that configuration changes could cause physical damage to actual inventory, beyond simply disrupting computer systems.

    Retailers in the UK have previously held security discussions with the government and major food distributors about cyber resilience in preparation for incidents. Helen Dickinson of the British Retail Consortium emphasized that cyber incidents are a major concern for retailers and that companies are sharing information and strengthening their defenses with the NCSC. After M&S and Co-op were targeted by ransomware attacks in May 2025, fresh deliveries ran short on some shelves, prompting customers to voice dissatisfaction with empty shelves.

    Infrastructure Risks Spreading Beyond the Home

    Outside the home, connected technologies are used to remotely manage industrial machinery and vehicles, while equipment at power plants and in water-supply chains is also monitored through mobile connectivity. Security expert Ken Munro cited a 2015 demonstration in which researchers remotely hacked a Jeep through an internet-connected entertainment system, saying the incident led to improvements in vehicle security. He assessed that connected security at UK utility companies was generally sound, but that global standards vary.

    Small, cash-strapped utility companies that may depend on older and vulnerable equipment were identified as the greatest source of concern. Olivier Daloy, a cybersecurity expert at Zscaler, said that without adequate protection, every internet-connected factory and piece of equipment could face similar risks, extending from automobile manufacturing to power and transport infrastructure. This goes beyond inconvenience or information leakage from appliances and demonstrates the possibility that a loss of control could result in physical harm.

    Security Standards and Consumer Responses

    UK law has required manufacturers of some consumer smart devices to meet minimum cybersecurity standards, including passwords and security updates, since April 2024. Former NCSC chief executive Ciaran Martin noted that there is much to demand of big technology companies to create safer devices and products, and recommended that consumers update their devices and enable multifactor authentication (MFA) where possible. He said that enabling multifactor authentication takes only a few seconds but can still be inconvenient, illustrating the practical barrier that security convenience poses to widespread adoption.

    This incident shows that connected-device cybersecurity must be treated as an essential requirement at the design stage rather than an optional added feature. Manufacturers should go beyond merely meeting minimum security standards and clearly define responsibility for equipment, update periods, and remote-control access. Retailers should check that refrigeration and building-control interfaces are not unnecessarily exposed to the public internet, while consumers should make updating older devices and configuring authentication part of their everyday security habits. Further reporting is needed to establish the technical scope of the attack and where responsibility lies.

    Source

    This article was prepared with reference to the following source: BBC Tech — If hackers can take control of a supermarket freezer, how vulnerable is other tech?

  • Linux Kernel CVE-2026-98432: AI Zero-Click Attack

    Linux Kernel CVE-2026-98432: AI Zero-Click Attack

    Anthropic’s Frontier red team used an undisclosed next-generation research AI model to discover the flaw and demonstrate remote code execution (RCE). Canonical and the National Institute of Standards and Technology (NIST) assigned the zero-click attack chain a CVSS score of 9.8. According to Security News’ initial report, it can seize root privileges without user interaction, requiring urgent action on enterprise servers.

    Race Condition During TCP SYN Processing

    CVE-2026-98432 occurs in the Linux kernel’s IPv4 layer while processing TCP connection requests. Because it does not create a copy when transferring ownership of memory options between sockets, reference timing can become misaligned when multiple CPUs process retransmitted packets simultaneously. This leads to a use-after-free (UAF), in which already-freed memory is referenced again after the standard memory release function has been called.

    The flaw creates a short race-condition window that an attacker could exploit to take control of a system or install malicious code. The central issue is not ordinary application memory but the point where the kernel’s memory management and concurrency controls overlap. Because the same flaw enables both address disclosure and function-pointer tampering, the required patch is closer to a memory lifetime management fix than a simple reference correction.

    KASLR Bypass and Callback Function-Pointer Tampering

    The demonstrated attack proceeded in two stages against a Linux server with an MPTCP listener open. First, the UAF exposed internal kernel addresses, remotely bypassing KASLR. The attackers then used a buffer overflow to tamper with a callback function pointer and execute a preloaded payload. It took five minutes to obtain root privileges.

    Conventional kernel attacks can trigger a panic when they fail to manipulate memory or induce a race condition, resulting in server disruption and detection alerts. This attack, however, causes only the handshake to fail if unsuccessful, allowing the server to continue operating normally and the attempt to be retried thousands of times until it succeeds. In Anthropic’s actual demonstration, extracting addresses with KASLR protection enabled took 48 minutes, but the server remained operational.

    Broad Impact Across Ubuntu Servers

    The Linux kernel vulnerability affects Ubuntu releases across the board. Security advisories indicate that a broad range of enterprise server environments are exposed, spanning the legacy supported versions 16.04 LTS and 18.04 LTS, as well as 20.04, 22.04, 24.04 LTS, and the latest 26.10 release. Regardless of whether MPTCP listeners are enabled, organizations need to immediately compare their deployed kernels with their support status.

    Patch Applying kfree_rcu and AI-Assisted Verification

    The upstream Linux kernel and Ubuntu are distributing a security patch that applies kfree_rcu(), an RCU-based release function that defers freeing memory until concurrent read operations by other processes are complete. Administrators should check the patch status of deployed kernels and respond by installing the updated packages. The guidance also recommends making AI-assisted security code verification a permanent part of the development process, separate from production updates.

    Security experts consider it significant that AI designed a sophisticated kernel exploit chain almost autonomously, a process that previously could take months of painstaking work. As the cost and barrier to designing attacks decline, the speed of patch deployment and code verification becomes equally important. Responding to an AI-generated attack chain requires more than installing a new kernel; it demands a system for detecting the race conditions and memory lifetime issues identified by AI within the development pipeline.

  • iPhone Supply Delays: What’s Bottlenecking the Duo?

    iPhone Supply Delays: What’s Bottlenecking the Duo?

    Apple is smoothly ramping up production of its new foldable device, the iPhone Duo, but has warned that supply delays may continue in the near term. Chief Operating Officer Sabih Khan said during this quarter’s earnings call that the company is working to get the product to customers as quickly as possible, but it is difficult to predict when supply and demand will reach equilibrium.

    Sold Out and Next-Year Deliveries Signal Strong Demand

    As delivery dates for customers who waited at Apple Stores or placed preorders but did not order immediately slipped into next year, smartphone delivery delays are becoming a practical purchasing problem. Verizon has apologized for the delays and is offering customers gift cards.

    The Financial Times reported last month that Apple described demand for the iPhone Duo as “nothing short of extraordinary”. The product sold out on Apple’s official website within hours of its launch, and delivery dates were pushed back to the following year. This suggests that demand may have grown faster than the initial production plan, rather than simply reflecting a production delay.

    Structural Pressure From Memory Prices and Titanium Sourcing

    This delay is difficult to attribute to a production problem unique to Apple. Supply pressure and cost burdens have increased as surging demand for memory chips from the AI industry drove up component prices across hardware manufacturers. Khan explained that Apple has also raised the prices of several products and said the company made those decisions “reluctantly”.

    Titanium supply for the new foldable device has also emerged as a constraint. Apple is expanding its partnership with titanium producer Perryman to support Duo supply. As memory costs and specialty-material sourcing pressures overlap, the structure suggests that the bottleneck will not ease quickly just because manufacturers increase internal production.

    Normalization Will Depend on Production and Delivery Indicators

    Apple and executive John Ternus emphasized their efforts to get the Duo to customers as quickly as possible, but did not provide a specific timetable for improvement. The direction of future supply normalization should be assessed by tracking how long website inventory lasts, whether wait times for Apple Store purchases shorten, and when carrier delivery compensation declines.

    The central issue is that iPhone supply delays have expanded from a simple sales-timing problem into a broader supply-and-demand issue across the component chain. The likelihood of easing bottlenecks increases as production ramps up, but stable deliveries remain difficult to expect until both memory prices and titanium sourcing recover. Based on Apple’s official statements and additional reporting from TechCrunch, it is more realistic to observe the direction in which the bottleneck is moving than to predict an exact recovery date.

    Reference Sources

    This article was prepared by checking the following source: TechCrunch — Apple says it’s ‘hard to predict’ when iPhone Duo constraints will improve

  • AI-Built Apps Need Clear Owners and Secure Deployment

    AI-Built Apps Need Clear Owners and Secure Deployment

    The fact that an app built by a non-developer works smoothly can actually delay the discovery of a serious risk. If database connections and deployments remain active after the owner changes or leaves the company, the app will continue to run, but the organization may not know who owns it or where to recover it. In practice, internal app management should begin by creating an official deployment path that can be operated, not by blocking creation tools.

    In one real-world case, the marketing team contacted the engineering team about a dashboard that had stopped updating, but the engineers did not know the app existed. It had been built with Lovable, used a Supabase service key, and was deployed to a personal Vercel account. Its creator had already left the company. The app was still running, but for all intents and purposes, it had disappeared from the organization’s management system.

    Why an App List Alone Is Not Enough

    Personal-account deployments, fragmented databases, and long-lived service keys collectively create gaps in internal app management across different tools. Blocking only one tool merely encourages teams to move to another service. Prohibiting personal accounts without providing organizational accounts and a shared deployment path will likewise lead teams to find workarounds. Even registering an app’s name does not address database permissions, secrets, incident alerts, or recovery responsibilities.

    Therefore, code created with AI generation tools should be treated as code submitted through an approved pipeline. More important than the author or the tool used is the account from which the code is deployed, the data it can access, and who responds when it fails. Without this principle, every new generation tool adds another asset beyond the organization’s control.

    First Step: Establish a Controllable Deployment Path

    Managed apps should be organized under organizational accounts with team permissions, and projects created in personal accounts should be transferred to organizational projects. Deployment should occur through a shared CI/CD pipeline after code changes, tests, security scans, and database migration reviews and approvals. Build artifacts and deployment metadata should include an app identifier and owner information, making it possible to find the same details later during recovery or decommissioning.

    The CLI can first be used to identify which projects remain under the current account. The following commands are conceptual examples, and actual output will vary depending on account status.

    vercel projects ls
    vercel teams ls
    supabase projects list

    ※ Note: The following configuration and code are conceptual simulation examples (Illustrative Example, not official spec).

    Projects discovered in personal accounts should be checked for continued use and then transferred to organizational projects. Once the transfer is complete, existing deployments and data connections should be linked to the official asset inventory, and personal-account tokens should be revoked. Rather than applying blocking commands first, organizations should provide secure defaults, cost controls, and support channels so teams can choose the official path in practice.

    Second Step: Attach Responsibilities to the App Inventory

    An internal app inventory should record at least the app name, business purpose, users, data store, deployment account, creator, current owner, incident contact, secret storage location, backup and recovery method, and decommission status. Separating the business owner from the technical owner does not solve the problem. The business owner should determine priorities and intended use, while the technical owner is responsible for recovery and changes.

    Binding ownership and operational responsibility to an individual author creates a gap whenever that person changes roles. Departure events should trigger the revocation of SSO sessions, team memberships, API tokens, and database permissions. Handover procedures should include a test in which the replacement owner confirms receipt of real incident alerts. An empty mailing list is only an archive for notifications, not a substitute contact network.

    Third Step: Combine Secrets and Incident Response in One Loop

    Supabase service keys should never be left in personal environments or documents. They should be moved to a central secret manager and replaced with workload identities and short-lived credentials. Database permissions should separate read and write access, while deployment accounts should be reconciled regularly against the app inventory to remove unused keys and orphaned credentials.

    Monitoring should go beyond simple uptime checks. It should detect authentication errors, interrupted data updates, and backup failures, with alerts routed through existing on-call and ticketing systems. The app registry should record repository, deployment, data_store, monitoring_contact, lifecycle_status, and decommission_date so incidents, changes, and decommissioning remain connected in one workflow.

    A decommissioning process is also necessary. Based on business closure or the criteria for last use, the app’s status should be changed to retired, and deployments, DNS, data, secrets, and external integrations should each be reclaimed. Revoking database permissions while leaving data and configurations behind makes an inoperable app continue to appear as a managed asset. Conversely, blanket restrictions on AI tools do not solve the problem.

    The origin of this problem is also reflected in the original discussion. The original thread, which asks whether platform owners can inventory internal apps and who will detect and recover them during an incident, shows that the management gap has already become a real operational issue.

    Operating Principles Matter More Than Avoiding Anti-Patterns

    The most common failure is to create an app list without assigning an operational owner. The next failure is leaving service keys in plaintext or revoking only deployment and database access when an employee leaves. If personal accounts are prohibited without an official path, users will scatter across external SaaS platforms. Organizations should first provide secure organizational accounts and a shared pipeline.

    Implementation will inevitably require organizations to align cost allocation, SSO integrations, and cross-team approval criteria. Rather than abandoning controls, the practical approach is to move higher-risk assets to organizational accounts first and repeatedly test approval procedures and credential revocation. Internal app management does not end with counting generated code. It is an ongoing operational practice that keeps assets, data, deployments, secrets, and incident responsibilities connected.

    An initial review can begin by comparing the deployment platform’s project list and database list with the app inventory. Projects remaining in personal accounts should be checked for use and transferred to organizational projects, while apps with unclear ownership should be assigned both a business owner and a technical owner. Service keys stored in personal environments should be moved to a central secret management system and replaced with workload identities and short-lived credentials. Deployment, authentication, data update, and backup status should be monitored through a single on-call path and confirmed directly by the replacement owner. When an employee leaves or a business closes, account sessions, API tokens, database permissions, DNS, data, and secrets should be reclaimed together.

    Practical Implementation Points

    • Coordinate with relevant teams and confirm the approval path
    • Test potential impact in an isolated environment beforehand
    • Establish a phased rollout and emergency rollback plan