Key Summary
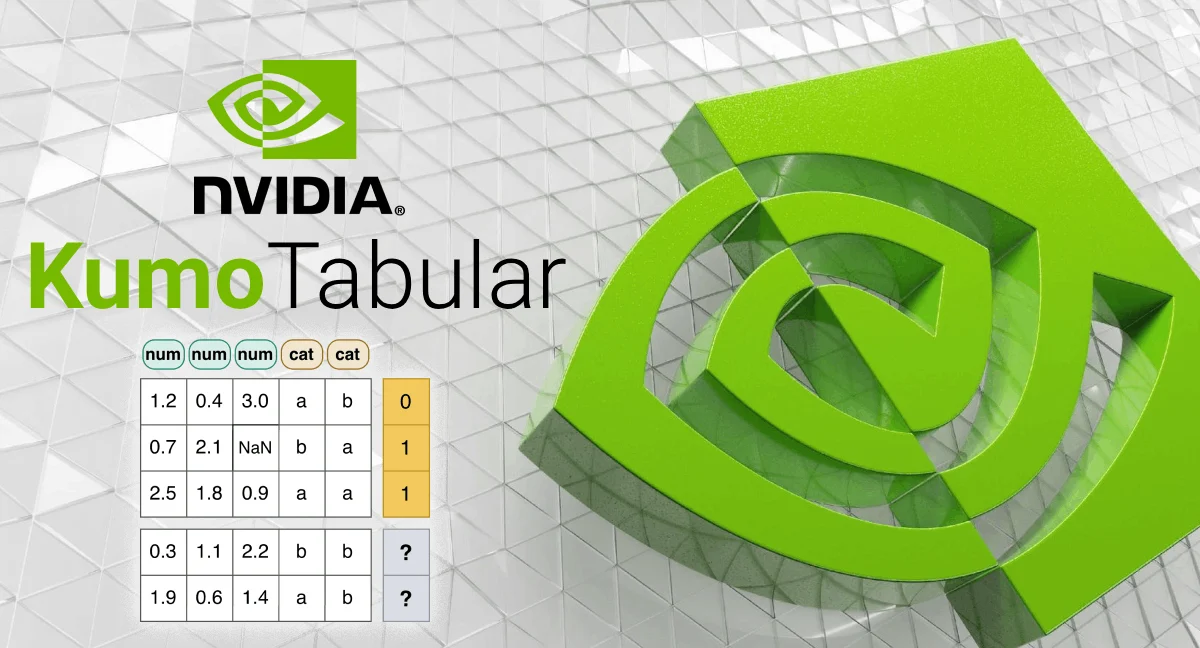
- Kumo Tabular is an open tabular foundation model that takes labeled rows as context and predicts labels for new rows in a single forward pass, handling both classification and regression without any training, hyperparameter tuning, or feature engineering.
- Based on the source material, the training data is limited to artificial data, and three model sizes are offered ranging from 28M to 215M parameters.
- It is distributed as an open-source library under the OpenMDW-1.1 license, which permits commercial use.
An analytical guide that organizes a newly released tabular foundation model from the perspective of a practitioner who wants to try it immediately, while also flagging how the workflow shifts compared with the existing gradient boosting flow and what remains unverified.
Table of Contents
Kumo Tabular takes labeled rows as context and predicts the label of a new row in a single forward pass. No training, no hyperparameter tuning, no feature engineering. Released by NVIDIA on Hugging Face, Kumo Tabular is an open tabular foundation model that handles classification and regression through the same interface.
It is hard to deny that gradient boosting trees (GBDT) have been the standard for structured-data prediction in industry for the past 20 years. XGBoost, LightGBM, CatBoost — virtually every organization has at some point followed the formula of “tabular data = GBDT.” Data preprocessing → training → tuning → validation → deployment, a five-step formula whose stability is now in question. The author views this point as the most meaningful aspect. It is an event where the workflow changes, not just the model itself.
What Kumo Tabular Takes In and Puts Out
The input is a bundle of labeled rows, that is, a context table. The output is a prediction for a new row. The model connects the two without any separate training. It belongs to the in-context learning family alongside TabPFN and TabICL, and is reminiscent of how LLMs perform new tasks from prompts alone.
Whether classification or regression, it ends with the same call. Binary classification like churn or default, continuous-value regression like revenue, demand, or price — all of it in a single forward pass. For practitioners, think of sklearn’s fit/predict API, but with the fit step removed.
Three Kumo Tabular Variants — Size and License
According to the source, three variants have been released, ranging from 28M to 215M parameters. The exact middle size is not specified. All variants follow the OpenMDW-1.1 license and are accessible on both GitHub and Hugging Face as part of the NVIDIA Kumo Structured model collection.
| Variant | Parameters | Estimated Use Case | License |
|---|---|---|---|
| Small | ~28M | On-device / lightweight inference | OpenMDW-1.1 |
| Medium | Mid-scale (undisclosed) | General server inference | OpenMDW-1.1 |
| Large | ~215M | High-quality prediction / batch | OpenMDW-1.1 |
The parameter count is small compared with GBDT, but the entire context must be re-fed for each inference. Latency can grow if GPU resources are insufficient.
Open Source Ecosystem — Simultaneous Release on Hugging Face and GitHub
Kumo Tabular was introduced on the official Hugging Face blog. The OpenMDW-1.1 license permits commercial use, so it can be embedded into internal services or products without a separate agreement. It shares the same direction as other model families NVIDIA released around the same time — NVIDIA SoL-Pi, NVIDIA PAIR. While expanding its lineup toward local inference infrastructure and agent harnesses, NVIDIA has applied the same philosophy to the structured-data domain.
#1 on 4 Benchmarks — But the Single-Source Caveat Must Be Noted
The source claims first place on four benchmarks: TabArena, BeyondArena, TALENT, and ScoringBench. The core point is that a model pre-trained on artificial data outperformed GBDT on real-data-based benchmarks. However, it is difficult to independently cross-verify these figures using only the materials gathered for this analysis. Organizations evaluating adoption should look beyond the “#1” label and first examine “on which data distribution the #1 was achieved.”
The First-Contact Workflow for Practitioners
The first task that comes to mind is one where a labeled table already exists. Churn prediction, default classification, short-term demand forecasting, price regression — any task that has been labeled at least once in the past can be fed in as context rows to receive immediate inference.
Applying it directly to data with no labels or where column meanings change frequently is difficult. There are likely constraints on the number of context rows and columns, and because the entire context must be re-fed for each inference, the structure is not well suited to large-volume batch processing. From a practitioner’s perspective, the most reasonable choice for the first PoC step is “the smallest table you have that already has labels.”
Differences When Compared with the GBDT Workflow
In the XGBoost/LightGBM workflow, five steps consumed the time of a single data scientist. Kumo Tabular effectively removes the training and tuning steps from that list. In their place, data governance — which labels may enter the context, how PII is masked, and how often the context is refreshed — takes on greater weight.
The cost structure also changes. Because every prediction requires GPU inference, the model shifts from a “one-time training cost” to an “N-times inference cost.” For low-traffic tasks, costs can actually rise.
Practical Application Points
- Start with a task where a labeled table already exists, feed it as context, and run a PoC that returns a single-forward-pass result.
- Measure accuracy, latency, and cost on the same holdout as the GBDT baseline. The gap on your own data matters more than any #1 benchmark figure.
- Check the model card for the upper limits on the number of context rows and columns, and verify in advance whether large-volume batch processing is feasible.
- Have the legal team review the obligations of OpenMDW-1.1 once more. Attribution requirements and redistribution restrictions are the key points.
- Redesign the budget structure — which assumed a one-time training cost — around N-times inference cost for GPU-based inference.
What to Try Right Now
- Open the NVIDIA Kumo Tabular model card on Hugging Face and check the parameter count for each variant along with the full license text.
- Pick one internal churn / default / demand dataset and feed 5,000–50,000 labeled rows as context to obtain a single-forward-pass result.
- Compile a comparison table against LightGBM with default hyperparameters on the same holdout. Use three axes: accuracy, prediction time, and GPU memory usage.
- Ask the data governance team whether PII columns are included in the context, and if so, how the masking policy should be structured.
- Review the full text of the OpenMDW-1.1 license together with the in-house legal team and reach a conclusion on whether it can be embedded into commercial services.
Frequently Asked Questions
Can Kumo Tabular fully replace XGBoost?
It is too early to conclude based on the source alone. The claim of #1 on four benchmarks does not mean a model pre-trained on artificial data is also superior on real distributions. A direct comparison on the same holdout must come first.
Does it support both classification and regression?
According to the Hugging Face blog, it predicts both classification and regression in a single forward pass. There is no need to separate the model call.
Is it available for commercial use?
It is distributed under the OpenMDW-1.1 license, which permits commercial use. However, there may be obligations, so reviewing the full license text is essential.
How does Kumo Tabular differ from TabPFN and TabICL?
All three belong to the in-context learning family. While TabPFN and TabICL are part of the academic/research stream, Kumo Tabular is a model designed with commercial distribution in mind within NVIDIA’s lineup, which sets it apart in character.
It is still too early to declare that Kumo Tabular has fundamentally shifted the paradigm of tabular ML. There are many unverified areas: the actual upper limit on the number of context rows, how well pre-training on artificial data generalizes across domains, and the break-even point at which GPU inference cost exceeds the one-time training model. Until these three are clarified, any claim of “GBDT replacement” is premature. Even so, it is a meaningful starting point as an experiment for practitioners. If you already have a labeled table in-house, it is worth running once this week.
Source Reference
This article was written after checking the following source: Hugging Face Blog — NVIDIA Kumo Tabular Sets a New Accuracy-Efficiency Frontier for Tabular Prediction