Tag: 구글 AI

  • 5 Takeaways from the Gemini Argon Launch — Google Returns to Center Stage with a Cybersecurity-Focused Model

    5 Takeaways from the Gemini Argon Launch — Google Returns to Center Stage with a Cybersecurity-Focused Model

    Key Takeaways

    • Google’s parent company Alphabet unveiled ‘Gemini 4 Argon,’ emphasizing it as the company’s most powerful model
    • Argon is designed to handle a wide range of tasks including coding, research, and writing, with Google highlighting particular strengths in cybersecurity defense work
    • In the security domain, it is marketed with the ability to ‘autonomously detect, validate, and patch critical software vulnerabilities,’ with emphasis on its defense-focused training

    An article analyzing the background behind Google’s decision to spotlight cybersecurity and coding — practical domains — with its new model ‘Argon,’ and the strategy of framing it as a benchmark competition with OpenAI, Anthropic, and others

    Table of Contents

    Gemini Argon is a new frontier model unveiled by Google’s parent company Alphabet on September 30. Described by Google as ‘its most powerful model yet,’ the model is weighted toward cybersecurity defense and coding (TechCrunch report). With OpenAI’s Astra and Anthropic’s Fable/Operus having also lifted the veil around the same time, Gemini Argon reads not merely as a new model announcement but as a message that ‘Google is back at the center of the stage.’

    Gemini Argon’s Cybersecurity Defense — The Weight of the ‘Autonomous Vulnerability Patching’ Claim

    Google introduced Gemini Argon as capable of ‘autonomously detecting, validating, and patching critical software vulnerabilities.’ It emphasized that the model is specialized for defense training rather than offensive use. For practitioners, the word that stands out is ‘validate.’ LLMs that identify candidate vulnerabilities already exist. The moment a single model runs the loop of verifying whether a candidate is a real threat, drafting the patch, and applying it, the cost structure of first-line triage for security teams can itself be shaken up.

    However, the initial rollout is phased out only to select cyber partners through a security initiative called the ‘Fairwind Program.’ This means everyday users cannot immediately knock on the API. While Google leans into the framing that it ‘prioritizes trust and safety,’ it is also effectively a strategic choice to control the first user pool.

    Gemini Argon’s Coding/Engineering and ‘Long-Horizon Reasoning’ Appeal

    Gemini Argon is designed to handle a wide range of tasks including coding, research, and writing, with the ability to sustain deep reasoning across long workflows as a key differentiator. The public blog includes the phrase ‘designed to sustain deep reasoning across complex, long-running workflows.’ As a concrete example, the company noted that its own employees are already using it for debugging and codebase migration. Maintaining context across days-to-weeks-long tasks like migration — not single-line debugging — suggests that the yardstick for model evaluation is shifting from ‘accuracy rate’ to ‘project completion rate.’

    On the multimodal side, long-form video analysis and chart parsing capabilities were also highlighted. Because it handles not just text and images but also temporally extended video, natural touchpoints emerge with security work such as operational monitoring and incident response log review.

    The Politics of Benchmarks — The Name ‘Vals’

    Google claimed that Gemini Argon scored higher than OpenAI’s GPT-6 Astra and Anthropic’s Fable/Operus across a range of benchmarks. The cited source, however, is interesting: it’s the model index from an AI benchmark startup called ‘Vals.’ Vals is a benchmark provider whose adoption is growing in the industry, but unlike established LMSYS or academic benchmarks, its structure has some model-company collaboration in the selection of evaluation sets and the application of weights. Teams evaluating Gemini Argon for adoption should not look at the score sheet alone, but also examine the composition of the evaluation set and the conditions of application.

    Item Gemini Argon OpenAI GPT-6 Astra Anthropic Fable/Operus
    Key Strength Cybersecurity defense, long-horizon reasoning General-purpose reasoning, the company’s best Safety, reasoning specialization
    Distribution Method Fairwind Program (controlled phases) Public via own channels Public via own channels
    Benchmark Citation Vals model index Based on own announcement Based on own announcement
    Multimodal Highlight Long-form video, chart parsing Based on own announcement Based on own announcement

    The Re-Entry Narrative Atop a Billion Users

    Google was once considered to have ‘fallen behind’ in the AI race. However, with the Gemini app surpassing 1 billion monthly users as of August, the company is pursuing a strategy of placing Argon atop its recovery trajectory. This number is not simply a MAU figure — it means another player that holds both ‘consumer touchpoints’ and a ‘top-tier model’ has emerged. In that same September, OpenAI’s Astra and Anthropic’s Fable unveiled in succession. As examined in the 3 Questions on GPT-6 Astra, the September new model competition has already entered a ‘speed war’ mode.

    The author sees this as the most meaningful point. Comparing model cards is not difficult. What is hard is deciding through which distribution channel, with which safety framework, and at which price point to release the model. Gemini Argon shows Google’s answer to that hard question — controlled rollout, defense specialization, long-horizon reasoning. And in that same September, that answer does not stand alone.

    What to Try Right Now

    • If your in-house security team is evaluating LLM adoption, check the partner eligibility requirements for the Gemini Argon Fairwind Program and review participation feasibility within one week.
    • If you are comparing LLM candidates for debugging/migration use in coding workflows, add Gemini Argon to your evaluation criteria under ‘long-context retention.’
    • When sharing benchmark materials with your team, attach not only the score sheets but also the composition of Vals’ evaluation sets and weighting information.
    • If you are designing a multimodal PoC, include context retention time on long-form video input as a separate measurement metric.
    • Create an internal wiki document that consolidates OpenAI, Anthropic, and Google models into a single comparison table covering licensing, distribution channels, safety policies, and pricing units.

    Practical Application Points

    • Defense-specialized trained models imply that guardrails against attack scenarios are built in — this does not mean misuse potential is zero. Do not eliminate the human review stage during SOC operations.
    • Long-horizon reasoning is different from a large context window. In the PoC stage, verify not token count but whether tool calls, file references, and session resumption are supported.
    • Benchmark scores are ‘snapshots.’ For the same model, real-world results can vary significantly depending on system prompt, temperature, and chaining method.
    • When evaluating a controlled-rollout model, include ‘when will it be released to general channels’ in your question list and divide scenarios into short-term, mid-term, and long-term adoption.

    Frequently Asked Questions

    Can regular developers use Gemini Argon right away?

    Initially, it is being rolled out in phases only to select cyber partners through the Fairwind Program. General users should check the official channel opening schedule separately.

    It’s described as for security defense — can it also be used for attacks?

    Google emphasized that it is trained with a defense focus. However, given the nature of LLMs, ethical and legal issues vary depending on the use case, so you must check the terms of service and availability policy when adopting.

    How is this different from previous Gemini models?

    Gemini Argon is positioned as the company’s most powerful model, citing differentiators in long-horizon workflow reasoning and multimodal processing. For precise specifications, it is best to consult the official model card.

    Can the Vals benchmark be trusted?

    Vals is seeing growing industry adoption, but there is insufficient standard consensus on the selection of evaluation sets. Rather than comparing scores alone, look at the composition of evaluation items and the conditions of application together.

    Reference Source

    This article was prepared after reviewing the following original source: TechCrunch — Google releases Gemini 4 Argon, called its most powerful model yet
  • TimesFM-3: Google’s Next Move Aiming 330M Parameters at Multivariate Time Series

    TimesFM-3: Google’s Next Move Aiming 330M Parameters at Multivariate Time Series

    TimesFM-3
    Google AI’s time series foundation model ‘TimesFM-3’ release and the shift to multivariate forecasting

    Key Summary

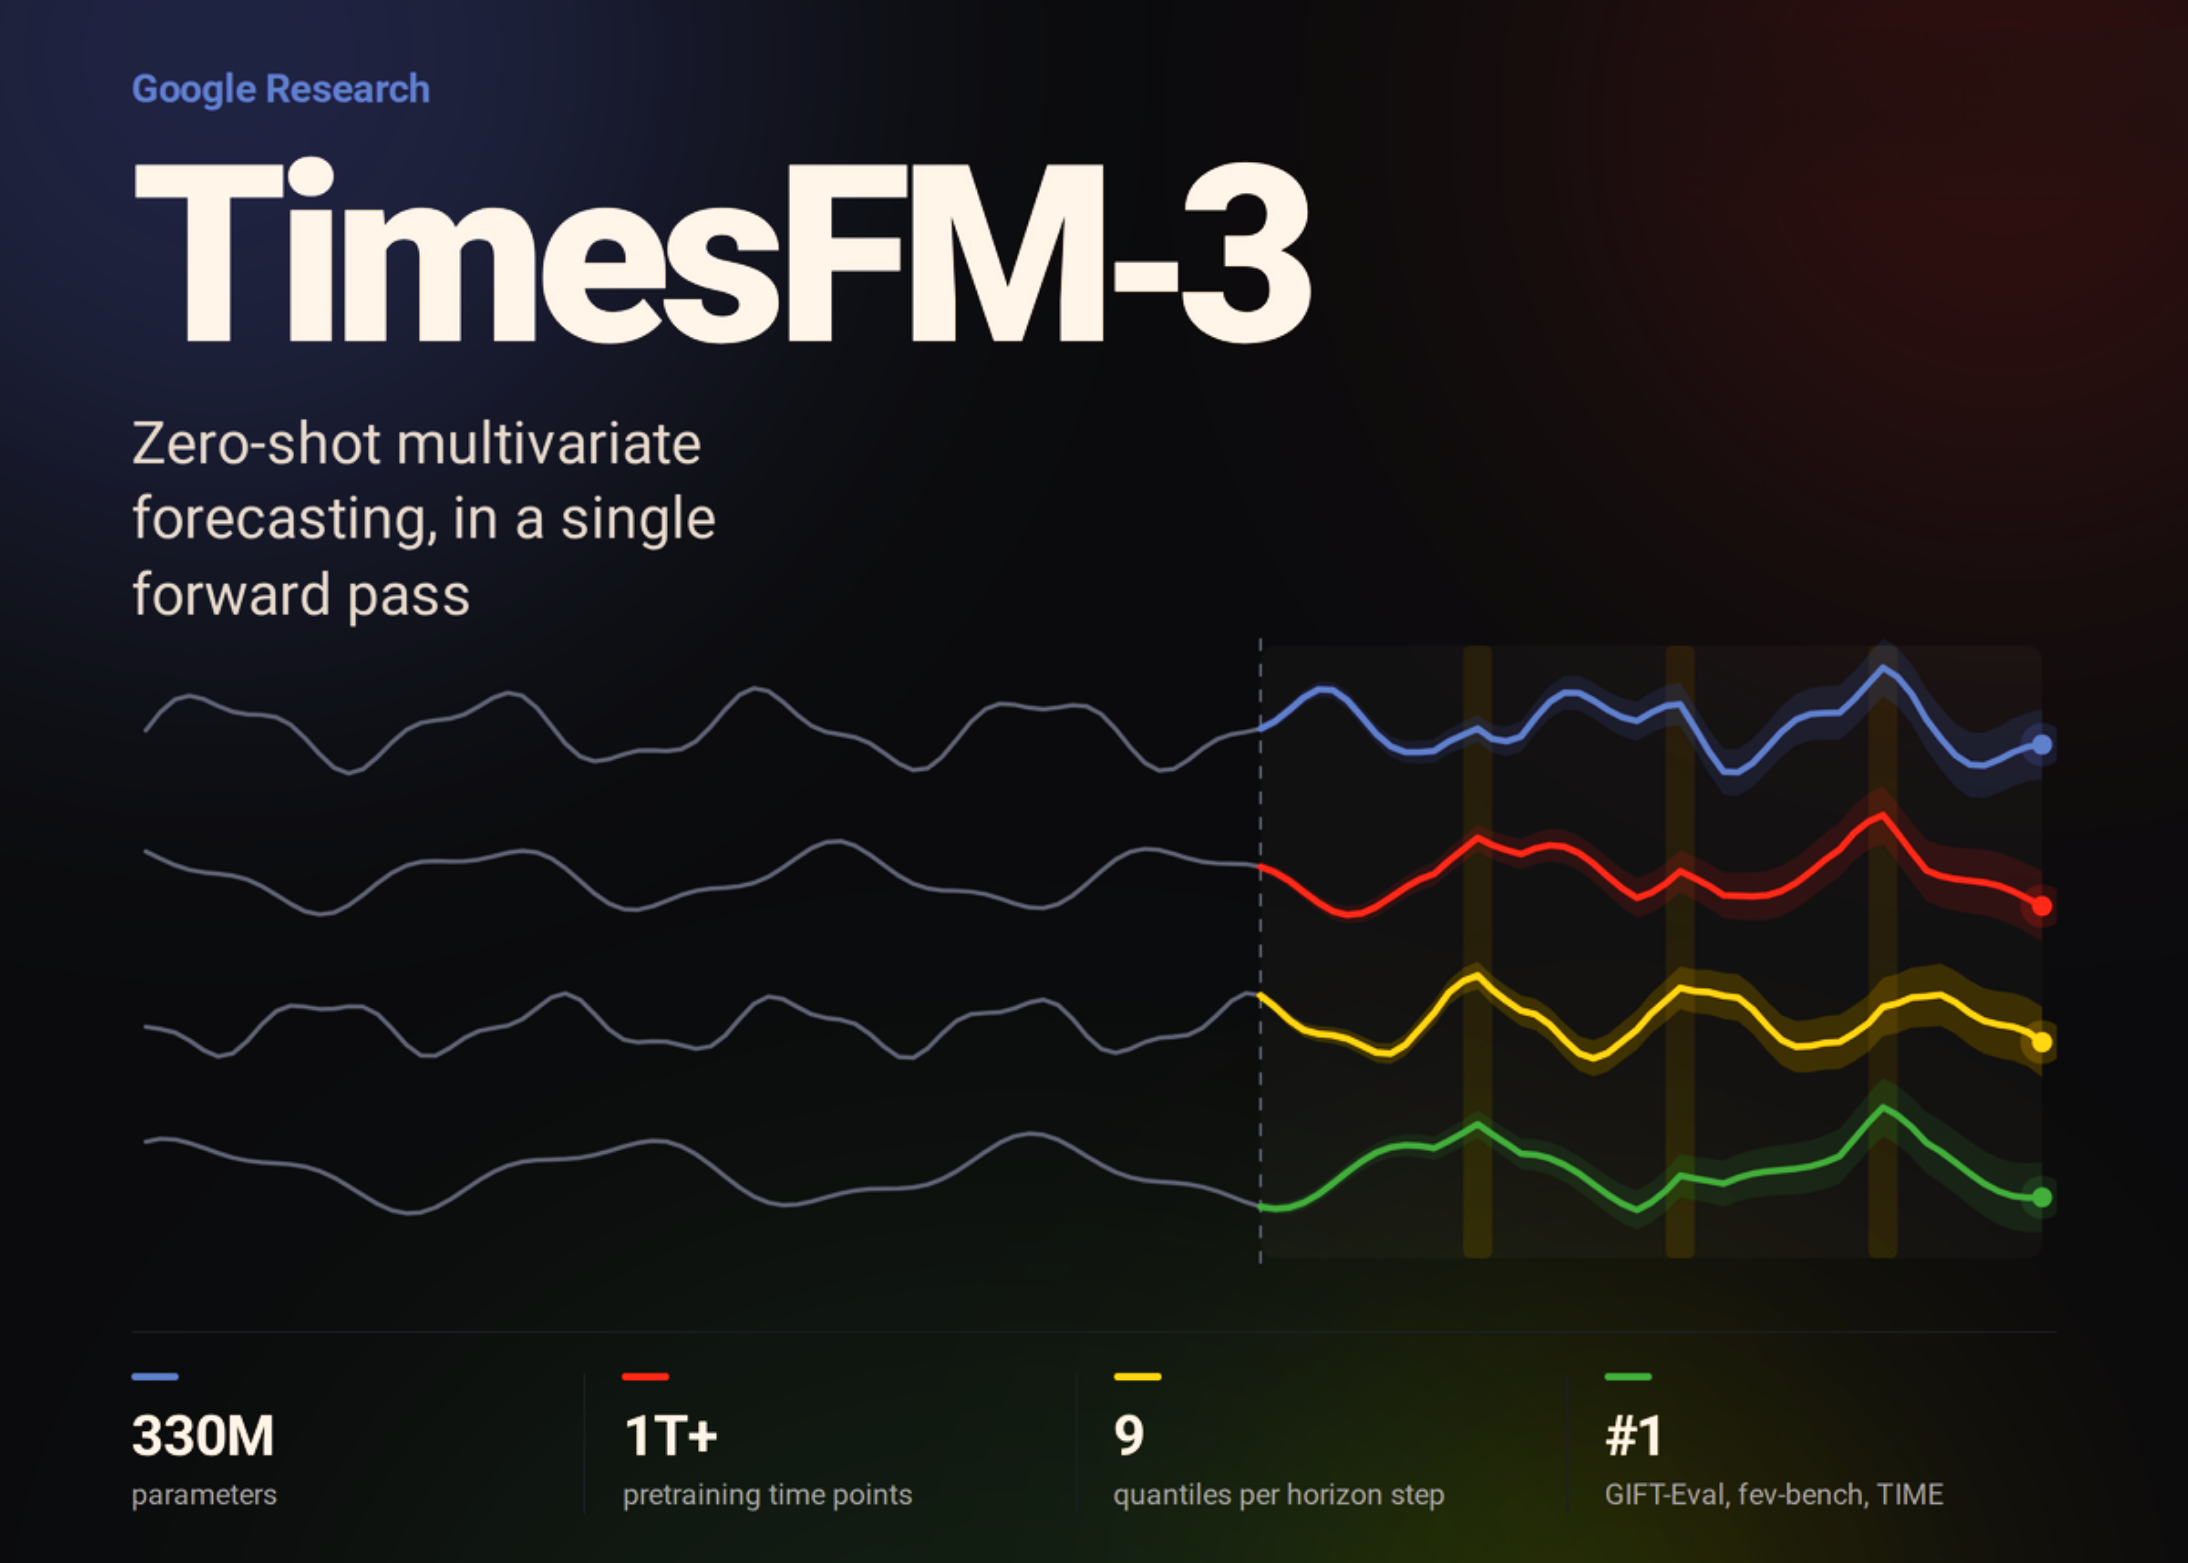
    • TimesFM-3 is a 330M-parameter time series foundation model that predicts multiple related time series simultaneously in a single forward pass.
    • Every TimesFM checkpoint up to 2.5 was univariate-only, but TimesFM-3 was pretrained from scratch for multivariate forecasting.
    • It was pretrained on real and synthetic time series data spanning over 1 trillion time points and accepts multiple targets, past covariates, and past-future covariates in a zero-shot manner without per-task fine-tuning.

    Analysis

    Table of Contents

    The Multivariate Era Declared by TimesFM-3

    To define TimesFM-3 in one sentence: it is Google’s new foundation model that takes multivariate time series as zero-shot input with 330M parameters and forecasts multiple related series at once in a single forward pass. The point I find most significant here is that every TimesFM checkpoint up to 2.5 was univariate-only. Earlier versions forecast a single series—temperature or revenue—independently, forcing practitioners to hand-engineer the correlations between variables into the model every time. TimesFM-3 marks a clean break because it is the first version designed as multivariate-native from the ground up.

    Core Changes in TimesFM-3: 1T Time-Point Training and Zero-Shot Covariates

    Let’s start with the core numbers. 330M parameters, pretraining on real and synthetic data across more than 1 trillion time points, with the decoder-only transformer retained. The model size itself is not a dramatic shift from before, but the training data scale and input design are fundamentally different. The most striking change is how it handles covariates. It accepts multiple targets, past covariates, and past-future covariates in a zero-shot manner, without any separate fine-tuning. In other words, the model performs forecasts while taking known-future signals—such as the weather forecast saying “it will rain tomorrow”—into account.

    Three Architectural Highlights

    As I dug into the architecture, three elements stood out from a practitioner’s perspective.

    • 32-Step Patch Tokenizer: Consecutive time points are grouped into 32-step patches, reducing the transformer input length. Because each series is normalized independently, scale differences (e.g., revenue in the millions and conversion rates between 0 and 1) don’t introduce cross-channel noise.
    • 2D Grid Attention: Input tokens pass through a 2D grid (series axis × time axis) and are processed by two alternating attention mechanisms. This separates inter-variable dependencies from temporal patterns during learning.
    • Lookahead Covariate Encoding: Past-future covariate tokens are input by combining the current patch with future patches. This is the part of the design that lets the model be aware of scheduled events in advance.

    This structure is reminiscent of the data-flow separation thinking discussed in the 6 AI chip architectures piece. How you slice a time series’ “data” and where you reassemble it is what determines performance.

    Benchmarks: First Place Across All Three

    Evaluation was carried out on three fronts: the GIFT-Eval, fev-bench, and TIME leaderboards. Across all three benchmarks, it achieved the highest average rank among pretrained foundation models on both point metrics and probabilistic metrics. What is especially interesting is the first-place finish on probabilistic metrics as well. Existing foundation models often do well on point predictions but tend to be weak at estimating uncertainty distributions. TimesFM-3 appears to learn covariance structures more naturally because it takes multivariate input from the ground up.

    TimesFM Series Comparison

    Item TimesFM-2.5 TimesFM-3
    Parameters ~200M 330M
    Input Design Univariate Multivariate native
    Covariates Not supported Past and future covariates, zero-shot
    Benchmarks Single leaderboard First place on GIFT-Eval, fev-bench, and TIME
    Weight License Research use timesfm-non-commercial-v1.0

    The Asymmetry of the TimesFM-3 License

    The repository code is Apache-2.0. In other words, the code can be freely reviewed and modified. The problem lies in the weights. The TimesFM 3.0 weights are distributed under the timesfm-non-commercial-license-v1.0. According to the detailed MarkTechPost report, benchmark evaluation is permitted, but deploying the model into a production forecasting API is not allowed under the license.

    This is similar to the strategy Meta has taken with Llama in the LLM space: open up research while keeping commercial advantage for itself. Even if a data science team files a report saying “Let’s adopt TimesFM-3,” the legal team is likely to flag it first, because hosting the weights as-is in a service would constitute a license violation. This asymmetry will be the biggest variable shaping how Korean companies approach adoption going forward.

    Questions for Practitioners

    For a multivariate time series foundation model to matter in practice, it ultimately has to prove two things. First, it needs a cost-of-operation advantage over traditional statistical models (ARIMA, Prophet) or lightweight ML approaches (LightGBM). Second, forecast quality must be preserved when input variables are added or removed, without retraining. TimesFM-3’s zero-shot design is itself an attempt to answer the second question, while the first will only be settled as cases accumulate showing “accuracy improved once we added covariates.”

    That said, because the weights are closed, Korean companies are effectively blocked from fine-tuning them to build internal models. Workarounds such as continued training on synthetic data or distillation are likely to dominate the conversation. This trend connects with the LLM circumvention strategies covered in the Guardbreaker analysis. When a model’s weights are closed, differentiation ultimately happens in input design and data processing.

    Practical Application Points

    • Before evaluating TimesFM-3, first ask whether “a single variable is enough” in your own forecasting pipeline. Without verifying that multivariate dependencies actually exist, there will be no cost-to-benefit gain.
    • Prepare internal data in advance that could serve as covariates. Draft a candidate list of past and future covariates—promotion schedules, price changes, holiday flags—and it will help regardless of which model you end up choosing.
    • Note that the weight license is non-commercial. For production deployment, check the Google Cloud TimesFM API route, and if self-hosting is required, keep the door open for a separate license negotiation.
    • Prioritize backtest results on your own dataset over benchmark scores. Even a first-place finish on GIFT-Eval can vanish when domain-specific patterns in wholesale, retail, or manufacturing differ.

    What to Try Right Now

    • Clone the TimesFM code from the GitHub repository and review the architecture and input interface within the Apache-2.0 scope.
    • Build a multivariate input shape (multiple targets + covariates) using 5–10 of your own time series.
    • Run a backtest over the same period against your existing univariate model and produce a comparison table of MAPE and CRPS.
    • Check whether the TimesFM API is exposed on Google Cloud Vertex AI, along with pricing, SLA, and quotas.
    • Ask the legal team in advance whether running an internal PoC on non-commercial weights is permissible.

    Frequently Asked Questions

    How is TimesFM-3 different from the previous TimesFM-2.5?

    The biggest difference is input design. Up to 2.5, only univariate input was accepted, but TimesFM-3 takes multivariate input from the start. It handles multiple targets and past-future covariates in a zero-shot manner.

    Can I download the weights and use them in a commercial service?

    No. The weights are distributed under timesfm-non-commercial-license-v1.0, which restricts commercial and production use. Only the code is Apache-2.0.

    Which evaluation gave it the first-place finish?

    It ranked first on both point and probabilistic metrics among pretrained foundation models across all three leaderboards: GIFT-Eval, fev-bench, and TIME.

    Can Korean companies start using it right away?

    Direct self-hosting of the weights is restricted by the license. The code and interface are open, so it can be used for PoCs and research, but commercial production requires going through the Google Cloud API route.