Key Summary
- Release scale: Six models—375B-A23B, 36B-A4B, 32B, 7B, 3.7B, and 0.9B—all simultaneously distributed under Apache 2.0 on Hugging Face (the 0.9B uses a smaller vocabulary)
- Open stack included: Beyond model weights, the release ships the pretraining corpus, intermediate checkpoints, training code, configuration files, and detailed logs—IFM describes this as “the largest fully open-source release in AI history”
- Training data: All six models were pretrained on approximately 20 trillion tokens, of which about 17% consists of explicit reasoning traces, and roughly 10 trillion tokens are synthetic data
An analytical article examining what it means—for technology, licensing, and commercialization—when a large language model is released as a full-stack open-source project, and what it implies in practice to run the same architecture consistently from 0.9B to 375B.
Table of Contents
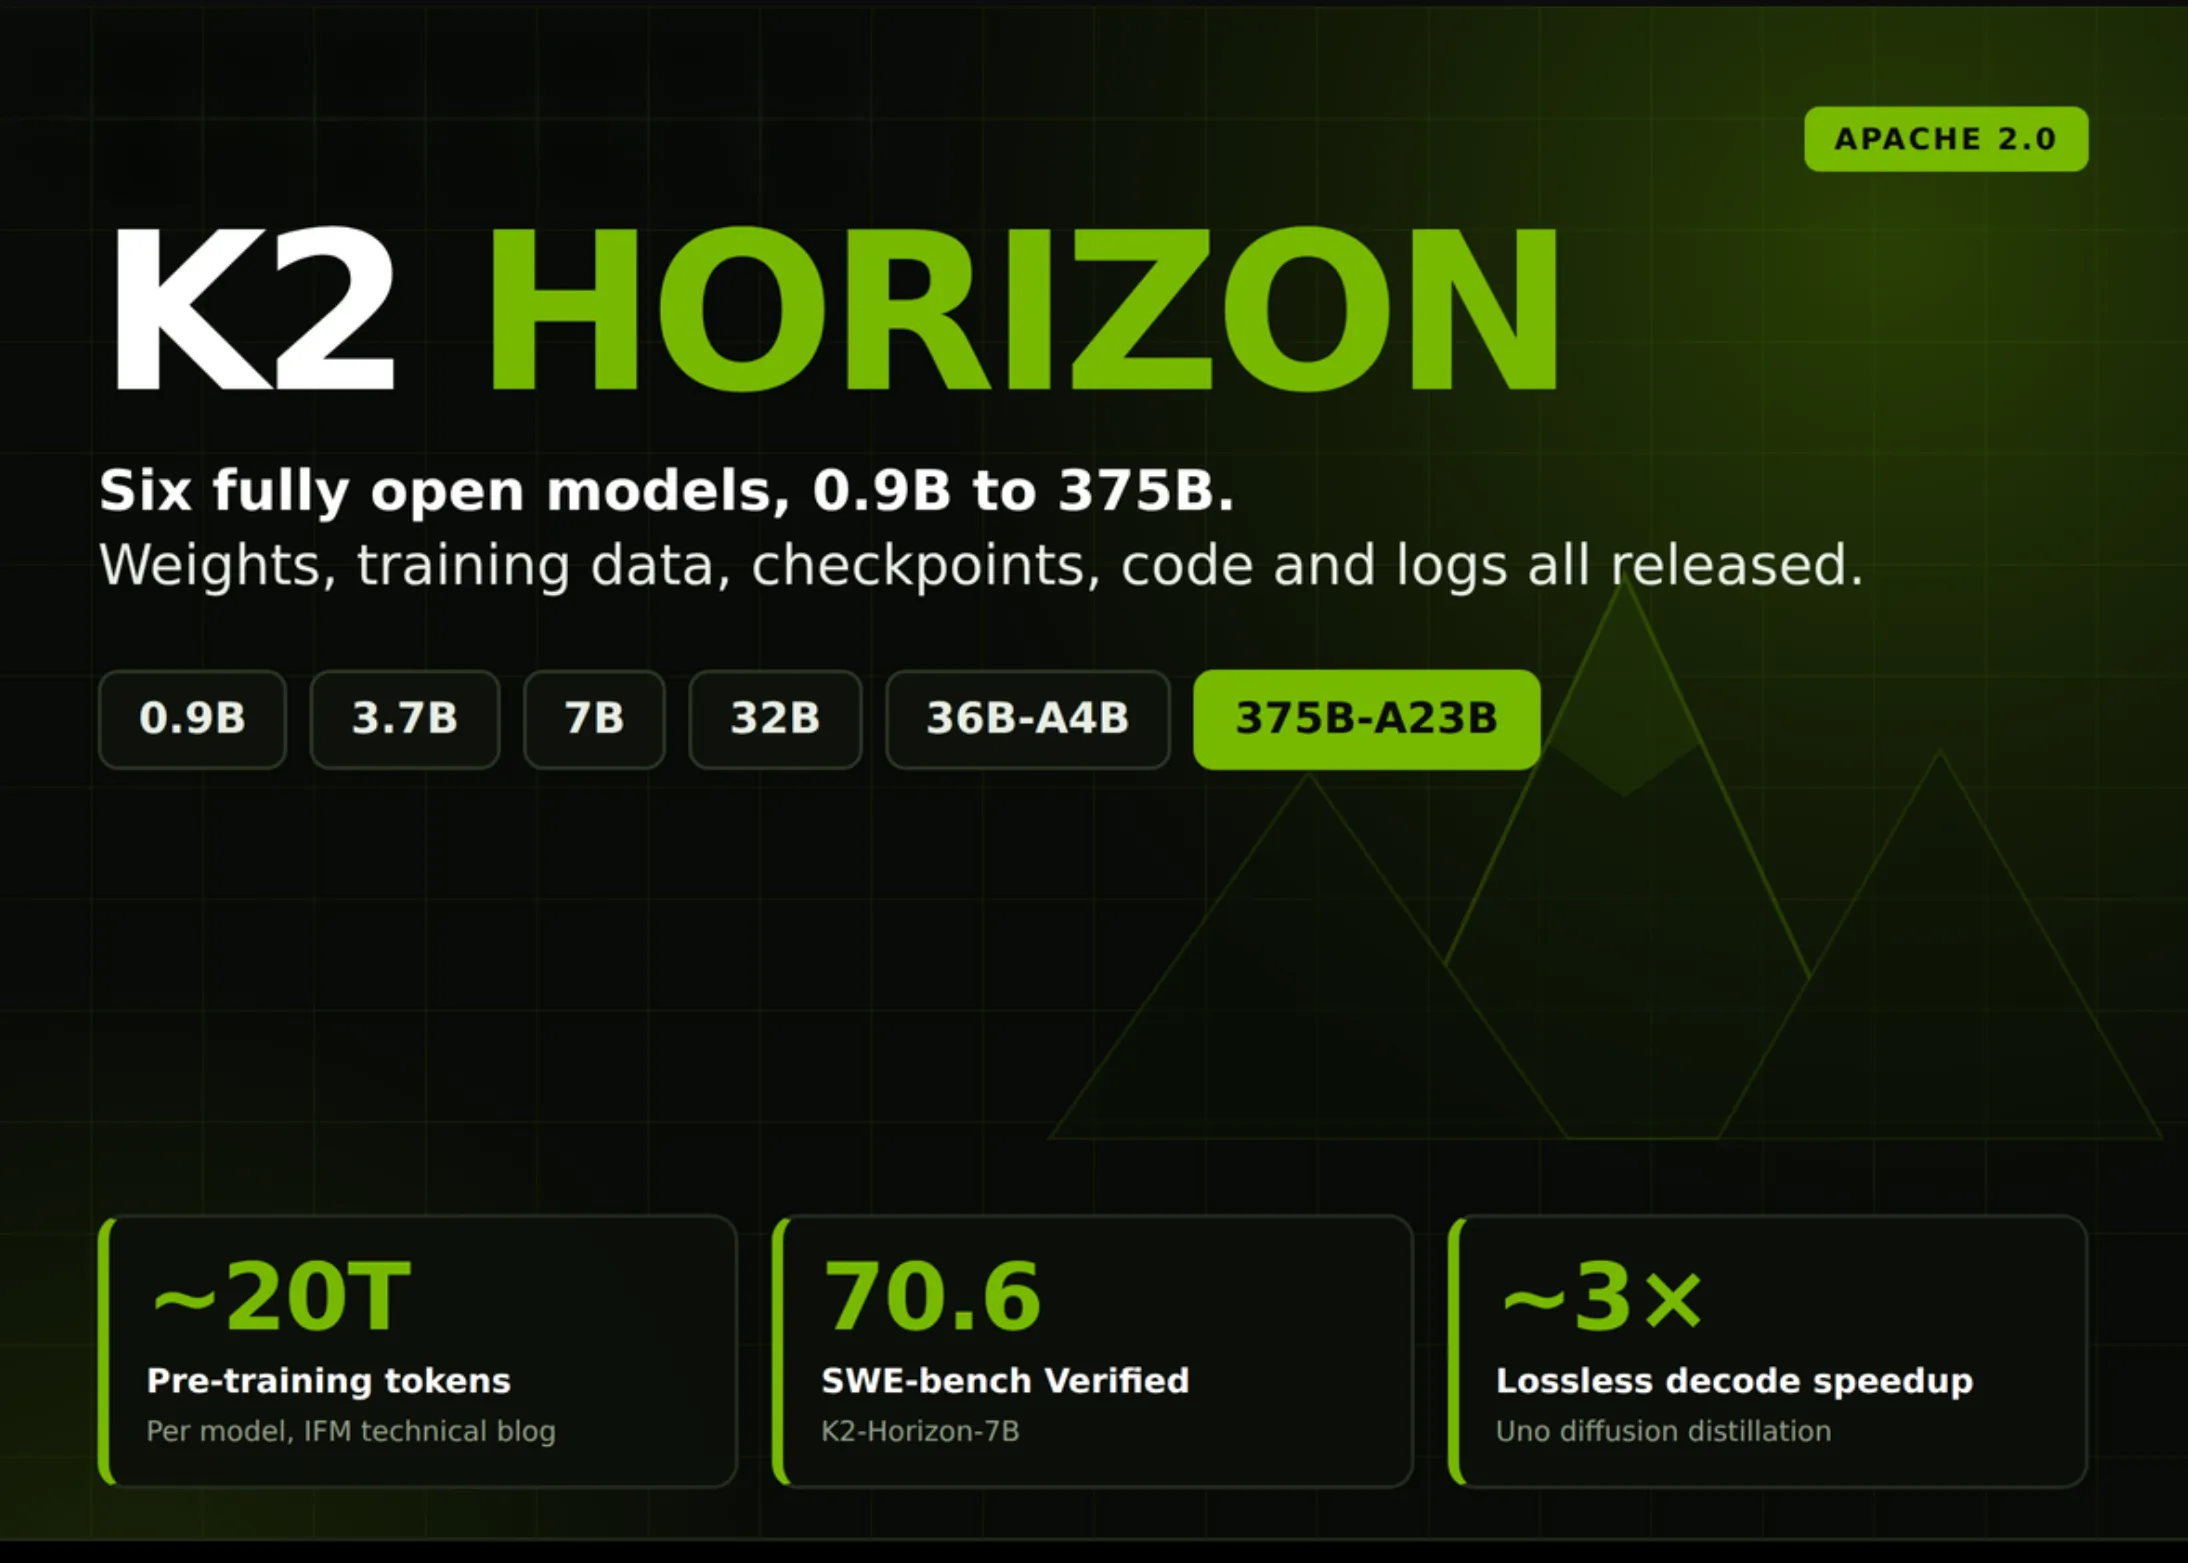
The fact that K2 Horizon released six models ranging from 0.9B to 375B under Apache 2.0 on the same day forces us to revisit what it means for a large language model to be open-sourced as a full stack. The bundle published in September 2026 by the Foundation Model Institute (IFM) under MBZUAI is not a single model but a “fleet” that ships the pretraining corpus, intermediate checkpoints, training code, configuration files, and detailed logs together.
In the author’s view, the core of this announcement lies not in model size or benchmark scores but in the scope of openness. The fact that even the 0.9B model’s use of a smaller vocabulary is explicitly stated means that the same training pipeline can be repeated by varying only the scale. The ability to use an identical interface across sizes in practice becomes a prerequisite for unified operations.
K2 Horizon Lineup: From 0.9B to 375B-A23B
The lineup is divided into six models. The 0.9B uses a reduced vocabulary, while the 3.7B, 7B, and 32B are dense. The 36B-A4B and 375B-A23B are MoE configurations. Because all models share the same tokenizer and tool-calling interface, the same code can be run by switching only the model identifier.
| Model | Total Parameters | Active | Type |
|---|---|---|---|
| 0.9B | 0.9B | 0.9B | Reduced-vocab dense |
| 3.7B | 3.7B | 3.7B | Local-inference dense |
| 7B | 7B | 7B | General-purpose dense |
| 32B | 32B | 32B | High-quality generation dense |
| 36B-A4B | 36B | 4B | MoVA MoE |
| 375B-A23B | 375B | 23B | Flagship MoE |
Because all six K2 Horizon models pass through the same synthetic-task generator and are trained with the same reasoning-trace ratio (about 17%), data alignment is applied consistently across the entire lineup. There is a high probability that a prompt format validated on the 0.9B will not break significantly when ported to the 375B-A23B.
The Scope of the Open Stack Brought by K2 Horizon
IFM used the phrase “the largest fully open-source release in AI history.” The K2 Horizon distribution bundle includes the pretraining corpus, intermediate checkpoints, training code, configuration files, and detailed logs. Compared with other open-source projects that release only weights and inference code, the scope is on a different level.
The release of intermediate checkpoints is directly tied to reproducibility. While retraining the 375B-A23B from scratch is difficult, you can continue fine-tuning from an intermediate stage or run ablations. In effect, the surface needed to experiment by varying the synthetic-data ratio or the reasoning-trace ratio is now secured.
Training Data Design: 20 Trillion Tokens, 100M+ Tasks
All six models were pretrained on approximately 20 trillion tokens, of which about 17% consists of explicit reasoning traces, and roughly 10 trillion tokens are synthetic data. The research team generated more than 100 million unique synthetic tasks and progressively incorporated post-training data during the middle-training stage.
The point practitioners should pay attention to is the scale of the synthetic tasks—the most striking number in the author’s view. 100 million is far beyond what can be hand-designed by humans. The structure has shifted from defining domain tasks and feeding them into the model to letting the model itself generate tasks while humans curate them. When examining the performance gap between the 36B-A4B and the 7B, the distribution of these 100 million tasks becomes the decisive variable.
MoVA: A Second MoE Scaling Axis Built on Attention
Among the K2 Horizon lineup, the 36B-A4B applies MoVA (Mixture-of-Value Attention). If MoE created a scaling axis by routing experts in the feed-forward layer, MoVA integrates routing into multi-head attention itself, adding a second scaling axis along the attention dimension. It is compatible with FlashAttention, GQA, and sparse attention, so it can be used without significantly overhauling existing serving stacks.
What makes MoVA interesting is that it can push MoE’s parameter efficiency a step further. Whether the upper K2 Horizon lineup converges entirely on MoVA, or dense and MoVA coexist, is a point to watch.
Tool-Calling Format: Markdown’s 18.5% Token-Efficiency Edge
IFM trained tool definitions in three formats—JSON, XML, and Markdown—and set Markdown as the default for inference. Measurement results show that Markdown uses approximately 18.5% fewer tokens than JSON. Producing the same result with fewer tokens translates directly into lower latency and cost.
The Markdown advantage grows as tool definitions get longer. Agents that expose 30 to 50 tools simultaneously are common, and in those cases, 18.5% is not a simple optimization but a near architectural decision. When designing a tool-calling system with K2 Horizon, it is simpler to let the model read and call Markdown tool definitions directly rather than building a separate router.
Serving Ecosystem: Day-0 Support for vLLM, SGLang, and Ollama
On the day of release, vLLM, SGLang, and Ollama received day-0 support, with FP8 and GGUF builds also provided. The supported range extends beyond NVIDIA to include AMD and Cerebras. According to the official IFM announcement, hosting is split across Compass, Cerebras, and Nebius APIs, plus the platform.ifm.ai gateway, so the same weights can be tested immediately on various stacks. Deployment-infrastructure choice is worth evaluating from the perspective of data-movement costs by AI chip architecture.
Day-0 serving support is a “signal” from the announcement. New models typically stabilize only after community patches, but K2 Horizon works on three inference engines at the moment of release. This shows IFM’s strategic choice to ship open-source models as a “stack.”
Practical Application Points
Size selection depends on call frequency and acceptable response latency. The 0.9B and 3.7B are efficient for classification, routing, and simple transformations; the 7B fits general-purpose reasoning; and the 32B is best for high-quality generation and summarization, where resource-to-output ratio matters. The 36B-A4B is well suited to agent routers or multi-tool-call workloads, leveraging its 4B active parameters per token. The 375B-A23B carries a significant operational cost, so the safer approach is to validate prompts and tool shapes on the 0.9B first, then scale up gradually.
What to Try Right Now
- Download the K2 Horizon 0.9B or 3.7B weights from Hugging Face and spin up a local vLLM server.
- Write the same tool definition in both JSON and Markdown, and compare token counts and response times.
- Pull the 36B-A4B and run at least five multi-tool-calling scenarios with MoVA routing enabled.
- Inspect the synthetic-task distribution in the pretraining-corpus metadata, pick the cluster closest to your in-house domain tasks, and start fine-tuning.
Frequently Asked Questions
Why does the K2 Horizon 0.9B model use a different vocabulary?
It is targeted at edge devices, so the vocabulary was reduced to lower memory usage. It goes through the same training pipeline but adopts a reduced vocabulary tailored to the inference environment.
Can it be commercialized under the Apache 2.0 license?
Because the weights, code, and data are all released under Apache 2.0, it can be used as-is in commercial services. Note, however, that the same license-notice requirement must be followed when redistributing.
How is MoVA different from conventional MoE?
If MoE routes experts in the feed-forward layer, MoVA integrates routing into multi-head attention itself. Its defining feature is compatibility with FlashAttention, GQA, and sparse attention.
Why is Markdown tool calling 18.5% more efficient than JSON?
Markdown uses fewer metacharacters such as braces, quotes, and tags, so fewer tokens are needed to express the same meaning. The advantage grows as tool definitions get longer.
The question K2 Horizon’s release poses is not simply “Is this yet another open-source model launch?” The fact that a fleet running consistently on the same pipeline from 0.9B to 375B has been released under Apache 2.0 shows that the axis of open-source LLM competition is shifting from weights to the “stack”—including data, code, and intermediate states. What licensing standards this change produces, and how commercial vendors respond, will be the deciding factor over the coming quarters.
Reference
This article was written after reviewing the following source: MarkTechPost — IFM Releases K2 Horizon: Six Apache 2.0 Models From 0.9B to 375B