Key Takeaways
- Fable 5.1 and Mythos 5.1 are two deployment variants that share the same base model and differ only in their guardrail layer; they were released on September 1, 2026, three months after the launch of the Fable 5 line
- Fable 5.1 is generally available (GA) under the claude-fable-5-1 identifier on the Claude API, Amazon Bedrock, AWS Claude Platform, Google Cloud, and Microsoft Foundry, while Mythos 5.1 is restricted to verified U.S. organizations under Project Glasswing
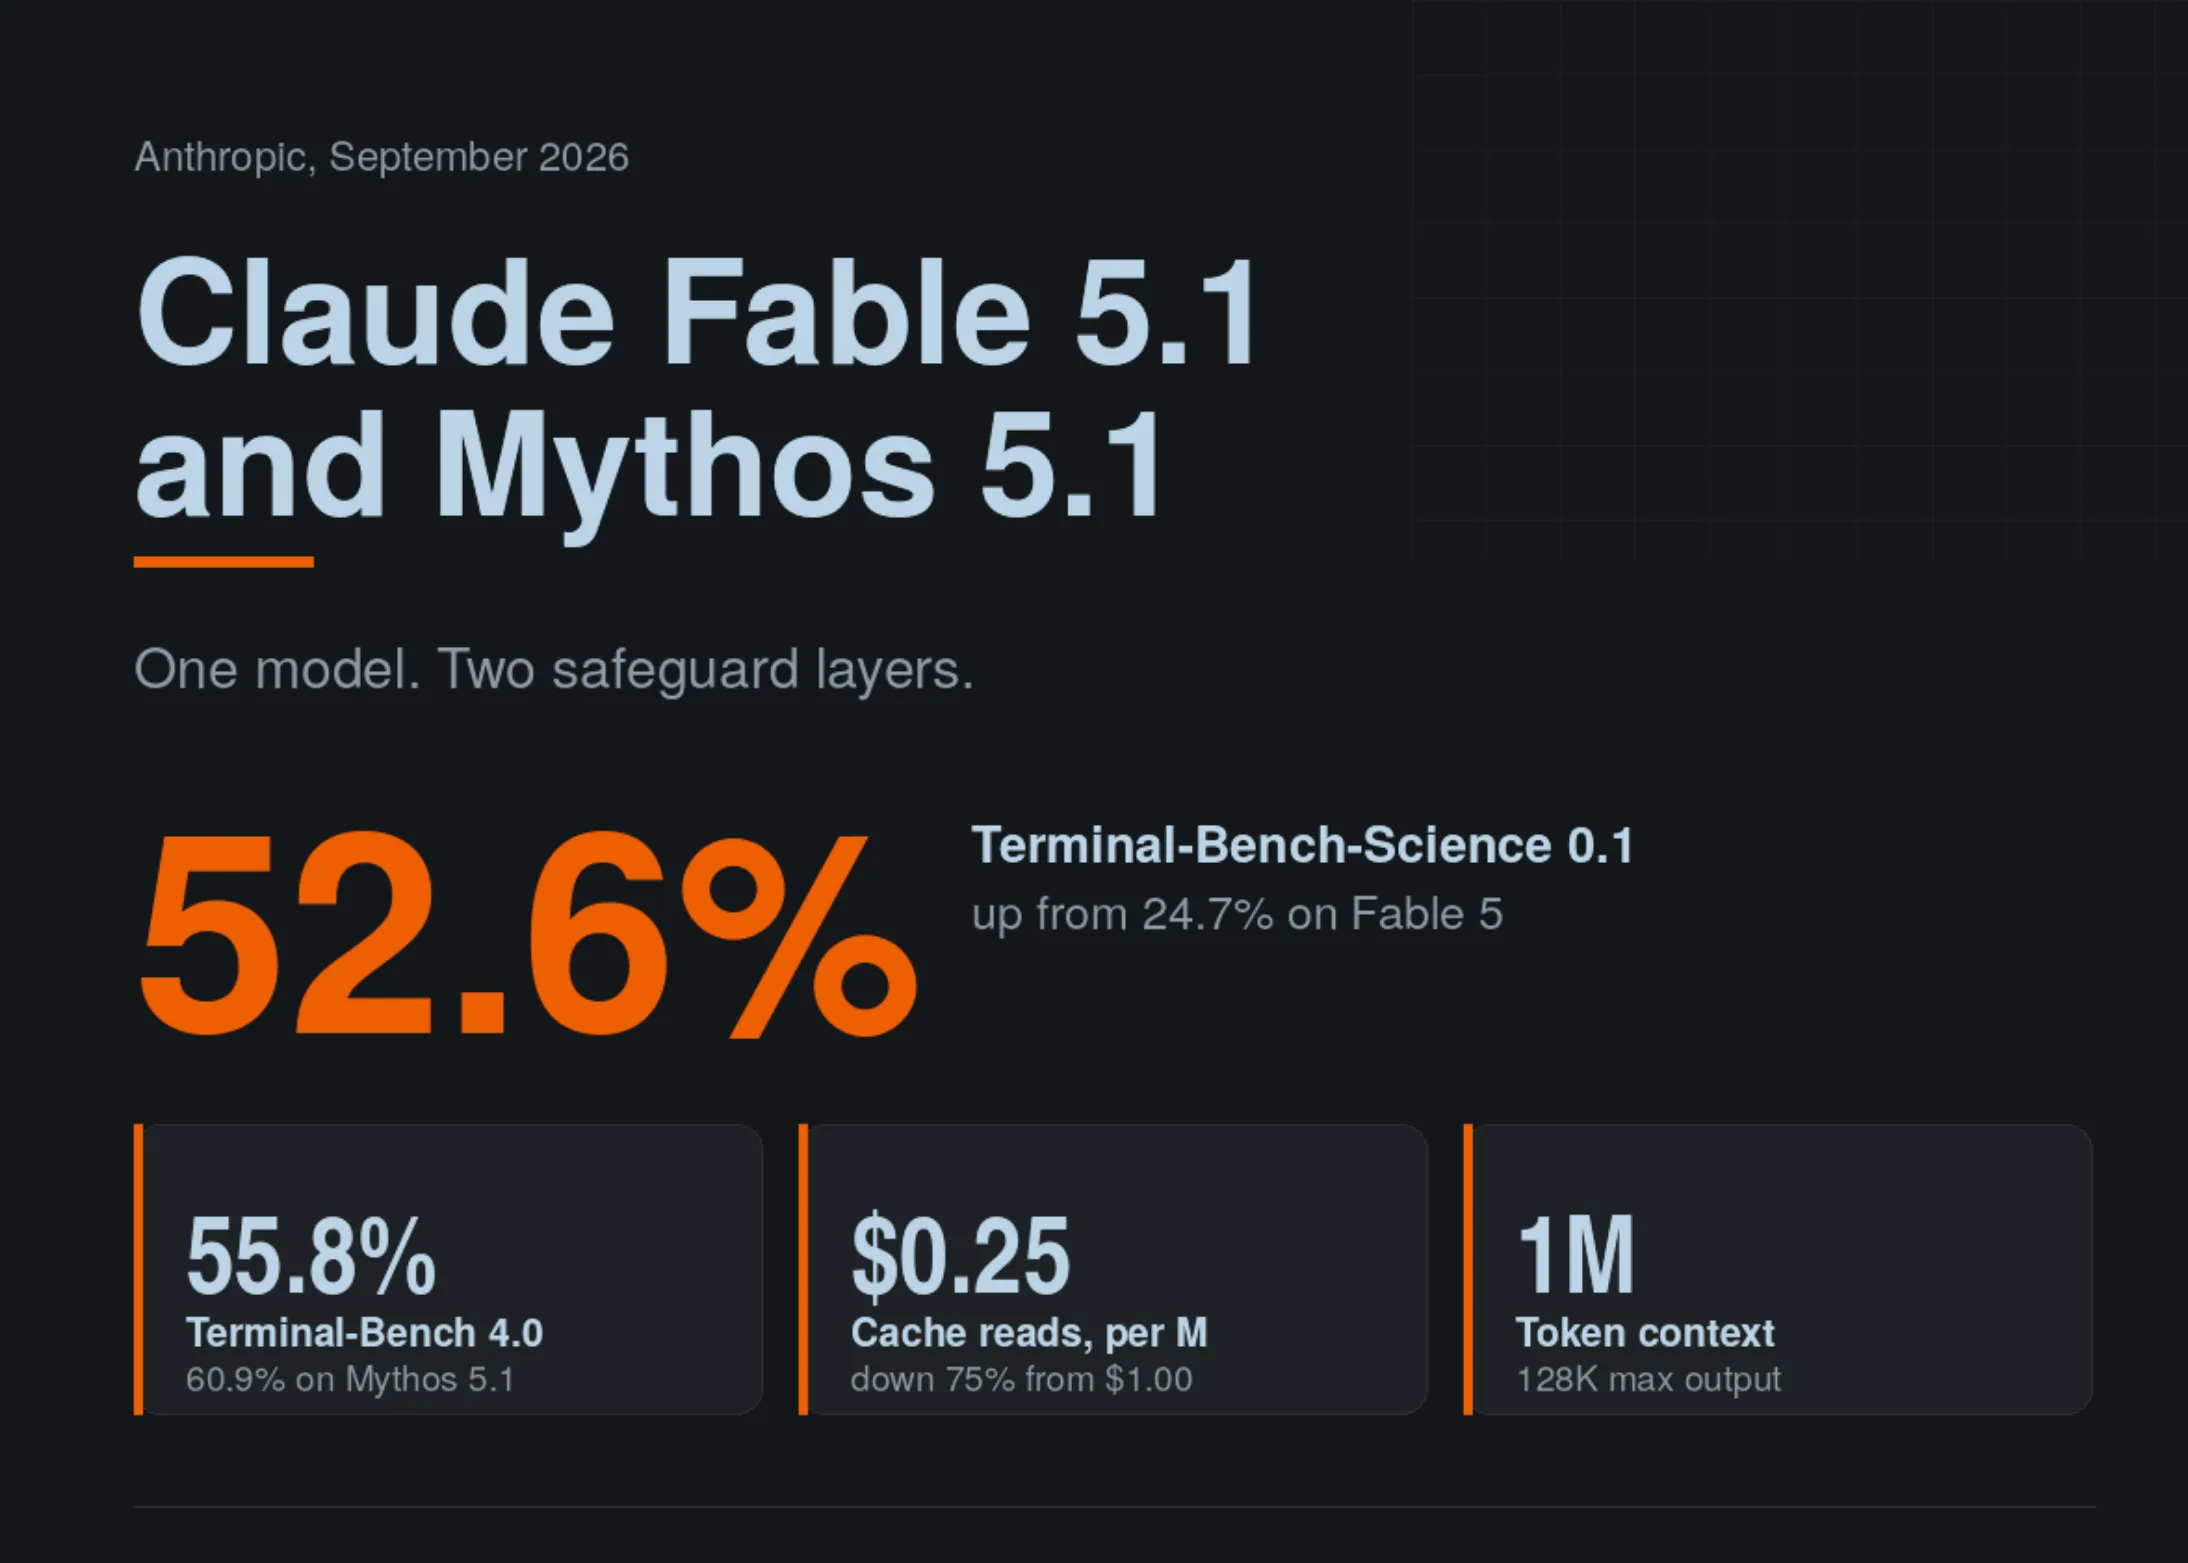
- Both models share the same core specifications: a 1M token context window, a 128K maximum output token count, and always-on adaptive thinking
Analytical — an article that unpacks the strategic implications of a single-model, dual-guardrail release structure and quantifies how the simultaneous jump in science benchmark scores and cut in cache pricing reshape the price-to-performance equation
Table of Contents
- Key Takeaways
- The Release Structure of the Claude 5.1 Lineup — Same Model, Different Gates
- Claude 5.1 Specifications — 1M Context, 128K Output, Always-On Adaptive Thinking
- Science Benchmark Jump — 52.6% on Terminal-Bench-Science 0.1
- The Gap Within the Same Model Revealed by Terminal-Bench 4.0
- Supplementary Benchmarks for Claude 5.1 — Five Figures at a Glance
The Claude 5.1 lineup was released on September 1, 2026 — exactly three months after Fable 5. On the same day, Anthropic launched two models simultaneously: Claude Fable 5.1 and Claude Mythos 5.1. The base model is identical, and the dual deployment differs only in the guardrail layer.
I see this structure itself as the most important signal. Releasing a model that disrupts both performance and pricing through two separate channels is a strategy aimed at capturing market share and governance control in a single move.
The Release Structure of the Claude 5.1 Lineup — Same Model, Different Gates
The two models share the claude-fable-5-1 identifier. The difference lies in the distribution channel.
Fable 5.1 is generally available on the Claude API, Amazon Bedrock, AWS Claude Platform, Google Cloud, and Microsoft Foundry. Mythos 5.1 is restricted to verified U.S. organizations under Project Glasswing. General developers are unlikely to encounter the Mythos 5.1 identifier in the API console.
Claude 5.1 Specifications — 1M Context, 128K Output, Always-On Adaptive Thinking
Both deployments share the following specifications.
- 1M token context window
- 128K maximum output tokens
- Always-on adaptive thinking
The fact that there is no difference in core compute specifications aligns with the announcement’s claim that only the guardrail layer differs on the same base model.
Science Benchmark Jump — 52.6% on Terminal-Bench-Science 0.1
Among the figures published by Anthropic, the most meaningful for practitioners is the Terminal-Bench-Science 0.1 score. On this benchmark, which evaluates agentic scientific research, Fable 5.1 recorded 52.6%.
| Model | Terminal-Bench-Science 0.1 |
|---|---|
| Claude Fable 5.1 | 52.6% |
| Claude Opus 5 | 29.0% |
| Claude Fable 5 | 24.7% |
| GPT-5.6 Sol | 22.4% |
The gap is 27.9 points over Fable 5 and 23.6 points over Opus 5. A standard error of 3.5 to 4.5 points was published alongside. Narrow gaps like the 2.3-point difference between Fable 5 and GPT-5.6 Sol mean that superiority should not be judged on a single benchmark score alone.
The Gap Within the Same Model Revealed by Terminal-Bench 4.0
An interesting figure is the Terminal-Bench 4.0 score. Although the base model is the same, scores diverge depending on whether the guardrail is applied.
Fable 5.1 at 55.8%, Mythos 5.1 at 60.9%. The difference is 5.1 points. Based on materials published by Anthropic, this is analyzed as the result of deploying the same model with only a different guardrail layer. Further disclosure is needed to determine which guardrail pulls the score down.
Supplementary Benchmarks for Claude 5.1 — Five Figures at a Glance
Here are the figures released beyond the science benchmark.
| Benchmark | Fable 5.1 Score |
|---|---|
| CursorBench 3.2.0 | 73.4% |
| Humanity’s Last Exam (no tools) | 60.9% |
| Humanity’s Last Exam (with tools) | 65.0% |
| AutomationBench | 31.4% |
| OSWorld 2.0 strict | 41.7% |
| GDPval-AA v2 | 1853 |
AutomationBench at 31.4% and OSWorld 2.0 strict at 41.7% were not published with comparable baselines, so there is insufficient information to judge their relative standing.
Claude 5.1 Pricing — Base Rates Frozen, Cache Cut 75%
The pricing is summarized as follows.
- Base input: $10 per million tokens (unchanged)
- Base output: $50 per million tokens (unchanged)
- Cache read: $1.00 → $0.25 per million tokens (75% cut)
Cache read pricing is now 0.025x of the base input price. Compared to the 0.1x ratio used by other Claude models, this is one-quarter the level, meaning the cache-to-input ratio has been cut deeper from 0.1x down to 0.025x.
The Cost Impact of Claude 5.1
Taking Anthropic’s own measurements at face value: approximately 25% savings on general workloads, and up to roughly 45% savings on context-heavy agentic workloads. Since cache hit rates vary by workload, the most effective approach is to directly measure your own traffic’s cache hit rate.
What the Two Deployments of the Same Model Signal
The dual-gate strategy is more than a simple channel split. It broadens market reach for general customers through Fable 5.1, while absorbing governance requirements for customers with stricter control needs through Mythos 5.1. The intent is to satisfy both price-performance advantage and policy requirements by sending one model out through two paths. The September 1 MarkTechPost report and the official Anthropic announcement are the sources for this simultaneous release.
Summary of Issues
- The single-model, dual-guardrail structure has set a new reference point for the price-performance-control balance
- The 52.6% on Terminal-Bench-Science 0.1 leaves an open question of how much of a real gap exists over Opus 5 within the 3.5 to 4.5 point standard error window
- The 0.025x cache read ratio creates a 4x gap versus the 0.1x of other models, foreshadowing significant market ripple effects
What to Try Right Now
- Measure the cache hit rate of your current Claude API traffic from CloudWatch and OpenTelemetry logs, and map the 25 to 45% savings to your own workload
- Review the eligibility requirements of Project Glasswing to determine whether you can access Mythos 5.1
- Redesign your prompt structure to expand cache hit regions in RAG pipelines that leverage the 1M token context
- Build a science evaluation set tailored to your domain to compare scores before and after adopting Fable 5.1
- Simulate whether the 23.6-point gap can be recovered cost-effectively when migrating from Opus 5 to Claude 5.1
Frequently Asked Questions
What is the difference between Claude 5.1 and Fable 5?
Claude 5.1 is a line released three months after Fable 5, jumping from 24.7% to 52.6% on Terminal-Bench-Science 0.1 and cutting cache read pricing by 75%. The base model is identical, and the line is split into two deployments that differ only in the guardrail layer.
Can general developers use Claude Mythos 5.1?
No. Mythos 5.1 is restricted to verified U.S. organizations under Project Glasswing. Only Fable 5.1 is generally available on the Claude API, Bedrock, Claude Platform, Google Cloud, and Microsoft Foundry.
How much does the cache read price cut actually affect real-world cost?
According to Anthropic’s measurements, savings reach approximately 25% on general workloads and up to roughly 45% on context-heavy agentic workloads. Actual savings vary depending on your traffic’s cache hit rate.
Why is the same model deployed with only different guardrails?
This is analyzed as a dual-gate strategy aimed at broadening market reach for general customers through Fable 5.1, while absorbing governance requirements for customers with stricter control needs through Mythos 5.1. The roughly 5.1-point gap on Terminal-Bench 4.0 (55.8% vs. 60.9%) illustrates the cost of this strategy.
Reference Source
This article was written after reviewing the following original source: MarkTechPost — Anthropic Releases Claude Fable 5.1 and Claude Mythos 5.1: 52.6% on Terminal-Bench-Science and 75% Cheaper Cache Reads